Chapter 4 — Finding Hidden Groups — Clustering Methods
From similarity to useful customer segments
Prof. Xuhu Wan
What This Chapter Covers
Problem: we have customer records, but nobody has already told us which buying-pattern group each customer belongs to.
Example 1 — a wholesale distributor. We have 440 customers and each customer’s annual spending on six product categories. The sales manager asks: “Do some customers buy similar combinations of products, so we could test a different bundle for each group?”
The table records amounts spent, but has no ready-made buying-pattern segment for each customer. Channel tells us whether a customer is retail or a hotel/restaurant/café; it does not tell us these spending-based groups.
Example 2 — a mall (simulated customer data). We have customers’ annual income and spending scores. The marketing manager asks: “Can we find groups with similar income and spending patterns before trying different promotions?”
There is no supplied label such as “higher income, lower spending score.” We first find groups from the features, then describe what each group looks like.
In this chapter: choose features → measure similarity → form groups → understand the groups → propose an action to test. The group labels are an output of clustering, not an answer column supplied at the start.
Chapter Roadmap
Section
Business task
1
Define the grouping question and choose features
2
Measure distance and standardise features
3
Understand and run K-means
4
Compare plausible K values and check limitations
5
Profile customers and propose business actions
6 (Optional)
Read a hierarchical tree — not covered in the final exam
§1 — Business Groups, Simple Rules, and Features
Define why a group would be useful before asking an algorithm to create one.
The Distributor’s Question
Business question: which wholesale customers have similar buying patterns, so the distributor can plan suitable product bundles?
One row = one customer’s annual spending record. The table contains 440 customers. A row summarises a whole year; it is not one shopping transaction or a count of items.
Customer location: 1 = Lisbon; 2 = Porto (Oporto); 3 = other regions
Fresh, Milk, Grocery, Frozen
Annual spending on fresh products, milk products, groceries and frozen products
Detergents_Paper, Delicassen
Annual spending on detergents/paper products and delicatessen products
The six spending columns use monetary units (m.u.); the source does not specify a currency. Channel and Region are category codes, not spending amounts or ordered scores.
Read the first row: Channel = 2 and Region = 3 identify a retail customer in another region. Fresh = 12,669 means annual fresh-product spending of 12,669 m.u. The preview shows four of the eight columns.
Clustering Has No Response Y
Chapter 3 regression uses an outcome Y and predictors X. Clustering uses selected features X to form groups without fitting a known outcome. The resulting cluster numbers are created by the algorithm.
Start with a Simple Business Rule
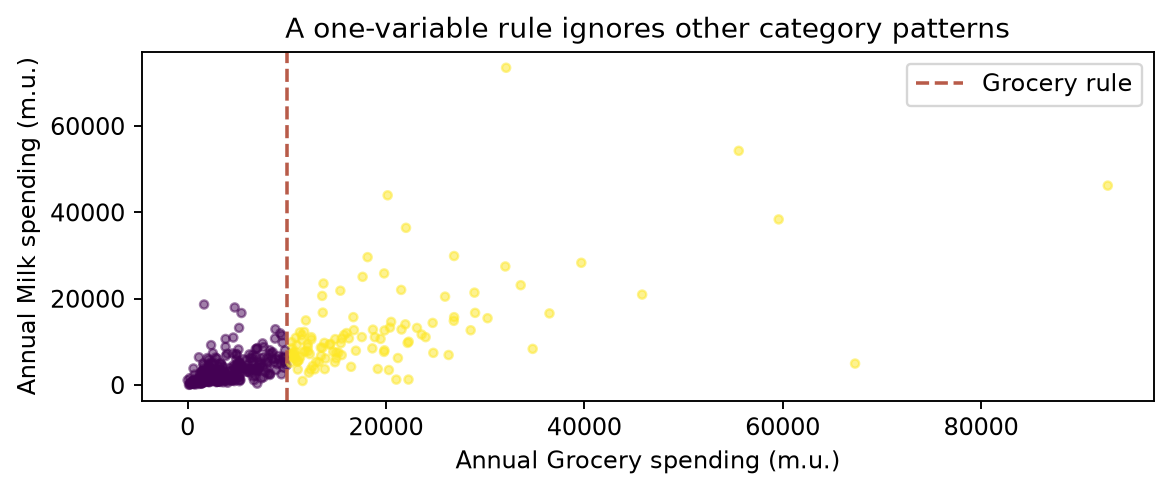
A simple business rule separates customers whose annual Grocery spending is at least 10,000 monetary units (m.u.) from the others. m.u. means monetary units: the dataset does not specify a currency, so this is not an asserted HKD or USD amount. The rule uses one spending variable and a chosen cutoff; it may miss other purchase patterns.
Render the Rule’s Boundary
The vertical line is the chosen Grocery cutoff. Customers with very different Milk spending can be placed together by this one-variable rule. Change the cutoff to see how membership changes.
Choose Features That Define Similarity
Step 1 — choose what counts as similar. Use the six annual spending columns. Exclude identifiers, Channel, Region and earlier Cluster labels.
Step 2 — put those features on comparable scales.StandardScaler() creates a scaling tool; scaler.fit_transform(wholesale[features]) learns each column’s mean and standard deviation, then standardises its values. The result X is the numerical input for clustering.
Why? Distance-based clustering can be dominated by columns with larger numerical spreads—even when all columns use the same currency. Standardisation measures each gap in standard-deviation units. The next two slides show how.
StandardScaler: One Calculation, Column by Column
Example: four customers have Income = [40,000, 60,000, 40,000, 60,000] and Score = [40, 40, 60, 60].
\[z=\frac{x-\text{column mean}}{\text{column standard deviation}}\]
Feature
Mean
SD used by the scaler
Example after scaling
Annual Income (m.u.)
50,000
10,000
60,000 → (60,000 − 50,000) / 10,000 = 1
Spending Score (points)
50
10
40 → (40 − 50) / 10 = −1
Read the new values: 0 = at the column mean; +1 = one SD above; −1 = one SD below. Each varying column now has mean 0 and SD 1. These are unit-free values, not percentages or values restricted to 0–1.
Why Scaling Changes Who Looks Close
Compare A = (40,000, 40) with B = (60,000, 40) and C = (40,000, 60). Use the column standard deviations from the previous example.
The point: K-means uses distances to assign customers to groups. Rescaling can change these distances and therefore the groups. In ISOM2600, always standardise the selected features with StandardScaler before fitting clustering models. This measures gaps relative to each feature’s spread; the business question still determines which features to include.
The Clustering Workflow
Define the business question → select features and inspect records → standardise features → choose K for K-means → fit, inspect and profile groups → test business actions.
Check whether the groups are distinct, stable and useful; revisit earlier choices when needed. A clustering result alone does not prove there are meaningful customer segments.
For K-means: specify the number of groups K before each fit. To compare K=3 and K=4, run the algorithm separately for each choice.
In-Class Practice: Improve the Rule
Try a Grocery cutoff of 8,000. Count both groups and compare their average Milk spending. Explain which feature the rule still ignores.
§2 — Distance Measures and Standardisation
Calculate distances and standardise selected features before clustering.
Why Clustering Needs a Distance
To group similar customers, we need a numerical way to compare them. A distance converts differences in the selected features into one number: smaller means more similar under those features and scales.
For the example customer coordinates A=(1,1), B=(4,5), C=(1,2), Euclidean distance gives A–B=5 and A–C=1. C is closer to A than B is.
How clustering uses this number: K-means compares each customer with current centres; hierarchical clustering starts with customer-pair distances and uses a linkage rule to compare groups.
Changing the features or their scales can change who looks close. The next slide shows how to calculate the distance.
Euclidean Distance: A Straight-Line Gap
A and B are two customers; each customer has two features. These are illustrative feature values on comparable scales.
Customer
Feature 1 (horizontal axis)
Feature 2 (vertical axis)
A
1
1
B
4
5
Thus A = (1, 1) and B = (4, 5). Each pair lists one customer’s Feature 1 and Feature 2 values.
Square the difference in each feature, add the squared differences, then take the square root. With more features, include one squared difference for every feature.
A Customer Distance Illustration
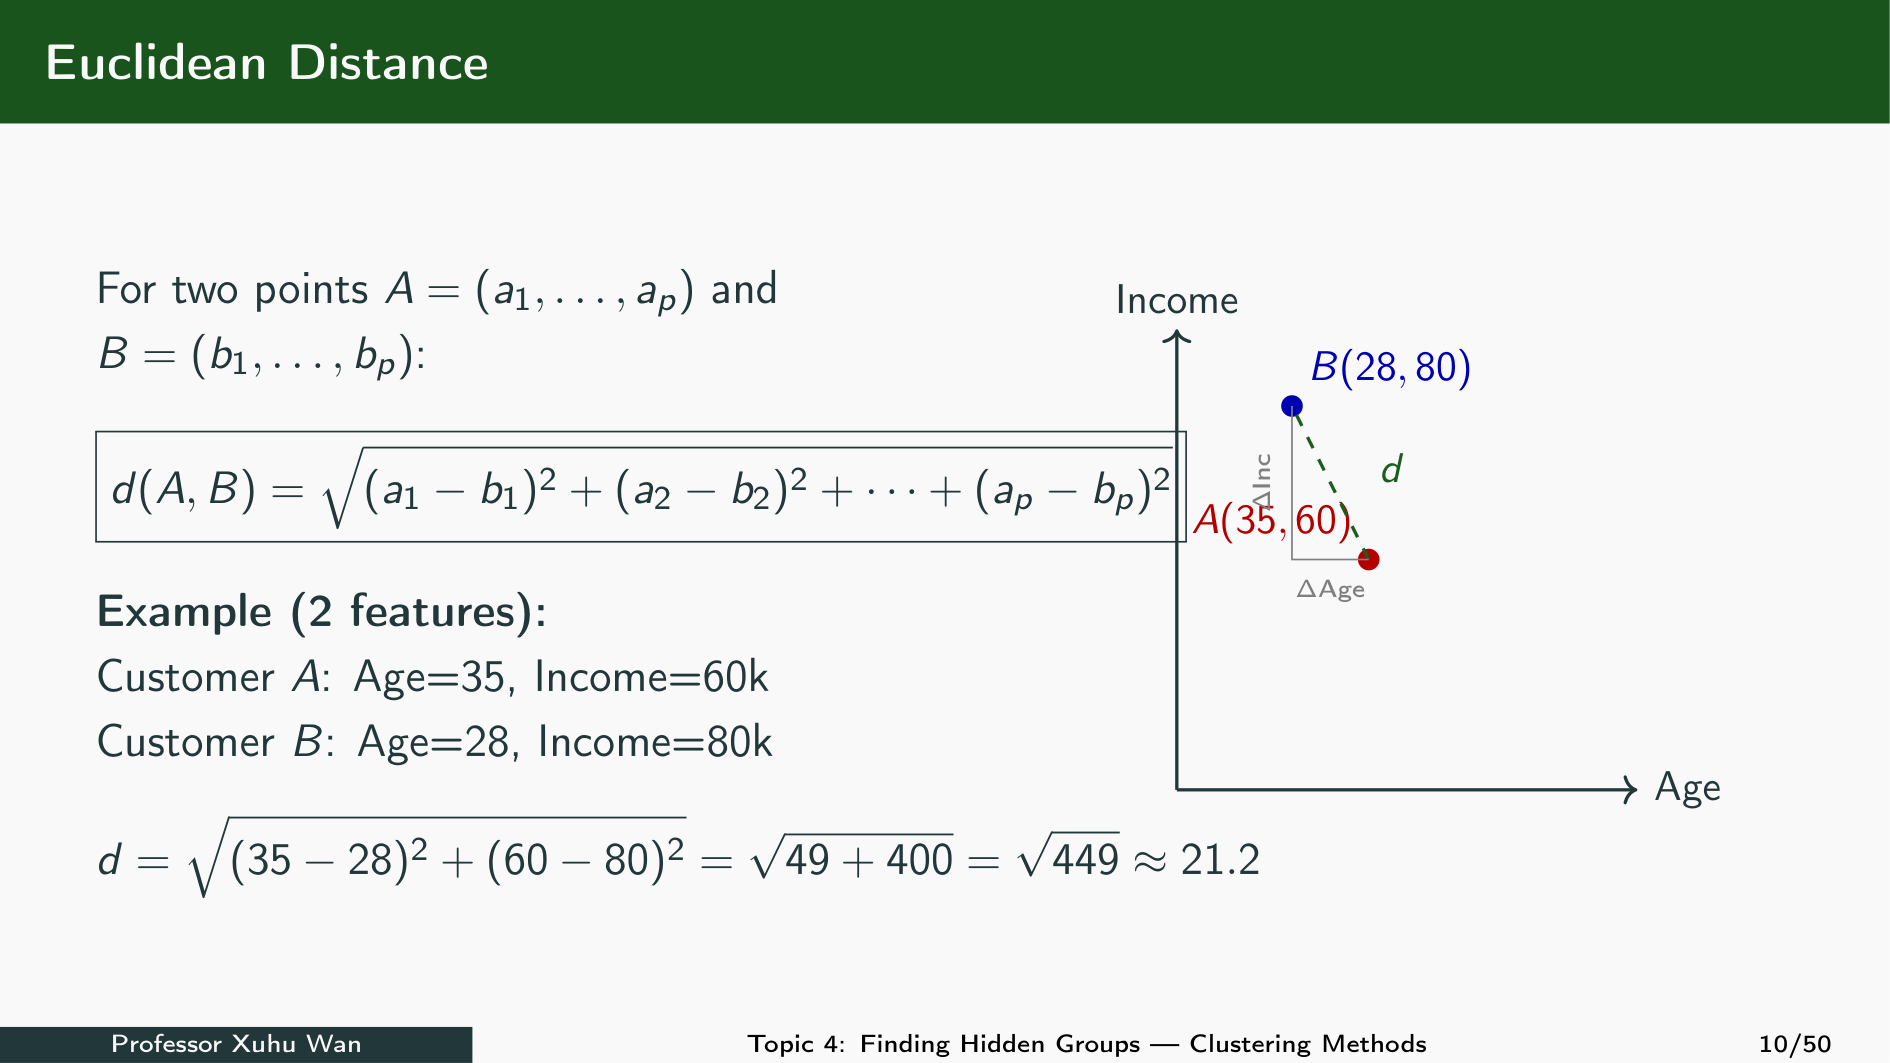
Consider two customers described by Age (years) and Income (thousands of monetary units): A=(35,60) and B=(28,80). The right triangle shows coordinate gaps of 7 years and 20 thousand monetary units. The raw Euclidean distance is about 21.19 in this mixed-unit feature space.
Manhattan Distance: Add Absolute Gaps
Return to A=(1,1) and B=(4,5) from our first distance example. Manhattan distance adds the absolute coordinate gaps: |4−1|+|5−1|=3+4=7, compared with Euclidean distance 5. Distance choice matters. Standard K-means optimises squared Euclidean distances; changing to Manhattan is not merely a KMeans parameter choice.
A Larger Numerical Scale Can Dominate
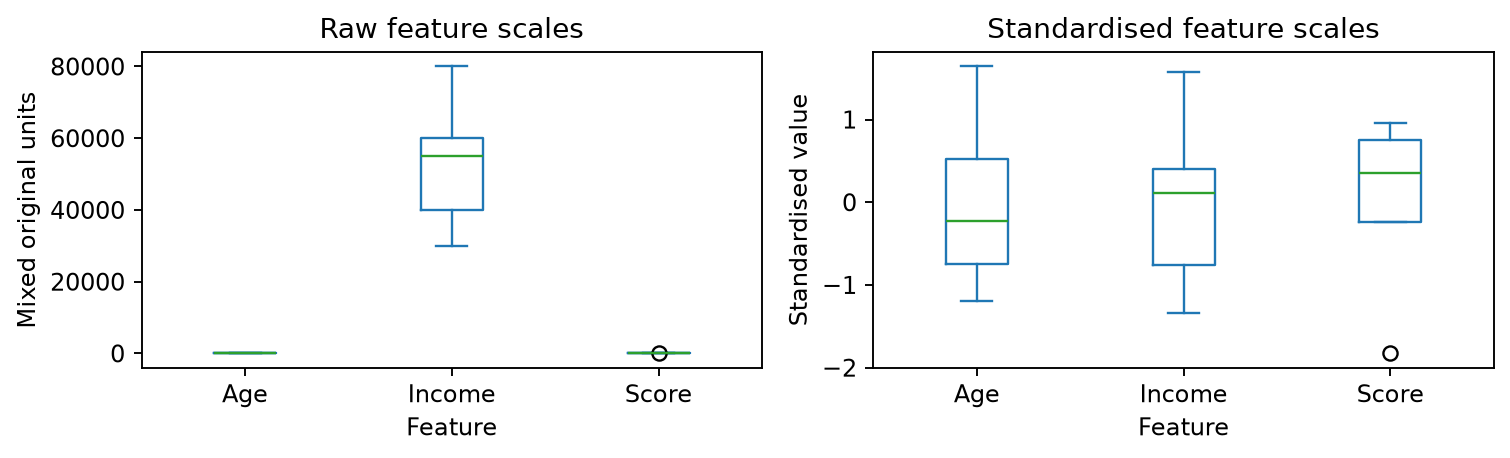
Income is in currency units; Age is years; Score is an illustrative spending score from 1 to 100. The Income difference dominates a raw distance even if we want all three features to matter.
StandardScaler: Centre and Scale Each Feature
For each feature, subtract its mean and divide by its standard deviation:
Why divide by n, not n − 1? Here we are rescaling the observed data, not estimating an unknown population variance. Using n makes the standardised column’s mean 0 and its SD 1 when checked with the same ddof=0 convention.
Statistics: sample variance uses n − 1 to correct bias when estimating population variance from a random sample.
Preprocessing:StandardScaler uses n as its scaling convention. This does not mean our customers are the entire population.
In pandas:.std() defaults to ddof=1; use .std(ddof=0) when checking StandardScaler.
fit_transform learns each column’s mean and scale, then transforms its values.
Scaler Attributes and Methods
scaler.mean_ and scaler.scale_ are fitted attributes. .fit_transform(...), .transform(...), and .inverse_transform(...) are methods. The trailing underscore convention marks values learned during fitting.
Render Before and After Scaling
The left panel shows the very different raw numerical ranges; the right panel shows standardised values. In ISOM2600, use the standardised features for clustering. Scaling does not make every feature equally useful.
Interactive Distance: Before and After Standardisation
Compare A–B with A–C before and after standardisation. The raw calculation is a diagnostic showing how numerical scales can dominate distance. For clustering in ISOM2600, use the standardised features.
Calculate Distances After Standardisation
Use the same formula on the standardised rows. A “closer” customer is closer under the selected features and scaling, not universally more similar.
Transform New Records with the Fitted Scaler
.transform() uses the existing means and scales. Fitting a new scaler on each new customer would destroy comparability. Use .inverse_transform() to recover centroids in business units.
In-Class Practice: Check the SD Convention
Print standardised means, .std(), and .std(ddof=0). Explain why the two SD outputs differ even though the scaling worked correctly.
§3 — K-Means: Assign, Average, Repeat
Understand the steps with six points before fitting the larger customer table.
A Centroid Is a Coordinate-Wise Mean
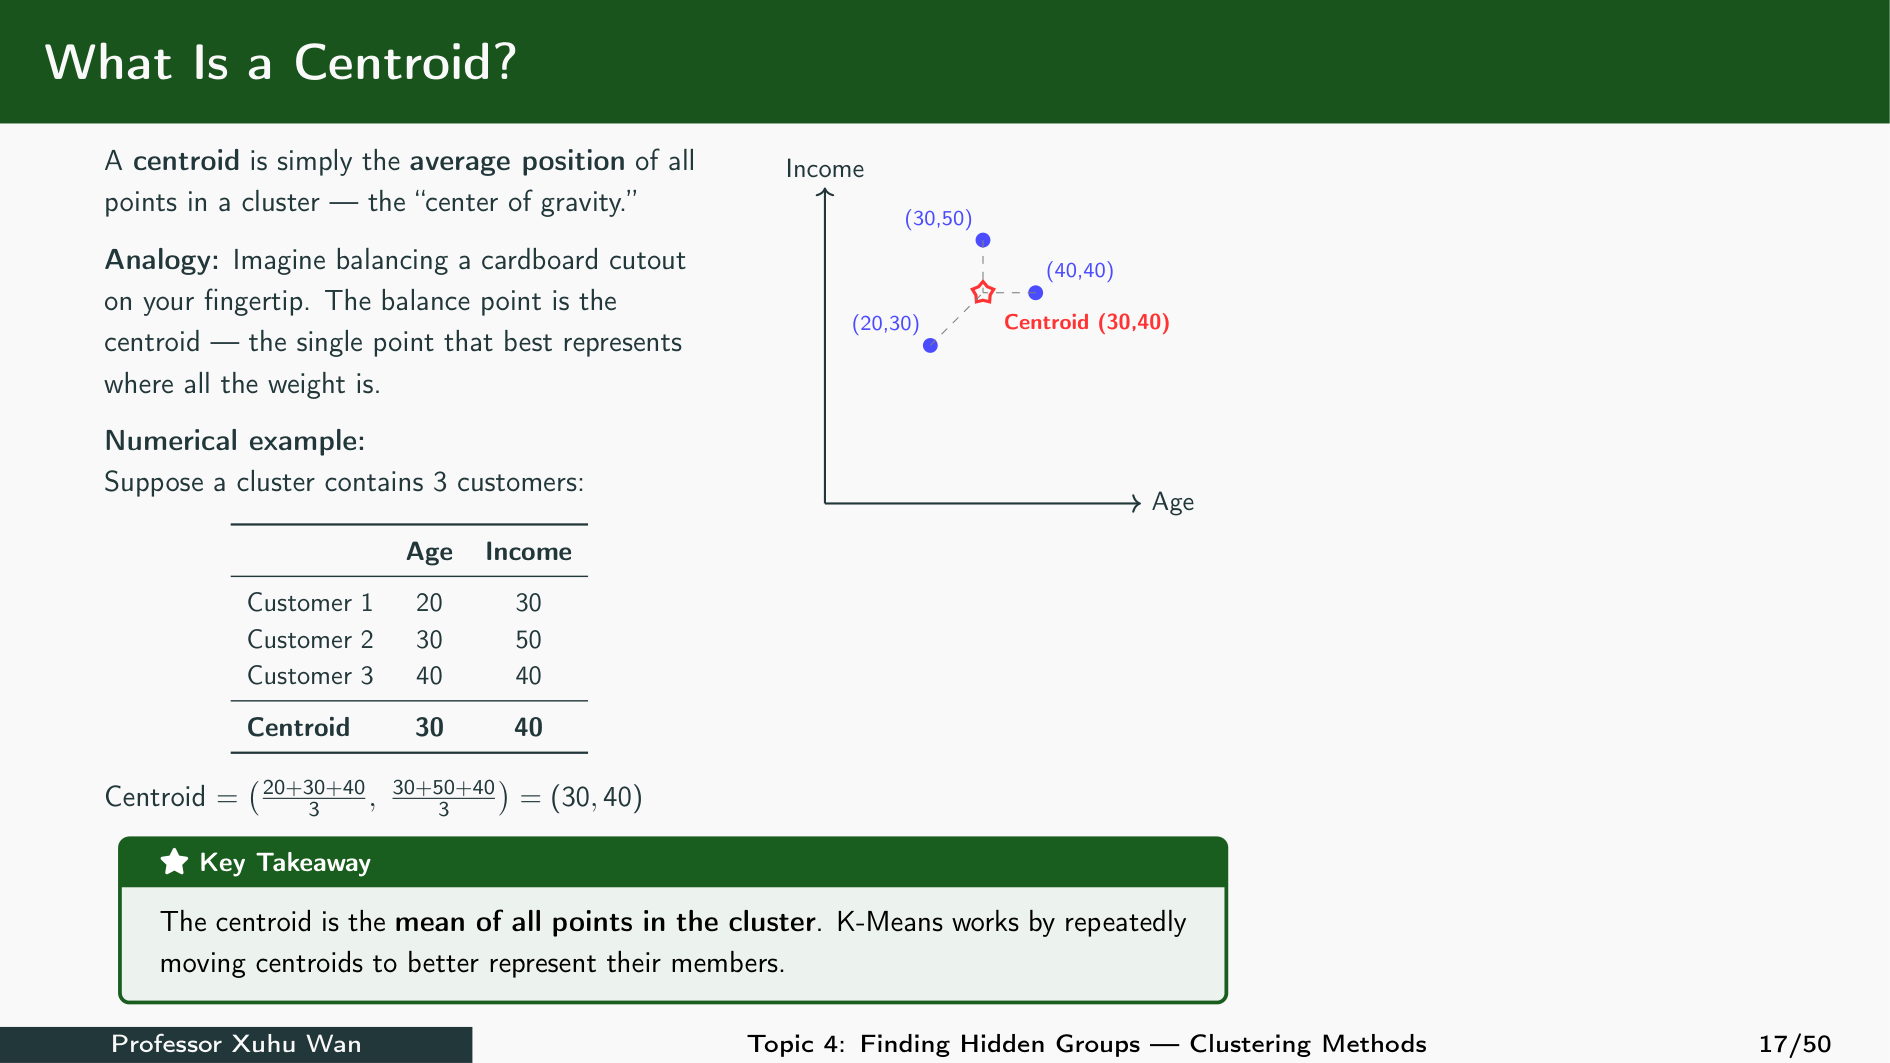
For three points shown in prepared illustrative coordinates, (20,30), (30,50), and (40,40), the centroid is (30,40). It need not be an observed customer. A centroid is the coordinate-wise mean; Python clustering fits use standardised features.
The K-Means Algorithm
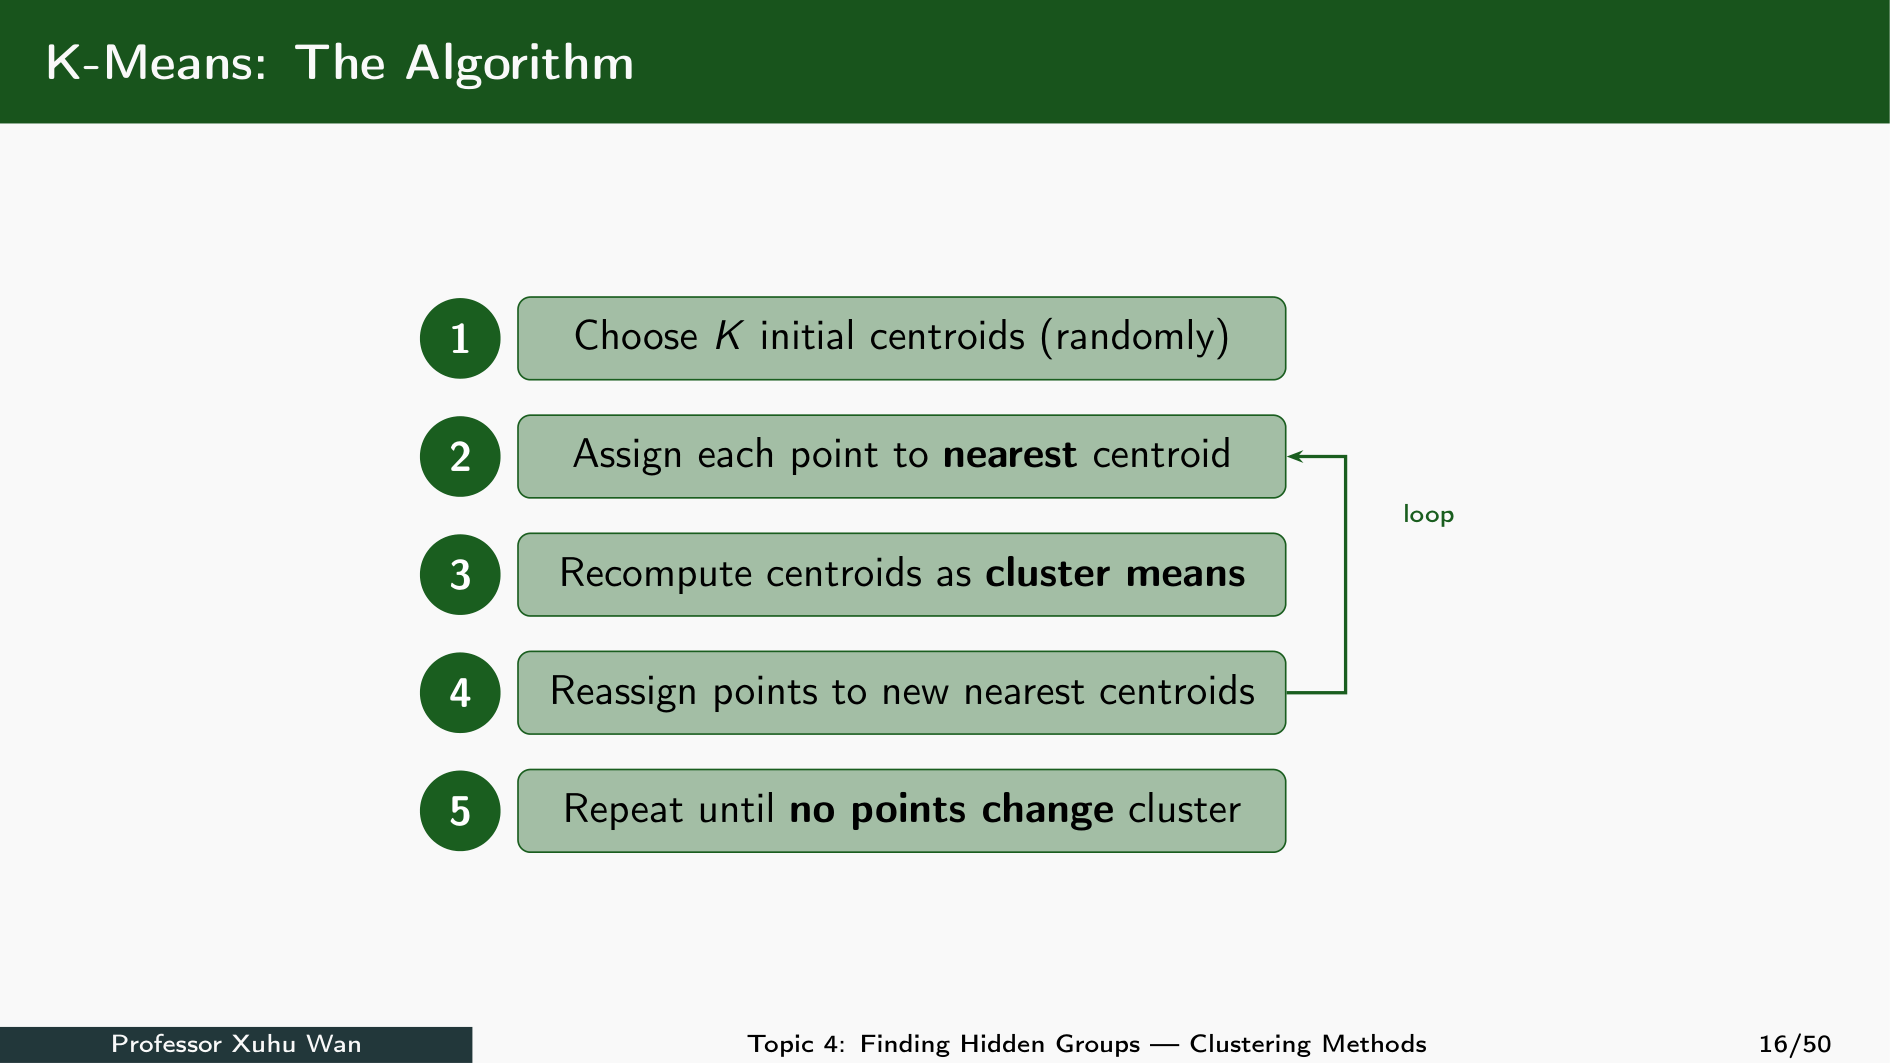
The final centroids are not known at the start. To find a group mean, we need to know its members; to assign members, we need centres. K-means solves this by repeating two operations: assign customers → recompute group means.
This is an iterative algorithm: new centres lead to new assignments, which lead to new centres. Keep K fixed during one fit. Follow the loop in the original lecture diagram, then work through the four illustrated steps below.
Manual diagrams use prepared schematic coordinates to show the algorithm. Python model fits always standardise the input features first.
K-Means Step 1: Choose Initial Centroids
Choose K=2 first. Each dot is a customer with two features. Start with centre 0 at A=(1,1) and centre 1 at C=(2,1). The grey customers have not yet been assigned.
These are starting guesses, not the final group means. We deliberately start both centres in the lower-left cloud so we can see why repeated updating is necessary. The software can choose starting centres automatically; here we set them for illustration.
K-Means Step 2: Assign to the Nearest Centroid
Keep the centres fixed while assigning all customers. Compare each customer’s distance to both centres. Colour the customer according to the nearer centre.
The first assignment is A,B → group 0 and C,D,E,F → group 1. C is at centre 1, so its distance to that centre is zero.
Do not move a centre after assigning just one customer. Finish this assignment step first; then compute both group means.
K-Means Step 3: Recompute the Centroids
Keep memberships fixed and average each feature within each group. The hollow circles mark the old centres; arrows point to the new means. Customer dots stay where they are.
Moving a centre can change which centre is closest. With the updated centres, C is 1.118 from centre 0 and 6.374 from centre 1. C therefore switches from group 1 to group 0 (outlined in gold).
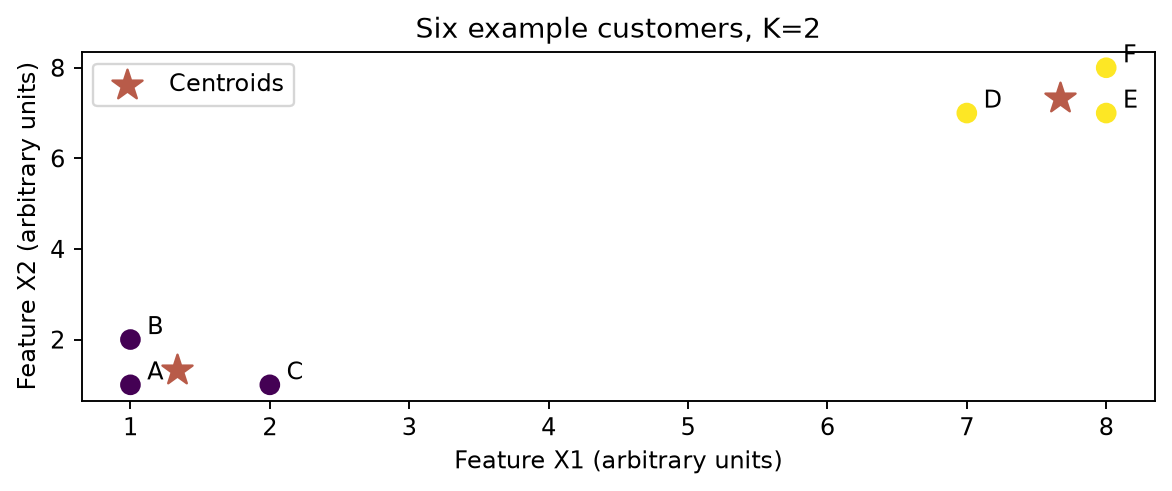
Compute the means again: A,B,C now give centre 0=(1.333,1.333); D,E,F give centre 1=(7.667,7.333). The centre update from Step 3 was not the final answer.
Check the assignments once more. Here nobody switches, so another mean calculation would give the same centres: stop. Other datasets may need more rounds.
For any assignment step, compare distances to every current centre. Use the same feature scales as the clustering fit. The point joins the nearest centre; cluster numbers only name groups.
The following Python calculation is a separate distance example with P=(2,1), centre 0=(1,1) and centre 1=(8,8). Squared distances are 1 and 85, so P joins group 0. Squaring preserves which nonnegative distance is smaller.
Compute One Assignment in Python
For point P=(2,1) and centres (1,1) and (8,8), squared distances are 1 and 85. argmin() gives the zero-based position of the smaller value, so P joins cluster 0.
Recompute Each Centre with .loc and .mean()
For this assignment, A/B/C form cluster 0 and D/E/F form cluster 1. Select each cluster separately with .loc, then use .mean() to calculate its coordinate means. Put the two mean rows in a DataFrame: these are the updated centres.
Interactive K-Means: Assign and Update
Press Play stages to watch initial centres → assignments → mean updates → stable assignments. Pause to explain a stage, use Next step to advance manually, or Reset steps to replay. Start with two centres in the same cloud. Watch customer C switch groups after the first update; update again, then check that assignments stay stable.
Fit KMeans in Python
First standardise X1 and X2 with StandardScaler. Create an estimator with K=2, a fixed random seed, and 10 initialisations. .fit_predict(X) fits the model to those standardised coordinates and returns one label per customer. The printed centres are also in standard-deviation units.
KMeans Attributes and Methods
Fitted attributes:.labels_, .cluster_centers_, .inertia_, .n_iter_. Methods:.fit(X), .fit_predict(X), .predict(new_X). Cluster IDs start at 0 in KMeans and are arbitrary labels, not ranks.
Render Fitted Groups and Centres
The model is fitted on standardised features. For this plot, scaler.inverse_transform(...) converts its centres back to the original X1/X2 coordinates, so stars and customer points use the same axes. Colour represents membership, not quality or profitability.
Assign a New Record
.predict() assigns a new point to a fitted centre; it does not update the centres. Transform the new record using the same fitted scaler before prediction. Do not fit a new scaler to it.
In-Class Practice: Explain the Object
Print the shape of .cluster_centers_, count members per cluster, and assign (7.5,7.5) after transforming it with the fitted scaler. Explain which operation would retrain the centres.
§4 — Choosing K and Checking the Result
Compare fit, separation, stability, and business usefulness rather than treating one plot as proof.
WCSS: What Does Each Symbol Mean?
WCSS = Within-Cluster Sum of Squares. Measure how tightly customers sit around their own group centres.
n customers in total; i identifies one customer (one row)
\(p\) and \(j\)
p selected features; j identifies one feature (one column)
\(x_{ij}\)
Customer i’s value of feature j, in the scale used for clustering
\(c_i\)
The cluster assigned to customer i; with KMeans, one of 0, …, K−1
\(\mu_{c_i,j}\)
Feature j of customer i’s assigned centre: the mean in that cluster
\((x_{ij}-\mu_{c_i,j})^2\)
Squared gap for this customer and this feature
\(\sum_j\) then \(\sum_i\)
Add across features for one customer, then across all customers
Only use the assigned centre: do not add distances from a customer to every centre. K is the number of clusters; each customer belongs to one of them.
Calculate WCSS: Square Each Assigned Gap
Within-Cluster Sum of Squares (WCSS) adds the squared distances from customers to their assigned centres. The diagram uses one group and one feature: its centre is 0, and WCSS = 4 + 1 + 9 = 14.
The Python code applies exactly the same rule to our earlier six-customer, two-feature K-means fit. assigned selects the correct centre for each row; subtract, square and sum across all rows and features. The result equals km.inertia_.
Smaller WCSS means more compact groups in the same feature space. Raw and standardised WCSS use different scales, so do not compare their numbers directly. More groups can reduce WCSS without making the segmentation more useful.
Explore the Simulated Mall Customers
The original notebook creates 200 customers with Age, income in thousands of illustrative currency units, and a Spending Score. We retain its records, but omit its known construction labels from the feature table.
Render an Elbow Plot
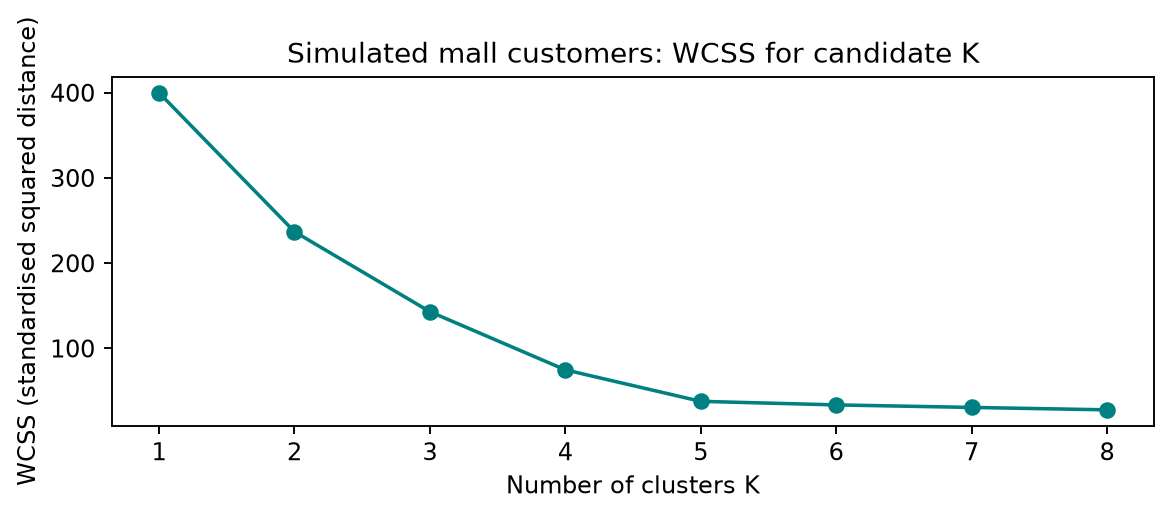
Fit several K values and plot WCSS. A bend suggests diminishing improvement, but may be unclear or suggest several plausible choices. Compare neighbouring K values with business profiles and group sizes.
Interactive K: Compare the Partition
Choose K=2,3,4,5, or 6 for the same standardised mall features. Compare group counts, WCSS, and centre positions in the original units. More colours do not automatically mean a better business segmentation.
Extension: Separation with a Silhouette Score
A silhouette score compares within-group and nearest-other-group distances. Values near +1 suggest separation; near 0 suggest boundary overlap; negative values suggest a point closer to another group. The mean is one diagnostic, not a unique answer for K.
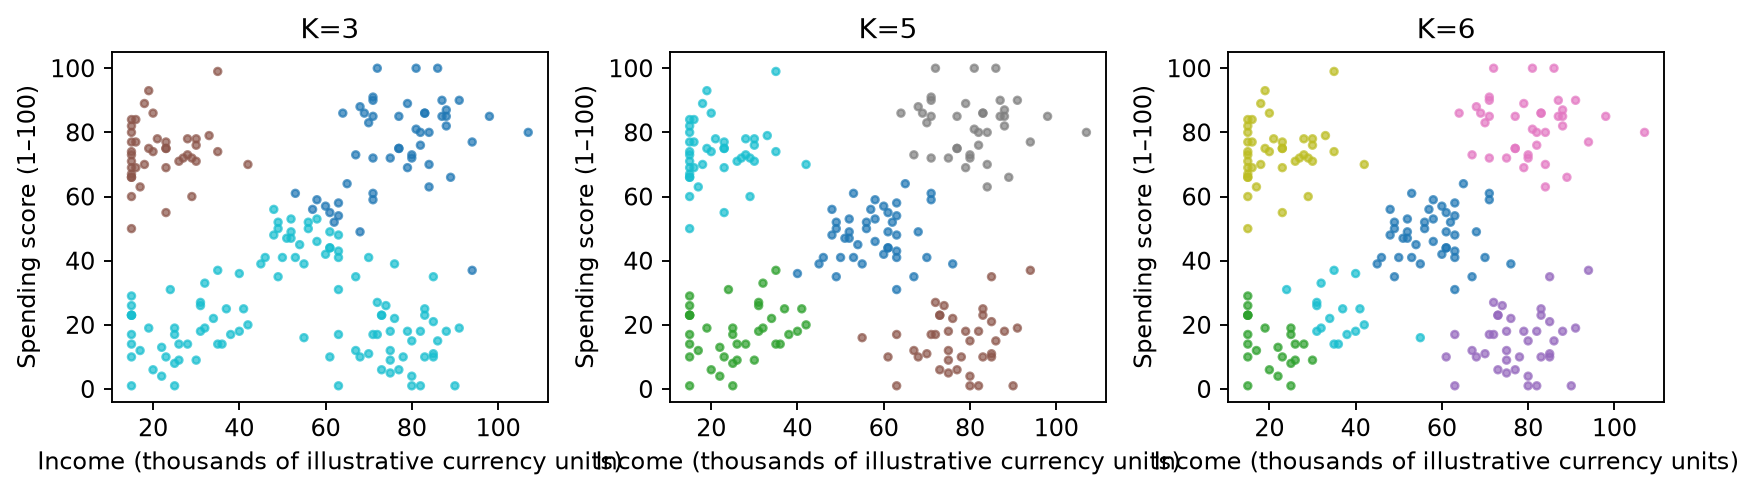
Render Neighbouring Choices
These three fits use the same standardised features and show the original-unit coordinates. K=3 merges patterns that K=5 separates; K=6 subdivides a pattern. Decide whether those distinctions support different actions.
Initialisation and Stability
Initialisation = choosing the K starting centres before assigning customers. The assign → update cycle improves a starting solution; different starts can end at different solutions. The first centres can therefore affect the final result.
init="k-means++" chooses starting centres that tend to be spread out. It still uses randomness; it does not guarantee the best possible solution.
n_init=10 means 10 complete attempts on the same data with the same K, each beginning from an initial centre configuration. Each attempt can contain many assign/update iterations. Keep the completed attempt with the smallest WCSS. It does not mean 10 clusters or 10 updates.
Read the code: K = 5 groups; 10 starts per fit. Fit A uses seed 42; fit B uses seed 7. Compare their final WCSS, then inspect the memberships and profiles.
Reproducible Does Not Mean Stable
Reproducible: repeat the same procedure with the same data, settings and random seed, and obtain the same result. random_state=42 makes this convenient; 42 is not a special or better seed.
Stable: the main customer patterns remain similar under reasonable changes. A fixed seed alone cannot demonstrate this.
Check
What to look for
Change the seed; keep data, scaling and K fixed
Similar WCSS, group sizes, memberships and original-unit profiles
Compare nearby K values
Which groups split or merge? Do the extra groups support a useful action?
Keep features standardised and inspect extreme records
Are the conclusions driven by units or a few unusual customers?
Compare memberships, not ID numbers. A group called 0 in one run can be called 2 in another with exactly the same customers. Similar WCSS alone also does not prove the memberships are the same.
If the substantive patterns change sharply, describe the segmentation as sensitive and investigate before using it for business decisions.
Outliers and Shape Limitations
An outlier is a customer far from most other customers in the chosen feature space. K-means uses means and squared distances, so unusual values can have a large influence.
Why the square matters: a distance of 10 contributes 100 to WCSS; a distance of 1 contributes only 1. One far-away point can therefore outweigh many small gaps.
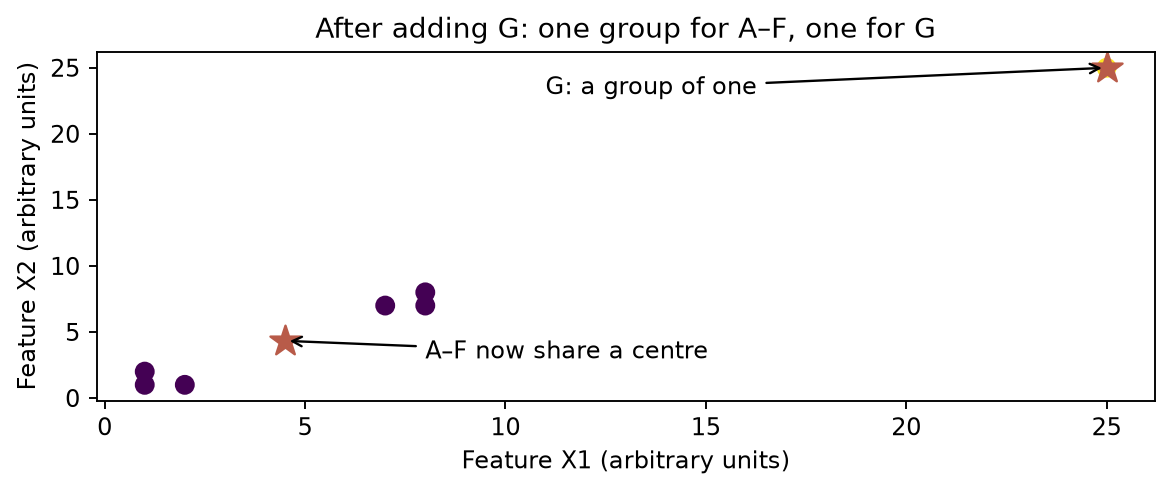
Our example: A–F originally form two compact groups. Add G=(25,25) and keep K=2. Standardise both features before fitting. In this fit, one centre is used for G alone, while A–F are combined. The plot converts centres back to the original coordinates. K-means has used a scarce centre to reduce the large squared error from G.
Check before acting: is G a data-entry error or a genuine unusual customer? Correct verified errors; investigate valid extremes. StandardScaler does not remove outliers, and unusual does not automatically mean wrong.
Why Cluster Shape Matters for K-Means
K-means asks: which centre is closest? It represents each group by one mean point. This works naturally for compact, roughly round groups in the selected feature space.
Long or curved groups: points far apart along one meaningful shape may be nearer to another centre. K-means can split that shape or join parts of different shapes. Its nearest-centre boundaries are straight in two dimensions, so they cannot trace arbitrary curved groups.
Different spreads or sizes: a broad group can contribute many large squared gaps. K-means may split it to reduce WCSS, even when a smaller nearby group then gets merged with another.
What to do: inspect a scatter plot and the resulting memberships, check feature scaling, and consider another clustering method if the geometry does not match the business question. Increasing K may reduce WCSS without solving the interpretation problem.
Choose a Useful, Defensible K
There is no single number that chooses K for us. Compare several candidates using the same customers, features and scaling. Then explain why the chosen groups are useful.
Read this example: moving from K=4 to K=5 reduces WCSS by about 36.94; moving from K=5 to K=6 reduces it by only 4.19. That makes K=5 worth examining, but does not prove it is the right answer.
Ask three questions: Are groups reasonably compact? What customer differences do they describe? Can we use those differences? For example, if two new groups would receive exactly the same offer, the extra split may add little value.
A clear conclusion would be: “We will try K=5 because it captures useful income/score differences without the extra split at K=6. We will check the profiles and stability before using the groups.” This is a proposed decision for the simulated example, not a verified business result.
In-Class Practice: Compare K=4 and K=5
Fit both choices, compare WCSS and membership counts, and describe a tradeoff. Keep the features and scaling identical.
§5 — Customer Profiles and Business Actions
Describe who is in each group, connect its centroid to its average features, and use that description to propose an action.
What Is a Cluster Profile?
K-means gives us a group number for each customer. A number such as “group 0” does not tell a manager what those customers are like.
A cluster profile is a short description of the customers in one group: how many there are, what their measured features are like, and how they differ from other groups. Here, we start with average annual spending in each product category.
Why do this? The sales manager needs to know which products a group tends to buy before proposing a suitable offer. “Group 0” gives no such information; “45 customers with higher average Grocery and Milk spending” does.
Profiling describes groups after clustering. It does not fit a second model or create new group assignments.
From Customers to a Centroid
A centroid is one point whose coordinates are the group’s feature means. For two features, average each column separately.
In this small illustration, group 0 contains A=(2,4), B=(4,4), C=(3,7), where coordinates are (Milk, Grocery) annual spending in thousands of monetary units.
\[
\text{Centroid of group 0}
=\left(\frac{2+4+3}{3},\frac{4+4+7}{3}\right)
=(3,5).
\]
The star therefore represents mean Milk spending of 3,000 and mean Grocery spending of 5,000 per customer per year. It may lie between customers: it is not an actual customer, and not every customer spends these amounts.
A Profile Is a Picture of the Group
“Picture” means a numerical description, not a photograph or a new customer. We can show the same group as a point on a scatter plot, a row of means, or a bar chart.
Small illustration
Customers
Mean Milk
Mean Grocery
Plain description
Group 0
3
3,000
5,000
Lower spending in these two categories
Group 1
3
9,000
11,000
Higher spending in these two categories
Connection: the two means in each row are that group’s centroid coordinates in original units. The profile adds context: group size, units and a description. Later we can also add the spread of values or the mix of customer types.
Use: compare these measured patterns to propose different offers. Limit: the averages do not tell us that every member is the same, or that the higher-spending group is more profitable.
Real Customers: Fit Groups, Then Count Members
Now apply the idea to the distributor’s 440 customers and six annual spending categories. We use K=3 as a working example; this does not establish that three is best.
Purpose of this code: attach a group label to every customer, then find how many customers each profile will describe.
Code
What it does
Why we need it
fit_transform(...)
Standardises the six spending columns
Makes distances comparable
km.fit_predict(X)
Fits K-means and returns one label per row
Identifies which customers belong together
wholesale["Cluster"] = ...
Saves each row’s label
Lets us select a group afterwards
value_counts().sort_index()
Counts members in label order
Shows how many customers support each summary
Read the result: group 0 has 45 customers; group 1 has 393; group 2 has 2. IDs 0, 1 and 2 are names, not a ranking. Next we calculate what each group buys.
Build the Profile: Select Customers, Then Average
Purpose of this code: turn the labels into a readable table of average purchases. We already know each customer’s group; we are describing those groups, not fitting them again.
wholesale["Cluster"] == 0 finds group 0’s rows.
.loc[..., features] keeps those customers and the six original spending columns. group0 is a table of 45 customers × 6 features.
group0.mean() averages each column separately: six numbers, one group’s mean spending profile. Repeat for groups 1 and 2.
pd.DataFrame(...) stacks the three summaries: one row per group, one column per category. profile is simply our chosen Python variable name.
Interpret: group 0 averages 28,656 m.u. on Grocery and 19,386 m.u. on Milk per customer per year, versus group 1’s 5,535 and 4,115. These are original-unit centroid coordinates for this converged K-means fit, not group totals.
Centroid and Profile: The Same Means in Different Units
We already have the profile from .loc and .mean(). Why show another method? K-means has also stored the group means in km.cluster_centers_, but it fitted them in standardised units.
Same group, same average pattern, two coordinate scales: the model uses standardised coordinates for distance; the manager needs annual spending amounts. scaler.inverse_transform(...) converts the stored centres to those original units.
Here “column mean” and “column SD” come from all 440 customers used to fit the scaler, not only the chosen group. Use that same fitted scaler.
Read the result: group 0’s Grocery coordinate becomes about 28,656 m.u., matching the profile calculated directly from its customers. This is an alternative way to obtain the feature means; it adds no new customers, groups or business evidence.
Inspect the Two-Customer Group
A profile is a summary. Check the customers behind it before treating it as a segment for a campaign. Group 2 contains only two customers, compared with 45 and 393 in the other groups.
Its mean Frozen spending is about 48,702 m.u. per customer per year. A large mean from two records is different evidence from a large mean shared by hundreds of customers.
Purpose of this code:value_counts() obtains group sizes; idxmin() finds the smallest group’s ID; .loc prints its actual customer records. Read the two rows to see what their average hides.
Check for verified data errors or genuine unusual customers. They may need individual attention; the profile alone does not justify a mass campaign or the name “VIP.”
Render Original-Unit Spending Profiles
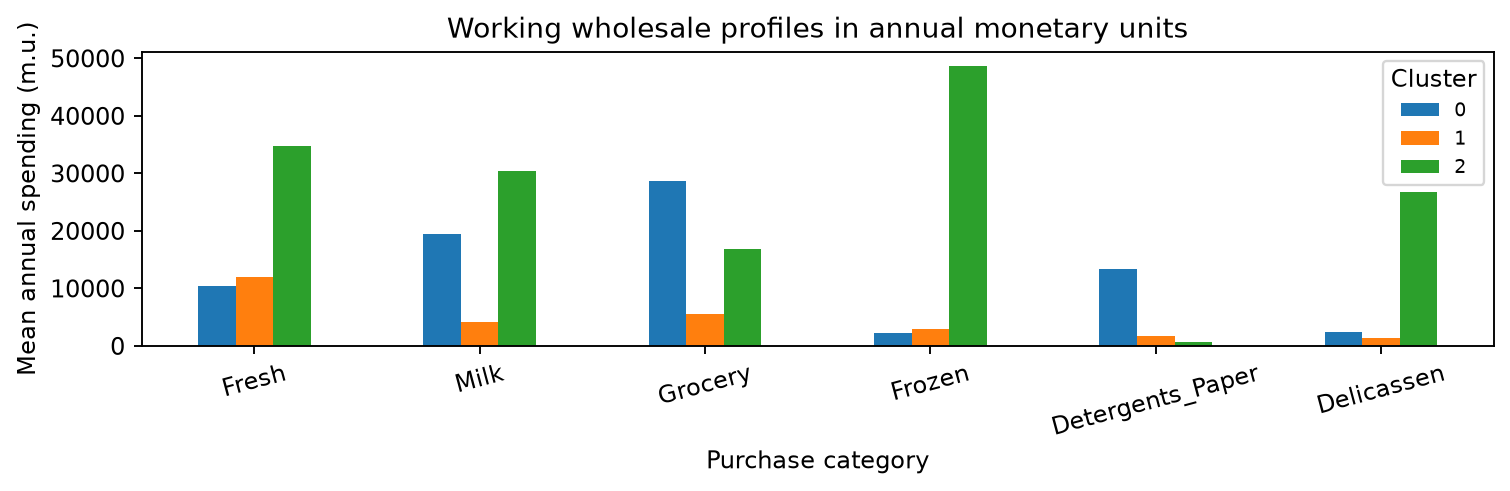
Purpose of this code: show the original-unit profile table as bars, so the manager can read actual average spending amounts.profile.T places categories on the horizontal axis; .plot.bar() draws one bar per group in each category.
Now read the same profiles in money amounts. The horizontal axis lists product categories. The vertical axis is mean annual spending per customer, in monetary units. The three bar colours represent the three groups.
For Grocery, group 0’s bar is about 28,656, compared with group 1’s 5,535. This tells the sales team how the groups’ average purchases differ.
Check who is behind each bar: group 0 has 45 customers, group 1 has 393, and group 2 has only 2. A tall bar for group 2 describes those two customers; it does not establish a large market opportunity.
Render Category Profiles in Comparable Units
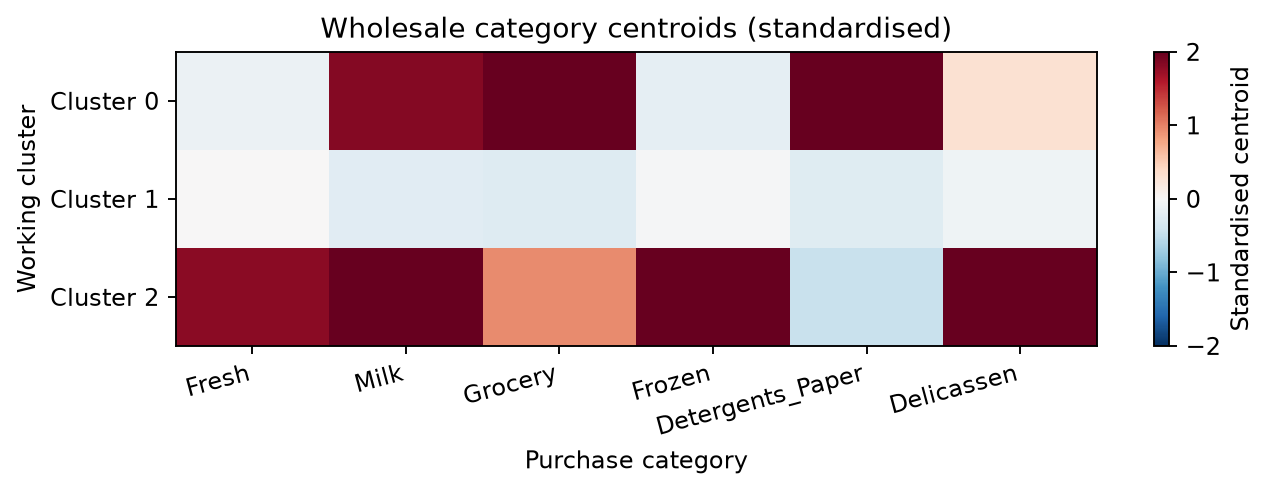
Purpose of this code: draw the mean-feature table as colours so we can compare each group’s buying pattern across all six categories. It visualises the existing centroids; it does not fit new groups.
Read one square at a time. Rows are customer groups; columns are product categories. A square shows whether that group’s average spending is above or below the average for all 440 customers in that category.
Red / positive: above the category average. Blue / negative: below it. Near white / zero: close to it. A value of +1 means one category SD above the overall mean; it does not mean one monetary unit.
Start with group 0’s Grocery square, then compare its Milk square. Next read across group 1. This helps us compare buying patterns across categories with very different spending ranges.
The colour bar is limited to −2 to +2: values beyond those limits share the end colour. Colour alone does not show their exact magnitude, and red does not mean higher profit.
Extension: Compare Absolute and Compressed Spending
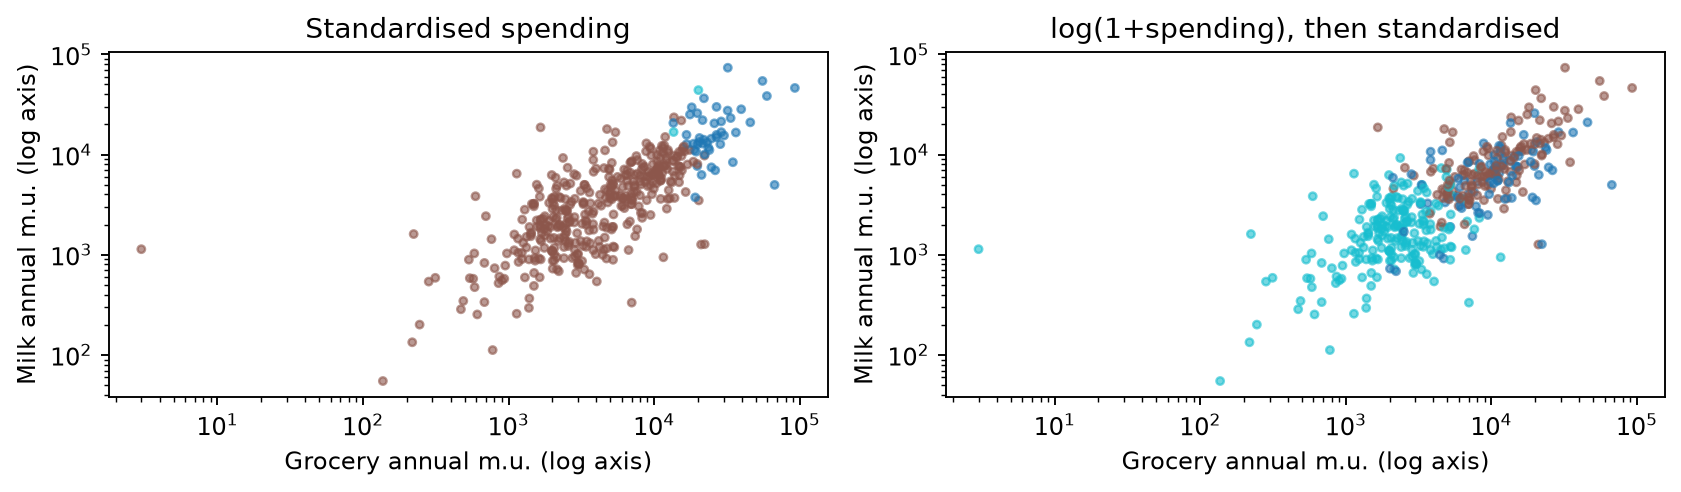
Optional: what if a few very large spending amounts drive the groups?log(1+x) compresses large values. For example, a rise from 1,000 to 10,000 is much smaller on a log scale than in raw monetary units.
The left panel fits standardised spending. The right panel first applies log(1+x), then standardises and fits K-means again. Customers can change colour because we changed how spending differences are measured.
Both plots display the same Grocery and Milk axes on log scales so we can see the points. Changing the plot axes alone would not change the fitted groups; changing the model inputs does.
Compare the group sizes and the original spending profiles before deciding whether this alternative helps. It changes the business question; it is not an automatic improvement.
Interpret with External Categories Afterwards
Do our spending groups mostly contain shops, or hotels/restaurants/cafés? We did not use Channel to create the groups. We can now use it to help describe them.
pd.crosstab(Channel, Cluster) makes a count table. Rows are customer types: 1 = hotel/restaurant/café; 2 = retail. Columns are the fitted clusters. A cell counts customers belonging to both its row type and its column group.
The second table uses normalize="columns": divide each count by that cluster’s total. Each column adds to 1, so it shows the customer-type mix within that group.
A spending group can contain both types. That is not automatically an error: we grouped customers by spending, not by their business label.
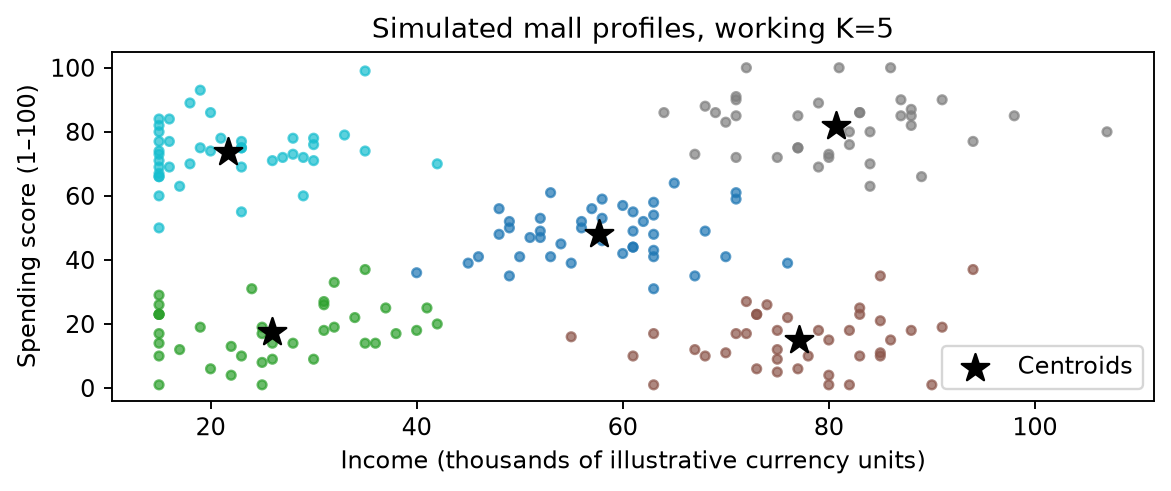
Compare the Simulated Mall Customer Profiles
Use the same reading method for the mall example. This constructed dataset uses two features: annual income (in thousands of illustrative currency units) and a spending score from 1 to 100.
For each group, select its customers, calculate mean income and mean score, then count its members. Compare the mean values with the other groups.
A group with relatively high income and low score can be called “higher income, lower spending score.” That name tells us exactly what was measured.
Do not rename it “disloyal customers” or “low-profit customers”: neither loyalty nor profit is in this table. A descriptive name is enough.
Render Mall Profiles with Original-Unit Centres
Each dot is one customer; each star is one group’s average position. Read income from left to right and spending score from bottom to top.
A star near the upper right means that group has relatively high average income and high average score. A star near the lower right means high income but low score. Nearby dots need not have exactly the average values.
The star may lie between customers rather than on a dot. It is a mean, not necessarily an actual person. Income and score help describe customers; they do not directly measure the profit an offer would generate.
From Profile to a Testable Action
What could the distributor try for group 0? Its 45 customers average about 28,656 m.u. on Grocery and 19,386 m.u. on Milk. A combined Grocery–Milk offer is one idea worth testing.
Keep three statements separate:
What we observed: this group already buys relatively more Grocery and Milk than the large group 1.
What we propose: offer some suitable customers a Grocery–Milk bundle.
What we need to learn: does the offer increase margin after the discount and campaign costs?
For a pilot, randomly assign eligible customers to an offer group and a comparison group where feasible, then compare results over the same period. Higher sales alone are not enough if the discount removes the extra margin.
Clustering suggests whom we might study. It does not show that an offer will work.
In-Class Practice: A Sales Manager’s Memo
Write a short note to the distributor’s sales manager. Use the original spending amounts, not standardised coordinates.
Find the group with the highest mean Grocery spending.
Report its customer count and its average Grocery and Milk spending, with units.
Give the group a plain descriptive name.
Suggest one offer to test and one result to measure.
Use this structure: “Group __ contains __ customers. On average, each spends __ on Grocery and __ on Milk per year. We could test __ and measure __.” Do not promise that the offer will increase profit.
§6 — Hierarchical Clustering: One Customer Story
Optional — not covered in the final exam.
Follow five customers through four merges, read their tree, and choose a cut.
Build Groups by Joining Two at a Time
Our manager has five customers, A–E. Hierarchical clustering starts with one group per customer and repeatedly joins two groups.
Five customers need four merges to become one group. We keep the whole history as a tree, then choose how many final groups to use.
A Group Needs a Rule for Comparing Distances
Distance compares two customers. Linkage compares two groups.
Suppose A and B are already together. To compare {A,B} with C, we have two customer gaps: A–C=6 and B–C=5.
A linkage rule turns those gaps into one group-comparison value. The next three slides show three possible rules.
Single Linkage Uses the Nearest Pair
Single linkage uses the smallest cross-group customer distance.
For {A,B} versus C, the two gaps are 6 and 5.
Single linkage = min(6,5) = 5. Only the closest pair determines this group comparison.
Complete Linkage Uses the Farthest Pair
Complete linkage uses the largest cross-group customer distance.
For {A,B} versus C, the two gaps are 6 and 5.
Complete linkage = max(6,5) = 6. Even the farthest pair matters. We use this rule for the rest of the example.
Average Linkage Uses All Cross-Group Pairs
Average linkage uses the mean of all cross-group customer distances.
For {A,B} versus C, there are two pairs: A–C and B–C.
Average linkage = (6+5)/2 = 5.5. Both pairs contribute equally here.
Read Our Five-Customer Distance Table
Each cell compares its row customer with its column customer. Smaller means more similar. The diagonal is zero; each pair appears twice.
A
B
C
D
E
A
0
2
6
10
9
B
2
0
5
9
8
C
6
5
0
4
5
D
10
9
4
0
3
E
9
8
5
3
0
We use these same five customers and same distances on every remaining slide.
Merge 1: Join A and B at Height 2
At the start, each group contains one customer. Its comparison with another group is simply that customer-pair distance.
The smallest distance is A–B=2, so join them first.
We now have four groups: {A,B}, {C}, {D}, {E}.
Merge 2: Update the Gaps, Then Join D and E
Use complete linkage to update the new group’s comparisons:
Current groups
Group-comparison value
{A,B} and C
max(6,5) = 6
{A,B} and D
max(10,9) = 10
{A,B} and E
max(9,8) = 9
C and D
4
C and E
5
D and E
3
The smallest current value is 3. Join D+E. Three groups remain: {A,B}, {C}, {D,E}.
Merge 3: C Joins {D,E} at Height 5
Compare the three remaining groups using the farthest cross-group pair:
Current groups
Complete linkage
{A,B} and C
max(6,5) = 6
C and {D,E}
max(4,5) = 5
{A,B} and {D,E}
max(10,9,9,8) = 10
The smallest of 6, 5 and 10 is 5. Join C with {D,E}.
The merge is at 5, even though C–D is 4: complete linkage also checks C–E=5.
Merge 4: Join the Final Two Groups at Height 10
Only {A,B} and {C,D,E} remain. Complete linkage checks all six cross-group customer pairs:
C
D
E
A
6
10
9
B
5
9
8
The largest is A–D=10, so the final merge height is 10. All five customers now belong to one group.
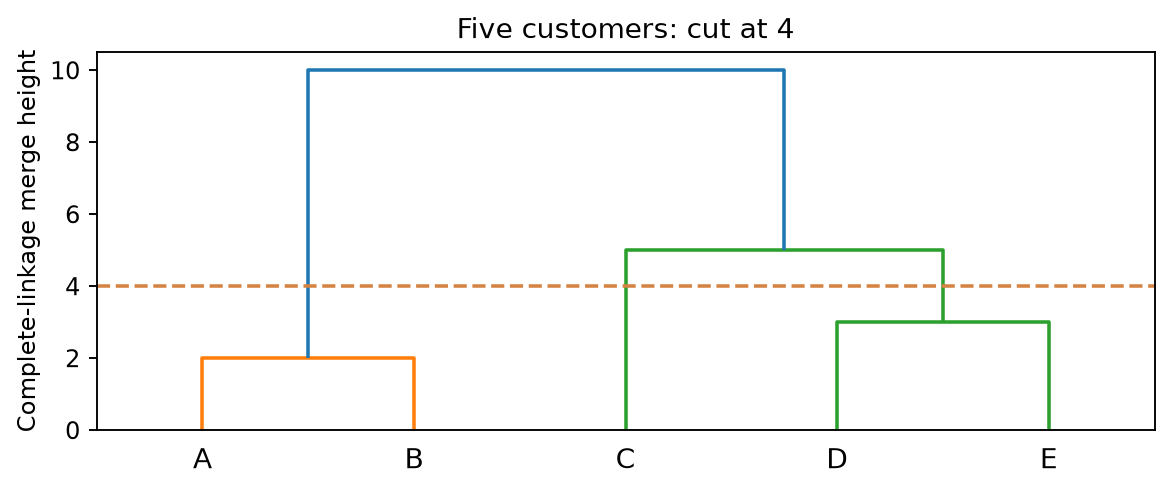
A Dendrogram Draws the Four Merges
A dendrogram is a picture of the merge history. Start at the customer names and follow branches upward.
Each horizontal join is one merge; its height is the complete-linkage distance. Read the four heights: 2, 3, 5, 10.
The left-to-right customer order only makes the tree easier to draw. It is not a ranking.
A Horizontal Cut Chooses the Final Groups
Keep joins below the cut. Customers connected below it belong together.
At height 4, A+B and D+E have joined, but C has not joined either group.
We obtain three groups: {A,B}, {C}, {D,E}.
Move the Cut and Watch the Groups Change
Use the same five-customer tree. Before moving the cut, predict who will stay together.
Try 1 → 4 → 6 → 11. You should see 5 → 3 → 2 → 1 groups.
Changing the cut reuses the same tree; it does not run the merging procedure again.
One Row of Z Records One Merge
Python calls the stored merge history Z, a linkage matrix. Five customers require four rows.
Read the first row [0,1,2,2]:
Entry
Meaning
Left = 0
Customer A
Right = 1
Customer B
Height = 2
Join them at distance 2
Count = 2
The new group contains 2 customers
Original customer IDs 0–4 mean A–E. They are labels, not ranks.
A New Node ID Refers to an Earlier Group
After a merge, Python gives the new group a node ID. Original customers are 0–4; new groups are 5–8.
New node
Group it represents
5
{A,B}
6
{D,E}
7
{C,D,E}
8
{A,B,C,D,E}
The third row [2,6,5,3] therefore means: join customer C (node 2) with group {D,E} (node 6), at height 5, making a group of 3 customers.
Save the Merge Record Once, Reuse It
Z is a compact record of the whole tree. Each row refers to customers or earlier groups by ID.
We can reuse Z to draw the tree or choose a different cut, without computing the merges again. Rebuild it only if the customers, distances or linkage rule change.
Python Computes the Merge Record We Worked Out
The code repeats our complete-linkage calculations and prints Z. The four merge heights should be 2, 3, 5, 10.
pd.read_csv(...) loads our distance table. squareform(...) repackages its upper-half pair distances for Python’s clustering function. It does not calculate new distances.
linkage(..., method="complete") performs the merges and returns their record. The printed column names help us read it.
Python Draws the Saved Tree
dendrogram(Z, ...) draws the merges already stored in Z. It does not perform a new clustering.
labels=... adds customer names. ax.axhline(4, ...) draws our horizontal cut at height 4.
Check the picture: the cut leaves {A,B}, {C}, {D,E}. Change the cut line to 6 and predict the result before running.
Read the Diagram Before Writing Code
Using the same five-customer tree, explain why C joins {D,E} at height 5.
Point to the two relevant customer distances, name the linkage rule, and explain the maximum. Then complete the Section 6 practice on the course main page.
Chapter Summary
Decision
Python tools
Check before claiming success
Define similarity
Choose feature columns
Units, identifiers, business purpose
Inspect records
.isna(), .describe()
Completeness, spread, unusual records
Standardise selected features
StandardScaler
ddof=0; weighting interpretation
Fit groups
KMeans, .fit_predict()
Seed, initialisations, arbitrary IDs
Choose K for K-means
.inertia_, elbow, silhouette
Sizes, stability, useful distinctions
Profile members
.loc, .mean(), .value_counts()
Original units, supported names
Propose actions
A measurable pilot
Profiles do not prove campaign effects
Optional extension (not covered in the final exam): inspect a tree
linkage, dendrogram, fcluster
Linkage meaning, cut heights, ties
A useful segmentation is a documented business choice: features + scaling + algorithm + K/cut + profiles + a plan to check the action.