Chapter 3 — Predicting with Linear Regression
From a fitted line to a defensible business prediction
What This Chapter Covers
A manager needs a prediction and a reason to trust it. We will estimate a line, interpret coefficients, quantify uncertainty, check residuals, and evaluate predictions on later data.
Chapter Roadmap
| Section | Question we will answer |
|---|---|
| 1 | What relationship is worth modelling? |
| 2 | How is a regression line fitted? |
| 3 | How can SPY return explain NVDA return? |
| 4 | What do standard errors, tests, and intervals tell us? |
| 5 | What can we predict, and how uncertain is it? |
| 6 | What do residuals and unusual observations reveal? |
| 7 | How do we interpret several predictors together? |
| 8 | Does the model predict later records well? |
| 9 | Which pharmacy predictors help predict Profit? |
Business Data and a Shared Regression Workflow
The short retail table introduces the calculations. For simple regression, X is the SPY daily return and Y is the NVDA daily return. For multiple regression, use local demographics to predict pharmacy Profit.
§1 — Business Questions and Association
Choose an outcome, choose relevant predictors, and inspect the relationship before fitting a model.
Outcome Y and Predictor X
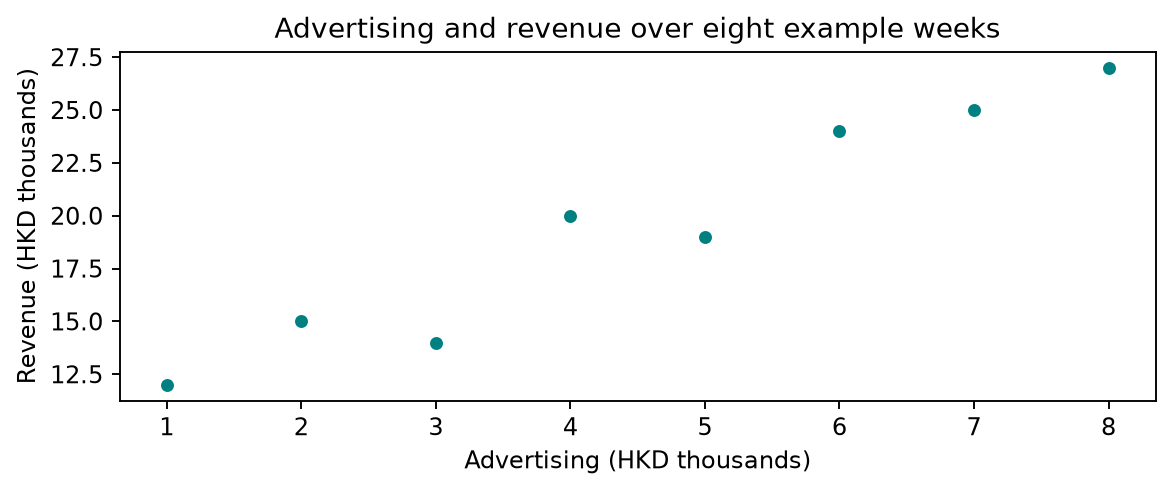
A response/outcome is what we want to explain or predict. A predictor/feature is an input. Here Y is weekly revenue; X is advertising spending. Each row refers to the same week.
Association, Direction, and Shape
Two variables are associated when their values show a relationship. A positive pattern tends to rise as X increases; a negative pattern tends to fall. A linear pattern follows approximately a straight line. A nonlinear pattern bends or changes direction.
Scatterplot Before Correlation
Each point represents one week. Put Ads on the horizontal axis and Revenue on the vertical axis. Look for direction, curvature, spread, and isolated observations.
Four Scatterplot Patterns
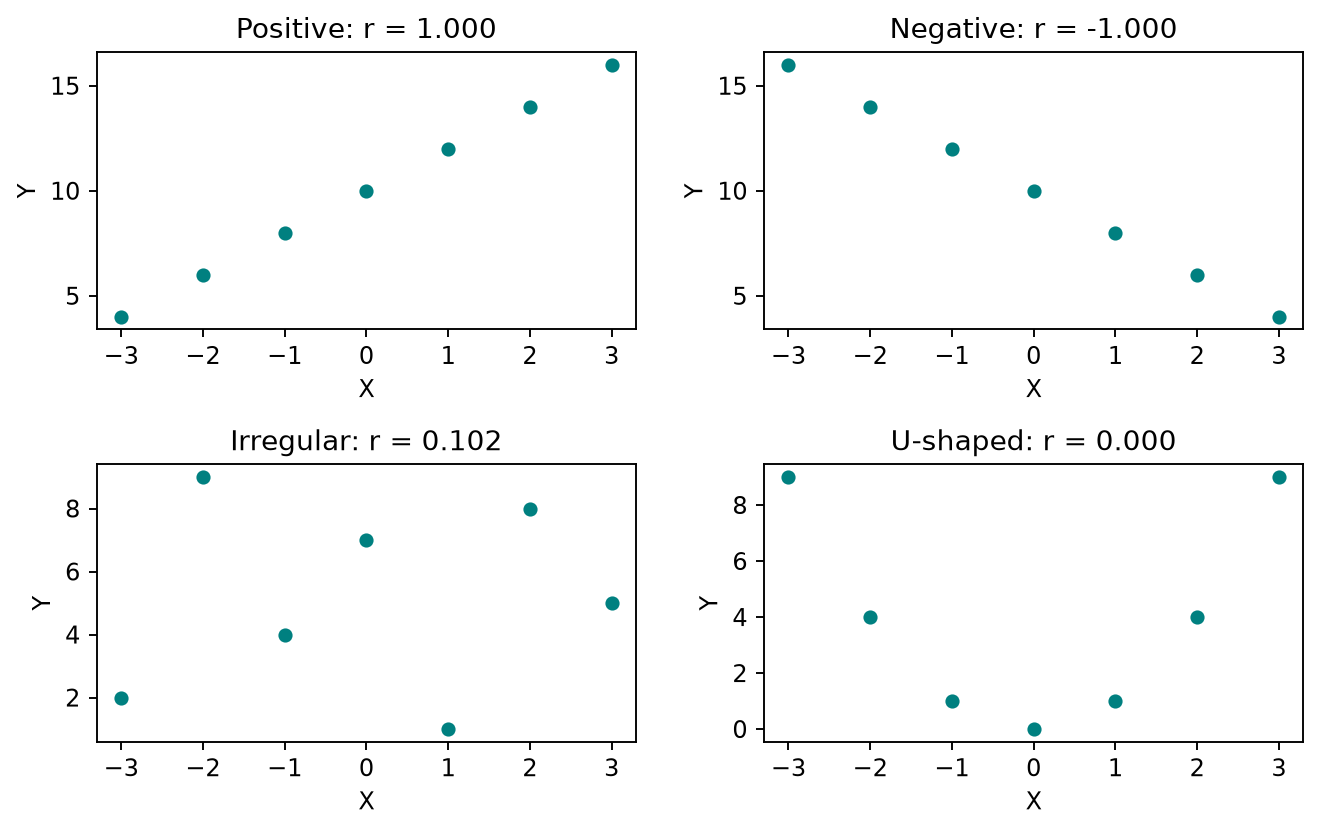
These constructed examples use the same X values. Compare a positive line, a negative line, irregular scatter, and a U-shaped curve. Read the shape before comparing the reported Pearson correlations.
Read a Correlation as Linear Association
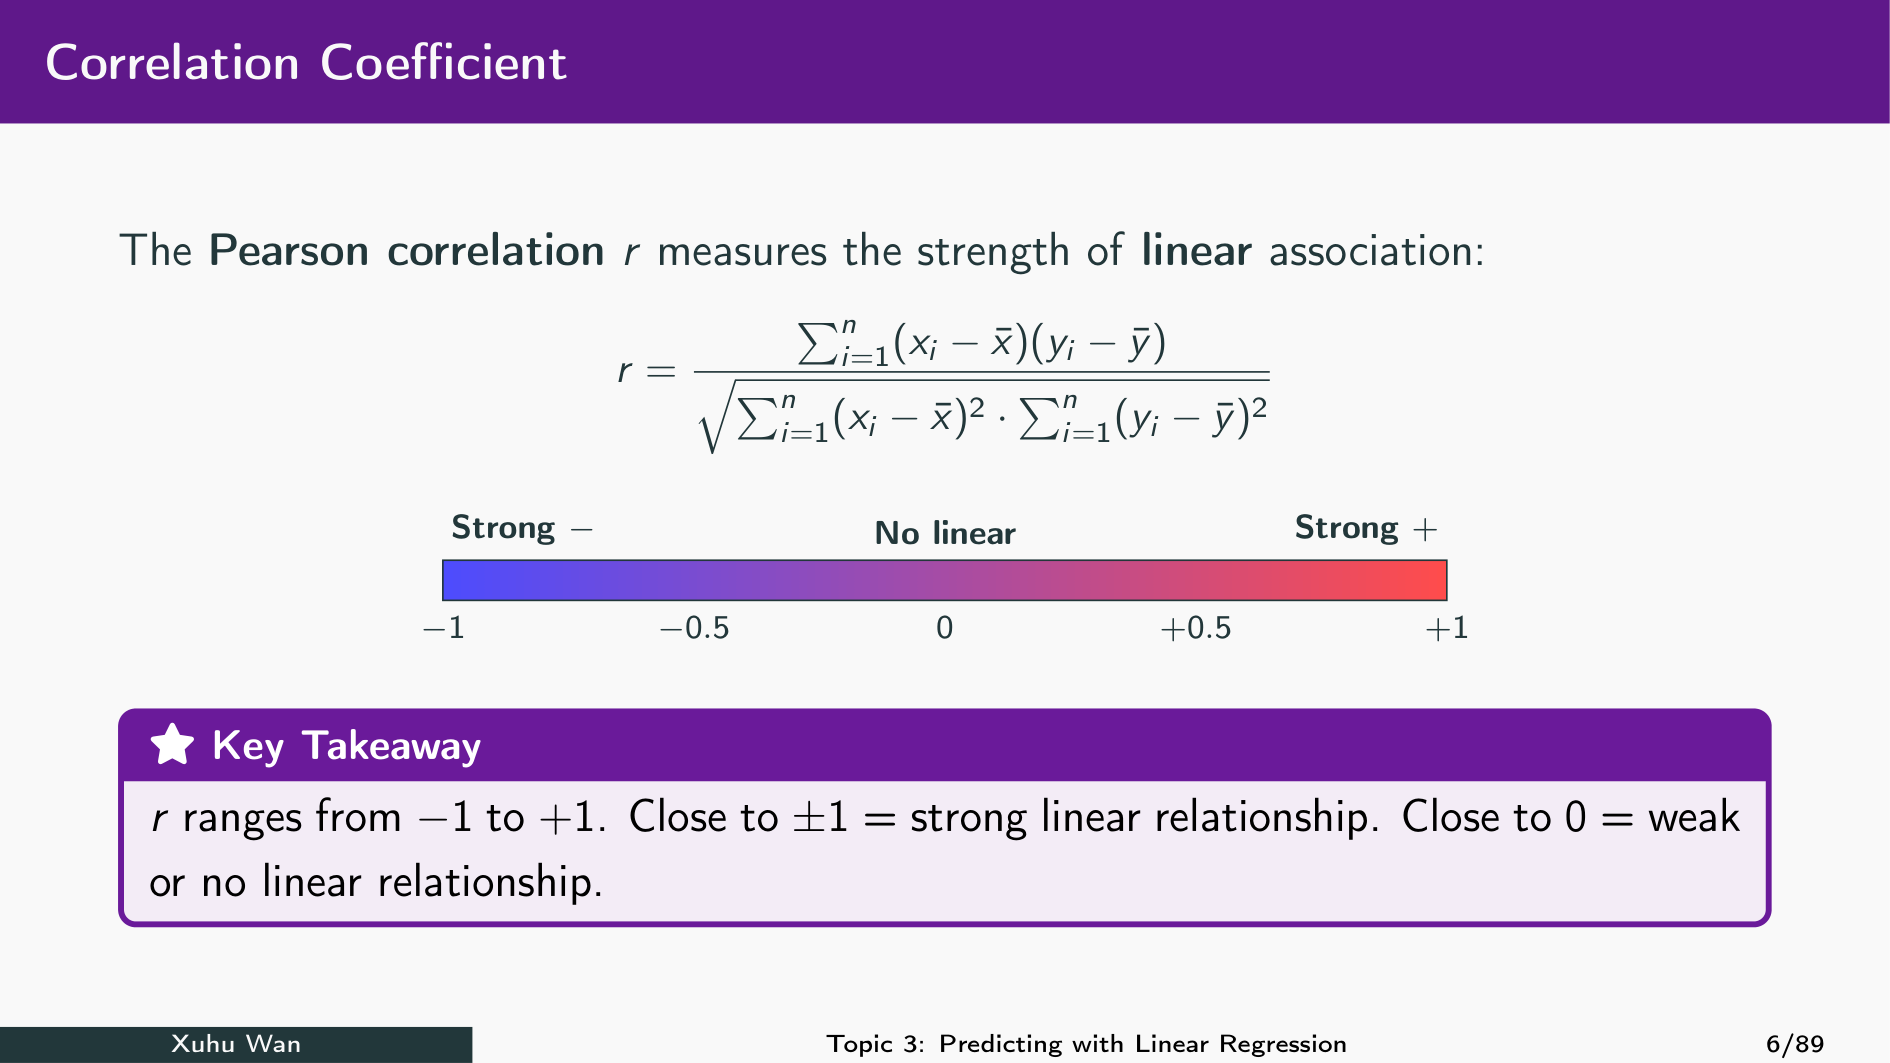
Pearson correlation \(r\) ranges from −1 to +1 when both variables vary. Its sign gives direction; its magnitude describes linear association. A high correlation alone does not show causation.
How Pearson Correlation Works
\(r=\frac{\sum_i(x_i-\bar x)(y_i-\bar y)}{\sqrt{\sum_i(x_i-\bar x)^2\sum_i(y_i-\bar y)^2}}\). Centre both variables by subtracting their means. Same-direction deviations contribute positive products; opposite-direction deviations contribute negative products. The denominator removes the units.
Zero Correlation with a Clear Business Pattern
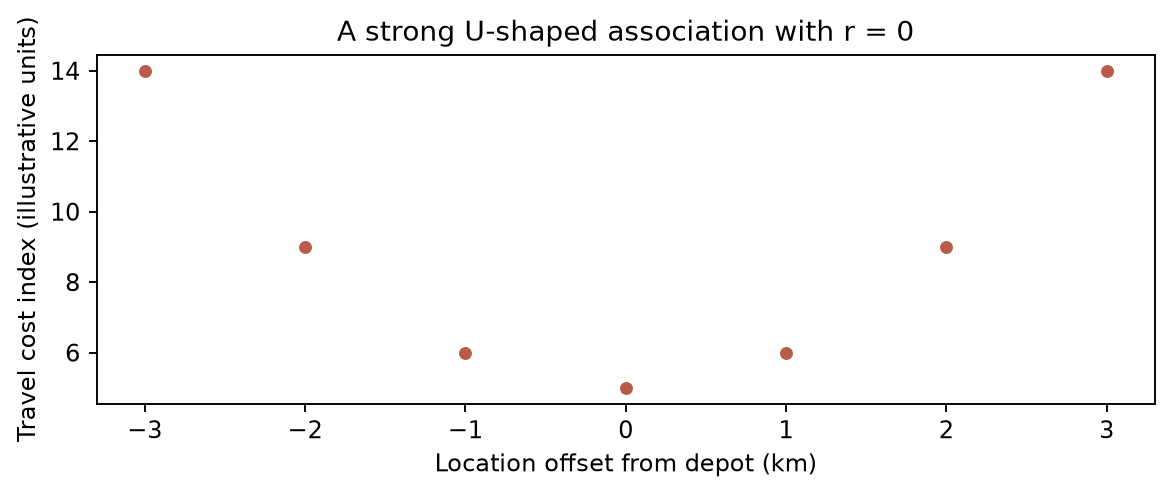
In this constructed delivery example, LocationOffset is kilometres east (+) or west (−) of a depot. TravelCost is an illustrative cost index: \(5+\mathrm{LocationOffset}^2\). Both directions become more expensive farther from the depot. Predict the correlation before running.
Interactive Association: Change the Shape
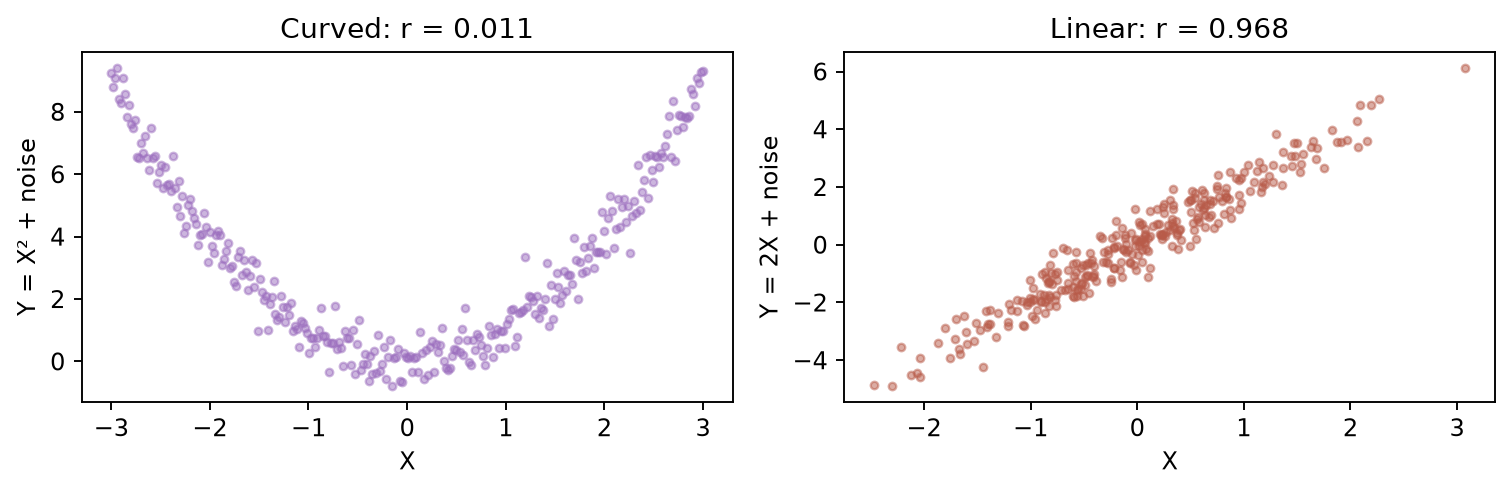
Choose a positive, negative, or U-shaped relationship. Increase the noise and watch Pearson r change. Predict first: can the U-shape have r close to zero even when X clearly matters?
Linear and Nonlinear Patterns with Noise
Compare \(Y=X^2+\mathrm{noise}\) with \(Y=2X+\mathrm{noise}\). The curved example can have a correlation near zero even when the U shape is obvious. Change the noise scale and compare the pictures with the numbers.
Correlation and Units
Changing HKD thousands into HKD multiplies the values by 1,000. The correlation stays the same; the numerical slope may change when the units of X or Y change.
Reading a Correlation Matrix
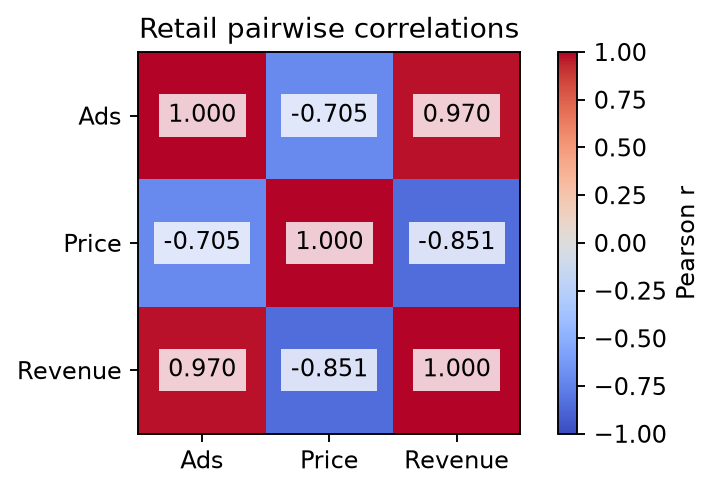
Series.corr(other) returns one number. DataFrame.corr() returns every pairwise correlation for the selected numeric columns. Find a pair at its row and column intersection. The table is symmetric; the diagonal is 1 for each varying variable.
Nonlinear Pattern and Correlation
When correlation is close to zero, there is little linear association. The data may have no obvious pattern, or they may follow a strong nonlinear pattern. Pearson correlation measures the direction and strength of a linear relationship. Always check the scatterplot.
A Heatmap Shows the Same Correlation Matrix
Run Code to draw the heatmap. .corr() calculates the matrix; ax.imshow(...) draws its colours; plt.show() displays the figure. vmin=-1, vmax=1 fixes the colour scale.
Association in NVDA and Market Returns
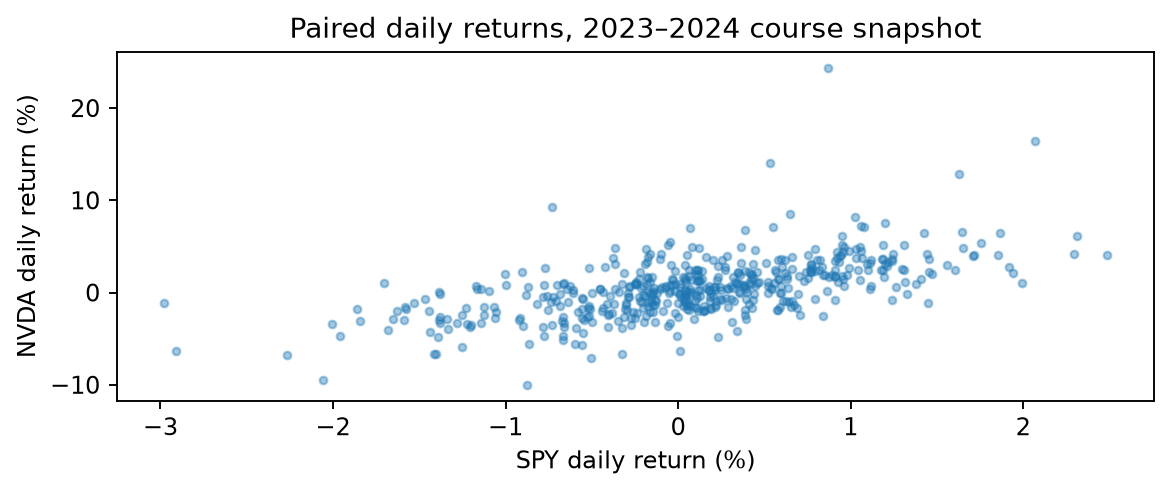
NVDA is our stock example and SPY is our market proxy. We use the existing course price snapshot: sort dates, compute each daily proportional change, and retain complete pairs. The first change is missing because it needs a preceding price. Decimal 0.01 means a 1% return.
Association Is a Starting Point
Busy weeks may have more advertising and lower prices. A simple linear regression cannot separate those relationships. A model with several predictors can account for measured price differences, while observational controls do not automatically establish causation.
In-Class Practice: A Number and a Picture
Use the delivery example. Print the LocationOffset–TravelCost correlation, draw the scatterplot, and explain how both results can be correct. Then create DistanceSquared = LocationOffset ** 2 and inspect its correlation with TravelCost.
§2 — Fitting and Interpreting a Regression Line
Read the model equation, fit ordinary least squares, and connect fitted values, residuals, and R-squared.
A Line Plus an Error
Simple linear regression (SLR) uses one predictor.
Population model
\[Y=\beta_0+\beta_1X+\varepsilon\]
- \(\beta_0\): true intercept — average \(Y\) when \(X=0\).
- \(\beta_1\): true slope — change in average \(Y\) for a one-unit increase in \(X\).
- \(\varepsilon\): noise — an individual outcome’s deviation from the population mean line.
Fitted line (estimated from the sample)
\[\hat y(x)=\hat\beta_0+\hat\beta_1x\]
- \(\hat y(x)\): estimated average of \(Y\) given \(X=x\).
- \(\hat\beta_0\): estimated intercept; \(\hat\beta_1\): estimated slope. Hats mean estimates.
Calculate a Prediction by Hand
Suppose the fitted regression line is Predicted Revenue = 10 + 2 × Ads. The coefficients are supplied for illustration. At Ads = 4, predicted average revenue is 18 thousand HKD; an individual week may differ.
Why Ordinary Least Squares?
Each vertical gap is a residual: observed \(y\) minus predicted \(\hat y\). SSE adds all eight squared gaps. Move the line, then play its movement toward the smallest SSE.
Calculate Squared Errors and SSE
For Revenue = 10 + 2 × Ads, read each observed value, prediction, residual and squared residual. Add the last column: \(SSE=\sum_i(y_i-\hat y_i)^2\). SSE is measured in squared outcome units.
Fit with statsmodels
Fit means finding the best line: the line with the smallest sum of squared residuals (SSE).
\[SSE=\sum_{i=1}^{n}(y_i-\hat y_i)^2\]
- A residual is a vertical gap: observed \(y_i\) minus fitted \(\hat y_i\).
.fit()chooses the intercept \(\hat\beta_0\) and slope \(\hat\beta_1\) that minimise SSE.sm.add_constant(...)adds the intercept column;sm.OLS(y, X)sets up the model;.fit()fits it to the data.
Results: Attributes and Methods
model.params, model.fittedvalues, model.resid, and model.rsquared are attributes: stored results, without parentheses. model.nobs counts observations used for fitting. .predict(...), .conf_int(), and .summary() are methods: calls that calculate or format a result.
Observed, Fitted, and Residual
A positive residual means the observed revenue is above the fitted line. A negative residual means it is below. Residuals have the same units as Revenue.
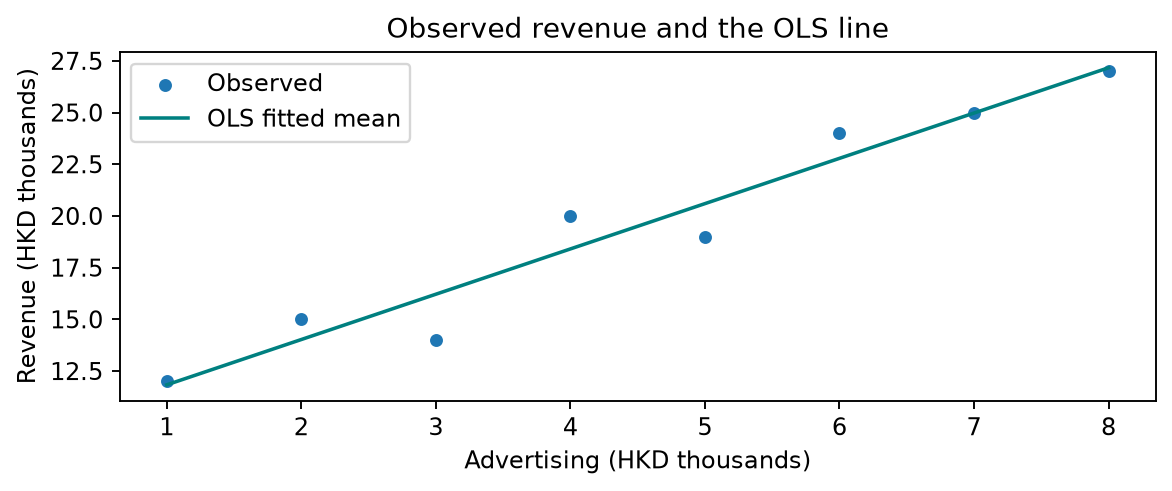
See the Fitted Line
The line is an estimated mean relationship. The vertical gaps from the observations to the line are residuals. It does not pass through every observation.
Interactive Line: Change the Slope
Move the intercept and slope. Watch the predicted values, residuals, and SSE change for the same eight weeks. The smallest SSE is what OLS seeks.
Start with Variation Around the Mean
Before fitting a line, predict the same mean \(\bar y\) for every record. SST adds the squared distances from that mean. Sample variance divides this total by \(n-1\).
\[SST=\sum_{i=1}^{n}(y_i-\bar y)^2,\qquad s_y^2=\frac{SST}{n-1}.\]
For the eight retail weeks, \(\bar y=19.5\), \(SST=214\), and \(s_y^2=30.571\). Variance has squared revenue units.
SST, SSR, and SSE: Three Different Distances
| Total variation | Explained by the regression | Remaining error |
|---|---|---|
| \(SST=\sum(y_i-\bar y)^2\) | \(SSR=\sum(\hat y_i-\bar y)^2\) | \(SSE=\sum(y_i-\hat y_i)^2\) |
| Observed → mean | Fitted → mean | Observed → fitted |
\[\boxed{SST=SSR+SSE}\quad\text{for OLS with an intercept, on its training rows.}\]
Here SSR means regression (explained) sum of squares. Some sources use SSR for residual sum of squares; always check the definition.
Interactive Decomposition: Follow One Observation
Select a week. The three coloured vertical distances show \(y_i-\bar y\), \(\hat y_i-\bar y\), and \(y_i-\hat y_i\). The signed distances add for each point; the squared totals add across the OLS training sample.
RMSE Returns the Error to Revenue Units
RMSE and R² are two measures of SLR fit. RMSE expresses residual variation in the units of \(Y\); R² describes the proportion of variation explained. Regression RMSE, denoted \(s\), estimates the standard deviation \(\sigma\) of the underlying noise \(\varepsilon\) in \(Y=\beta_0+\beta_1X+\varepsilon\):
\[s=\mathrm{RMSE}=\sqrt{\frac{\mathrm{SSE}}{n-2}} =\sqrt{\frac{1}{n-2}\sum_{i=1}^{n}(y_i-\hat{y}_i)^2}.\]
\(n\) is the training sample size. We subtract 2 because we estimated an intercept and a slope. For the 8 retail weeks: \(\sqrt{12.476/(8-2)}=1.442\) thousand HKD.
R-Squared Compares Two Fits
R² compares the line with the mean-only baseline:
\[R^2=1-\frac{SSE}{SST}=\frac{SSR}{SST}.\]
For the fitted retail OLS line: \(SST=214\), \(SSR=201.524\), \(SSE=12.476\), so \(R^2=0.9417\). It explains about 94.2% of the training variation around the mean. This does not establish causation or future prediction accuracy.
Two Measures of SLR Fit: RMSE and R-Squared
Use both measures to describe the same fitted regression line.
| Regression RMSE | R² | |
|---|---|---|
| Question | How large is the residual variation? | What proportion of variation does the line explain? |
| Formula | \(s=\sqrt{SSE/(n-2)}\) | \(1-SSE/SST\) |
| Units | Same as \(Y\) | No units |
| Better sample fit | Smaller | Larger |
| Retail example | 1.442 thousand HKD | 0.9417, or 94.17% |
Regression RMSE \(s\) estimates the underlying noise standard deviation \(\sigma\); R² gives an explained proportion. Good training fit does not guarantee good prediction on new records.
Interactive R-Squared: Reduce the Squared Errors
Start with the mean-only prediction. Move toward the OLS line and compare the vertical errors. At the OLS endpoint, R² is the fraction of the original squared error removed.
In-Class Practice: Explain the Slope
Print the fitted Ads coefficient. Explain both units in one sentence. Predict Revenue at Ads=4 using .predict() and a table with columns const and Ads.
§3 — Simple Regression with SPY and NVDA Returns
Use SPY return as X and NVDA return as Y. Fit a line, read its intercept and slope, and make a conditional prediction.
Prices and Returns Answer Different Questions
A stock price is a level. A daily return measures the proportional price change since the previous trading day. pct_change() calculates that change. Its first row is missing because it has no previous price in the file.
Decimal Returns and Percentage Points
| Decimal stored in Python | Return displayed as a percentage |
|---|---|
| 0.01 | +1% |
| 0.02 | +2% |
| -0.01 | -1% |
Multiplying a decimal return by 100 displays it as a percentage. Moving from 1% to 2% is an increase of one percentage point.
X Is SPY Return and Y Is NVDA Return
SPY represents broad US market performance. NVDA is the individual stock whose return we want to explain. Each row contains the two returns from the same trading day.
\[\text{Fitted NVDA return}=\text{intercept}+\text{slope}\times\text{SPY return}.\]
Actual NVDA return can differ from the fitted return because other influences remain.
Keep X and Y on the Same Date
The Date index identifies each trading day. Select the SPY and NVDA columns together before calculating returns, then use dropna() to remove incomplete pairs. One row is one shared date. Do not pair an NVDA return with a SPY return from another day.
Keep Later Dates for Testing
Fit using the first 80% of complete dates. Reserve the later 20% to check predictions. cut is the row position where the test period begins. .iloc[:cut] excludes that position and .iloc[cut:] starts there.
Fit NVDA Return on SPY Return
Y contains NVDA returns. The design X contains SPY returns plus the constant column added by sm.add_constant. sm.OLS(Y, X).fit() estimates the intercept and slope from the training dates.
The Intercept Is the Fitted Return When X Is Zero
Set SPY return to 0% in the fitted equation. The remaining fitted NVDA return is the intercept. Read it from model.params["const"]. The model and Python store returns as decimals.
An Intercept Describes This Fitted Line
A positive intercept puts the fitted NVDA return above zero when SPY return is zero. A negative intercept puts it below zero.
This is a description of the fitted historical relationship. It is not a guarantee that NVDA will earn that return on any particular day.
Calculate a Return from a Supplied SPY Scenario
For an illustrative line, take an intercept of 0.1% and a slope of 1.5. If SPY returns 1%, the fitted NVDA return is 0.1% + 1.5 × 1% = 1.6%. If SPY returns -1%, the fitted return is -1.4%. These illustrative coefficients are separate from the estimated NVDA model.
The Slope Describes a Change in Y for a Change in X
In a fitted straight line, a one-unit increase in X corresponds to a fitted change in Y equal to the slope. Keep the units of both variables explicit.
Here both variables are decimal returns. More practically, a one percentage-point increase in SPY return corresponds to a fitted increase in NVDA return equal to the slope in percentage points. For a slope of 1.5, that fitted increase is 1.5 percentage points.
Calculate the Slope from Covariance
For OLS with an intercept, divide the covariance of X and Y by the variance of X. Use the same complete training pairs in both calculations. Here X is SPY return and Y is NVDA return.
Compare Slopes Using the Same Return Units
| Illustrative slope | Fitted NVDA change when SPY increases by 1 percentage point |
|---|---|
| 1.5 | Increases by 1.5 percentage points |
| 1.0 | Increases by 1 percentage point |
| 0.6 | Increases by 0.6 percentage points |
| 0 | No fitted linear change |
| -0.5 | Decreases by 0.5 percentage points |
These are slope illustrations, not estimates for several stocks. Actual returns also contain residual variation.
Interactive Return Prediction: Intercept and Slope
Change the intercept, slope or SPY return, then read the fitted NVDA return. The values here are illustrative percentages.
Plot the Fitted Stock-Return Line
Each dot represents one training date. Its horizontal position is SPY return and its vertical position is NVDA return. The line shows fitted NVDA returns. Vertical distances from the dots to the line are residuals.
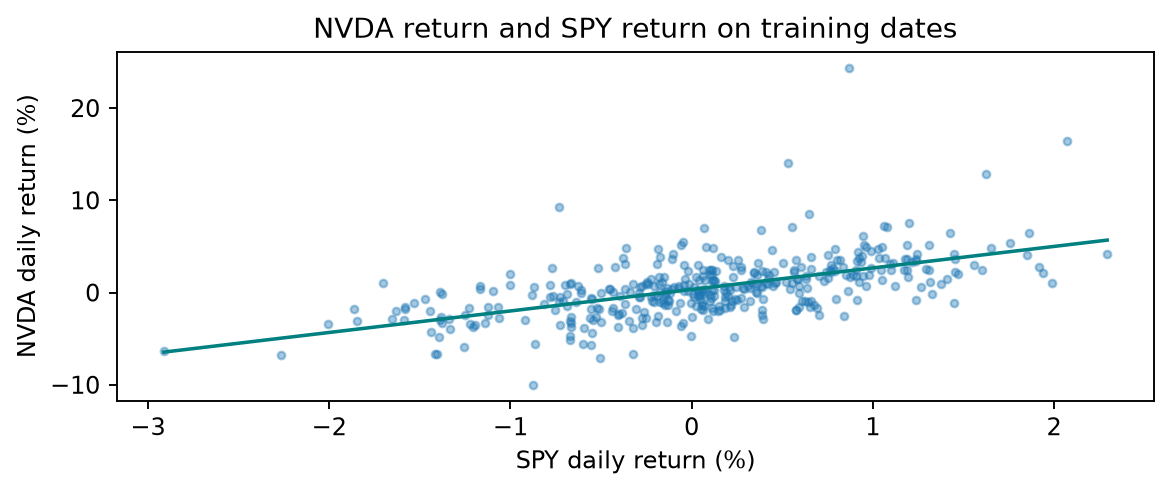
In-Class Practice: A Conditional Return
Supply SPY return of 0.01, meaning 1%, and use the fitted model to predict NVDA return. Display the result as a percentage. Explain why an unknown future SPY return must be supplied before the model can predict that day.
§4 — Coefficient Uncertainty and Statistical Inference
Distinguish estimates from standard errors; perform specified tests and interpret confidence intervals.
Why an Estimate Needs a Standard Error
sales contains eight example weeks, one row per week. Ads = weekly advertising spending (HKD thousands); Revenue = weekly sales revenue (HKD thousands); Price = selling price (HKD per item). This fit predicts Revenue using Ads; Price is not included.
A new sample gives a different fitted slope. A standard error (SE) estimates the standard deviation of these estimates across repeated samples.
\[\hat\beta_1=2.1905,\qquad SE(\hat\beta_1)=0.2225\]
- Ads estimate = 2.1905: an extra HKD 1,000 of advertising corresponds to HKD 2,190.50 more fitted average revenue.
- Ads SE = 0.2225: if we repeatedly collected samples of the same size under the same conditions and fitted each one, the Ads slope estimates would vary. Their standard deviation is estimated as 0.2225.
- SE has the slope’s units: HKD thousands of Revenue per HKD thousand of Ads. Smaller SE means a more precise slope estimate.
- It is not the standard deviation of Revenue, or the known distance from our estimate to the true slope.
Read a Coefficient Table
Columns: coef is the estimate; std err is its standard error; t tests coefficient=0; P>|t| is the two-sided p-value for that zero null; [0.025,0.975] gives a 95% coefficient interval.
\[t=\frac{\text{coefficient estimate}-\text{null value}}{\text{standard error}}.\]
The Null Value Belongs in the Numerator
The null specifies the slope value to test. Here test a slope of 1, rather than the default value 0. Subtract 1 from the estimated SPY slope, then divide by its standard error. With one predictor and an intercept the residual degrees of freedom are n−2. A two-sided test considers departures above or below 1.
Two-Sided p-Value: Both Tails
A p-value is the probability, assuming the null and model assumptions, of a test statistic at least as extreme as observed. It is not the probability that the null is true. Both tails matter for a “different from” alternative.
\[p_{\mathrm{two\ sided}}=2P\big(T_{df}\ge |t_{\mathrm{observed}}|\big).\]
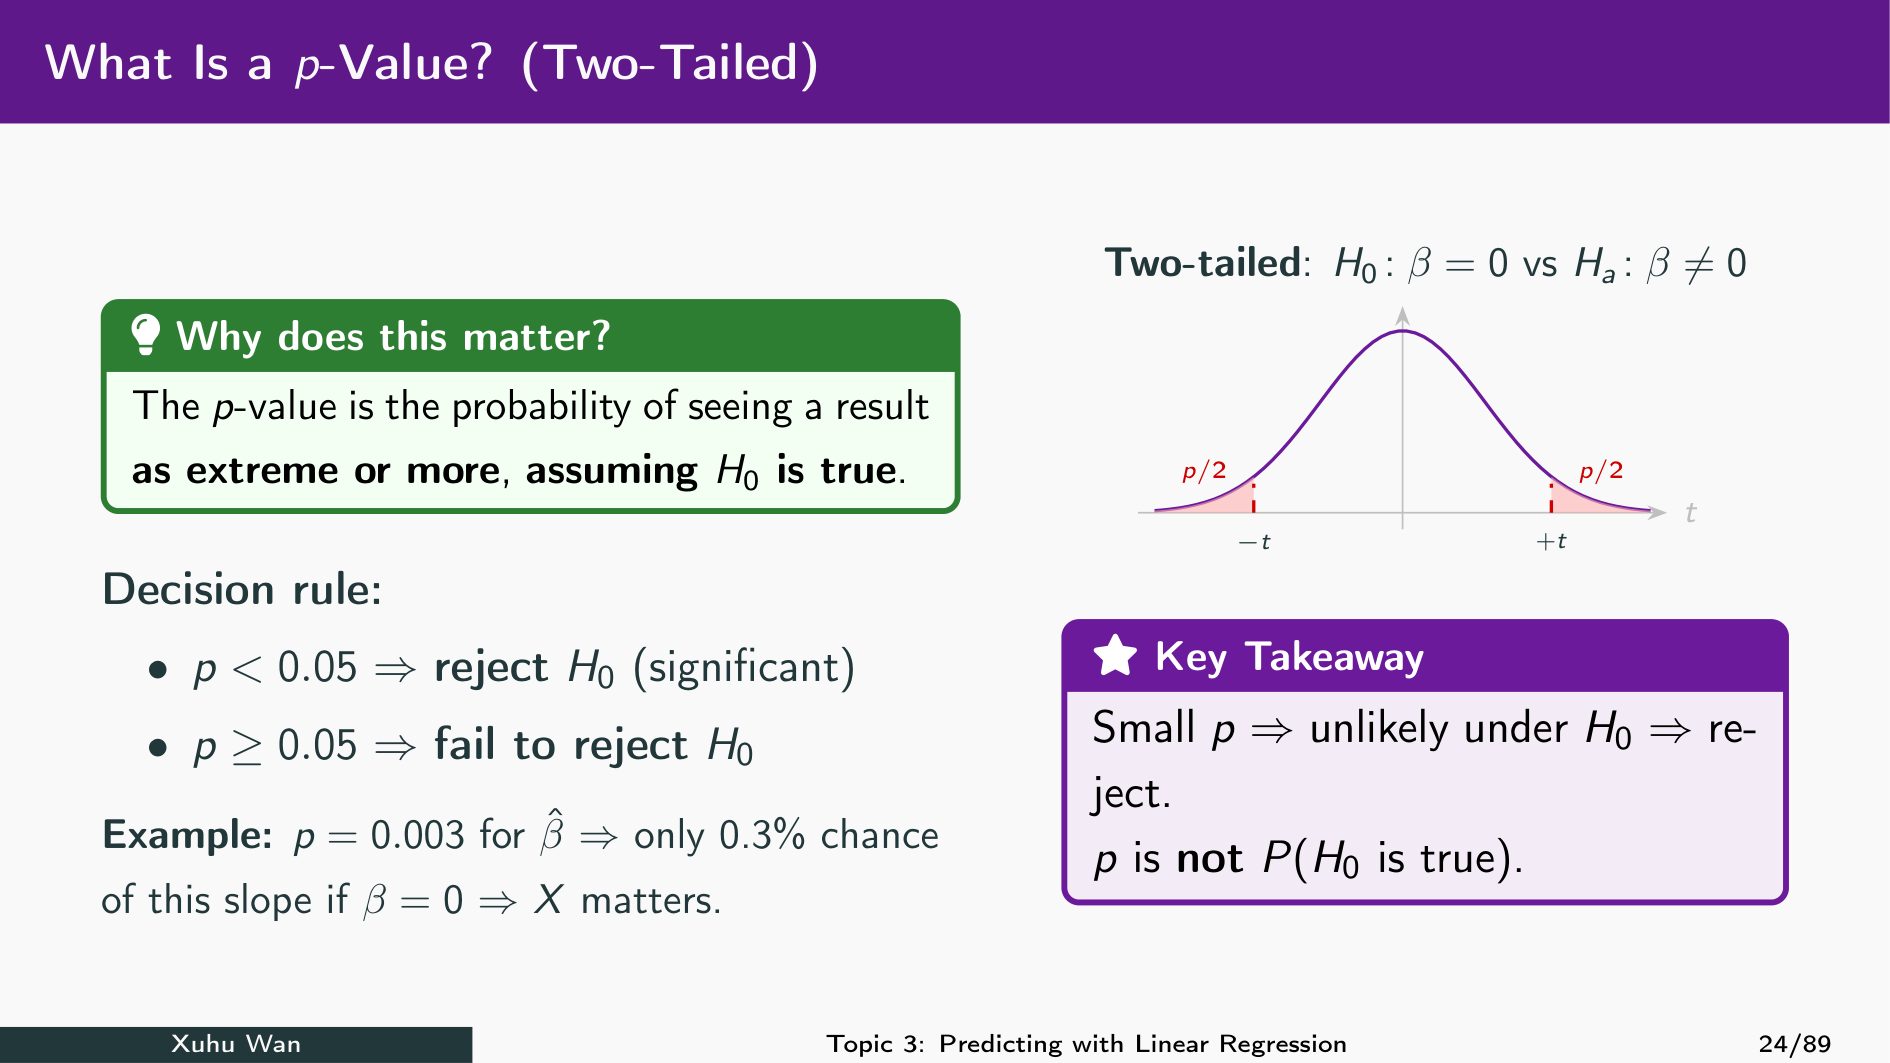
Calculate the Two-Sided p-Value
stats.t.sf(t, df) gives the right-tail area. For a two-sided test use 2 * sf(abs(t), df). The survival function is convenient and avoids subtracting a CDF very close to 1.
Render the Test Distribution
The shaded region is the two-sided p-value for an illustrative t=2.2 with 20 degrees of freedom. Change t_obs and predict how the shaded area changes. This figure is not the estimated stock-return regression test.
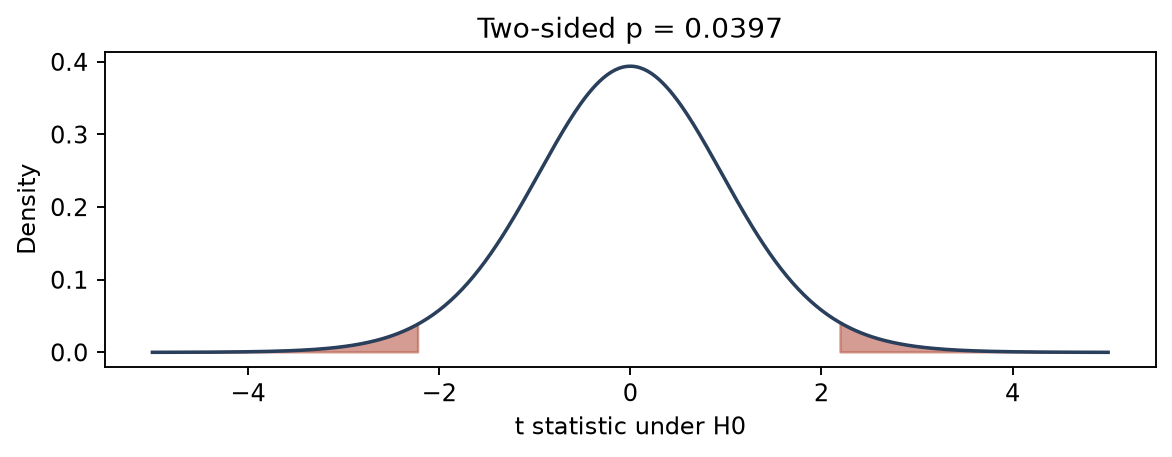
What Does p = 0.0397 Mean?
The previous graph is an illustration with \(t=2.2\) and 20 degrees of freedom. Suppose we test \(H_0:\beta_1=0\) against \(H_1:\beta_1\ne0\).
\[p=P\bigl(|T|\ge 2.2\mid H_0\bigr)=2P(T\ge2.2)=0.0397,\qquad T\sim t_{20}.\]
- Meaning: if the true slope is zero and the model assumptions hold, there is about a 3.97% chance of obtaining a t statistic at least this far from zero, in either direction.
- Repeated-sample picture: among 1,000 such samples when the null is true, about 40 would give \(t\le-2.2\) or \(t\ge2.2\).
- Decision at 5%: \(0.0397<0.05\), so reject \(H_0\). There is evidence that the slope differs from zero. At a 1% level, we would fail to reject.
- It does not mean a 3.97% probability that \(H_0\) is true, or a 96.03% probability that \(H_1\) is true.
A Confidence Interval for a Coefficient
A classical 95% coefficient interval is \(\hat\beta\pm t_{0.975,df}\,SE(\hat\beta)\). In repeated samples, this procedure covers the fixed true coefficient 95% of the time under the assumptions. It is not an interval for an individual outcome.
Statistical and Business Importance
Use reject or fail to reject, rather than “accept the null.” Discuss effect size, units, interval width, and assumptions.
Two-sided test: Ads slope = 0 versus Ads slope ≠ 0. A small p-value provides evidence that advertising spending is linearly associated with weekly revenue, under the model assumptions. Read the estimated slope for the direction and size.
It does not establish causation or show that the advertising increase pays for itself.
In-Class Practice: Does the Slope Differ from One?
Test whether the SPY slope equals 1 against a two-sided alternative. A slope of 1 means a one percentage-point increase in SPY return corresponds to a fitted one percentage-point increase in NVDA return. State the null, alternative, t statistic, degrees of freedom, p-value and conclusion at 5%.
Interactive Test: Move the Observed t
Move the observed t statistic. The alternative is different from the null value: a two-sided test. Compare the shaded probability with the Python survival-function calculation; degrees of freedom stay fixed at 20.
§5 — Point Predictions and Two Kinds of Interval
Separate a conditional mean from one new observation, and recognise interpolation and extrapolation.
Two Prediction Questions
At Ads=4, what is the mean revenue across comparable weeks? What revenue might one new week produce? The point estimate is the same, but the second question also includes individual-week variation.
Mean Confidence Interval versus Prediction Interval
The inner band describes uncertainty in the mean line. The outer band describes uncertainty for one new outcome. Under the same classical model and confidence level, the individual prediction interval is wider when residual variance is positive.
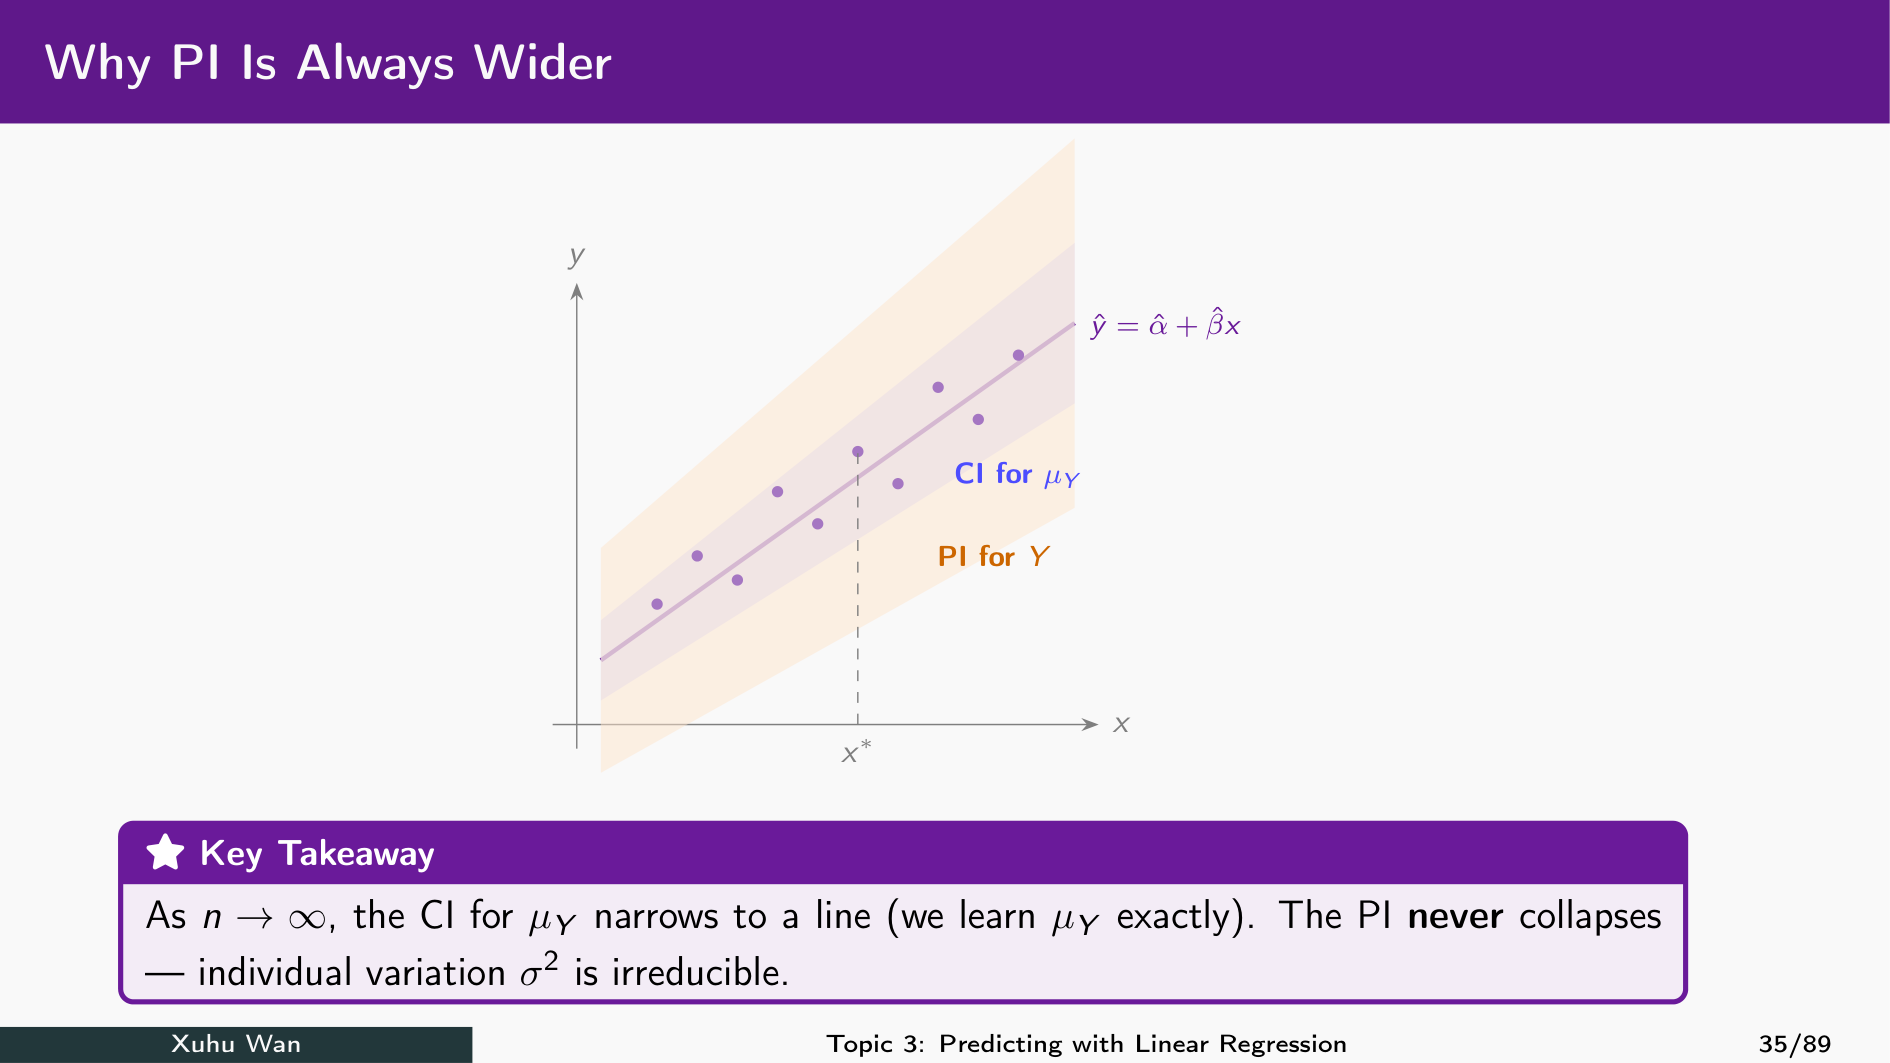
Read the Prediction Symbols
For the retail example, choose advertising of 4 thousand HKD.
| Symbol | Meaning | Retail example |
|---|---|---|
| \(x_0\) | The predictor value where we want a prediction | Ads = 4 |
| \(\mu_0=E[Y\mid X=x_0]\) | Unknown population mean outcome at this input | Average revenue across comparable weeks with Ads = 4 |
| \(\hat y_0=\hat\beta_0+\hat\beta_1x_0\) | Our estimate of that mean, read from the fitted line | Fitted average revenue at Ads = 4 |
| \(Y_0\) | One new, not-yet-observed outcome at this input | Revenue for one future week with Ads = 4 |
The subscript 0 labels the target case; it does not mean \(X=0\). A hat means estimated from the training sample.
What Does SE of the Fitted Mean Measure?
If we collected another training sample and fitted again, the line and \(\hat y_0\) would change. \(SE(\hat y_0)\) estimates the standard deviation of this mean estimator across repeated samples.
\[SE(\hat y_0)=s\sqrt{\frac{1}{n}+\frac{(x_0-\bar x)^2}{S_{xx}}},\qquad S_{xx}=\sum_{i=1}^{n}(x_i-\bar x)^2.\]
Here \(n\) is training sample size, \(\bar x\) is the training mean of \(X\), and \(S_{xx}\) measures its spread. \(s\) is regression RMSE, our estimate of the underlying noise standard deviation \(\sigma\).
For Ads = 4: \(n=8\), \(\bar x=4.5\), \(S_{xx}=42\), \(s=1.442\), giving \(SE(\hat y_0)\approx0.522\) thousand HKD. Across repeated training samples, the fitted average at Ads = 4 would vary; we estimate that variation’s standard deviation as about HKD 522. This measures how precisely we estimate the average, not how much one week’s revenue varies.
Confidence Interval: For the Average Revenue
Question: with advertising fixed at HKD 4,000, what is the average revenue across comparable weeks? The target is the unknown population mean \(\mu_0=E[Y\mid X=4]\).
\[\text{95% mean CI: }\quad \hat y_0\pm t^*SE(\hat y_0)\] \[=\hat y_0\pm t^*s\sqrt{\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}}.\]
- \(\hat y_0\): fitted average; \(SE(\hat y_0)\): uncertainty in that estimated average.
- \(t^*=t_{0.975,n-2}\): the 95% critical t value for simple linear regression. With \(n=8\), \(t^*=2.447\).
Example (HKD thousands):
\[18.405\pm2.447(0.522)\ \approx\ [17.128,\ 19.682].\]
We are 95% confident that the population average revenue at Ads = 4 lies between approximately HKD 17,128 and HKD 19,682. This interval is for the average, not one particular week.
Prediction Interval: For One New Week
Question: with advertising fixed at HKD 4,000, what revenue might one new week produce? The target is that week’s unknown outcome \(Y_0\).
\[\text{95% individual PI: }\quad\hat y_0\pm t^*\sqrt{SE(\hat y_0)^2+s^2}\] \[=\hat y_0\pm t^*s\sqrt{1+\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}}.\]
- \(SE(\hat y_0)^2\): uncertainty in the estimated average.
- Extra \(s^2\): variation from the new week’s own noise. Here \(s=1.442\) and \(t^*=2.447\).
Same example (HKD thousands):
\[18.405\pm2.447\sqrt{0.522^2+1.442^2}\ \approx\ [14.652,\ 22.157].\]
The 95% prediction interval for one new week’s revenue is approximately HKD 14,652 to HKD 22,157. It is wider than the mean CI because one week can differ from the population average. Use this interval when planning for one future week.
Ask statsmodels for Both Intervals
For \(x_0=4\), .get_prediction(new).summary_frame(alpha=0.05) returns:
| Output column | Symbol and meaning |
|---|---|
mean |
\(\hat y_0\): estimated mean revenue |
mean_se |
\(SE(\hat y_0)\): standard error of that estimated mean |
mean_ci_lower, mean_ci_upper |
95% confidence interval for the unknown mean \(\mu_0\) |
obs_ci_lower, obs_ci_upper |
95% prediction interval for one new outcome \(Y_0\) |
Both intervals are centred on \(\hat y_0\). The PI includes the new week’s own noise as well as uncertainty in the fitted mean.
Render Both Bands from the Same Fit
The numerical bands are narrowest near the centre of the observed Ads values. The outer band adds residual variation. Change alpha to 0.01 to request 99% intervals.
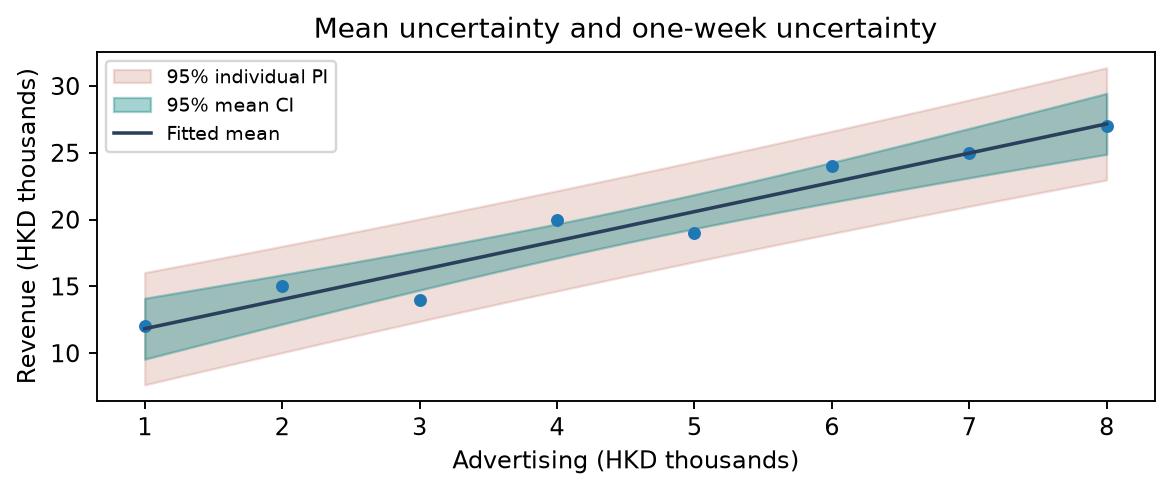
Why the Extra Term Matters
A mean confidence interval describes uncertainty about the average at \(x_0\). A prediction interval must also allow for one new observation’s own noise.
\[\text{Mean CI: }\hat y_0\pm t^*SE(\hat y_0).\] \[\text{Individual PI: }\hat y_0\pm t^*\sqrt{SE(\hat y_0)^2+s^2}.\]
\(s^2\) estimates the variance of the underlying noise. \(t^*=t_{0.975,n-2}\) is the 95% critical value for SLR. The extra \(s^2\) makes the PI wider. Both intervals use the same \(x_0\), fitted model and confidence level.
Interpolation and Extrapolation
Ads=4 lies inside the observed 1–8 range. Ads=15 lies outside it: extrapolation. A numerical prediction still exists, but the fitted relationship is not checked there by our observations.
Use the Interval for the Decision
An inventory decision for one future week needs individual-outcome uncertainty, not just a precise estimate of average demand. A 95% PI is not a worst-case bound and is conditional on the inputs and assumptions.
In-Class Practice: Mean or One Week?
Produce the mean CI and individual PI at Ads=6. Print both widths and explain which is relevant when planning stock for a single week.
Interactive Intervals: Change the Input and Confidence
Move Ads within and beyond the observed range and switch 95% to 99% confidence. Compare the fitted mean, mean CI, and individual PI for the eight-week retail model.
§6 — Residual Analysis and Unusual Observations
Use residual plots to question the model assumptions and distinguish a large residual from high leverage.
LINE Is a Diagnostic Checklist
L: linear conditional mean. I: independent errors. N: normal errors for classical exact small-sample inference. E: equal error variance. Normal X values are not required; a scatterplot alone cannot verify the full checklist.
Four Assumptions: Which Plot Should We Use?
Use residuals as observable clues about the model’s unobserved errors.
| Assumption | Visual check | What we hope to see | Warning pattern |
|---|---|---|---|
| L — Linear mean | Residuals vs fitted values (or predictor \(X\)) | Points centred near zero without a curve | U-shape, curve, systematic pattern |
| I — Independent errors | Residuals vs time / meaningful observation order | No runs, cycles or persistent pattern | Long runs above/below zero, cycles |
| N — Normal errors | Normal Q–Q plot of residuals | Points roughly follow the reference line | Systematic bending or large tail departures |
| E — Equal variance | Residuals vs fitted values; absolute residuals vs fitted values | Roughly constant vertical spread | Fan/funnel shape or rising residual magnitude |
The same residual plot checks L through its centre and E through its spread. Plots reveal warning signs; they cannot prove the assumptions.
Residuals versus Fitted Values
Look for a curved pattern or changing spread around zero. The fitted mean may be too simple if the residual pattern is systematic. Eight points are useful for explanation, but weak evidence for diagnosing a real business process.
\[\text{Horizontal: }\hat y_i\qquad\text{Vertical: }e_i=y_i-\hat y_i\qquad\text{Reference: }e_i=0.\]
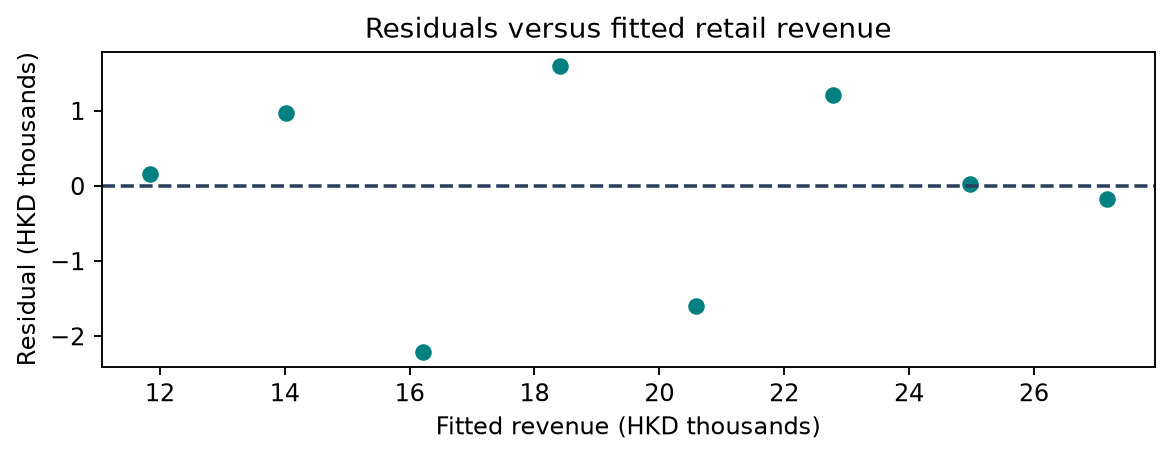
Illustration: Curvature and a Fan Shape
These constructed diagnostic examples show two warning patterns. A curved residual pattern suggests a missing shape in the mean; widening spread suggests nonconstant variance. These are illustrations, not fitted evidence about NVDA.
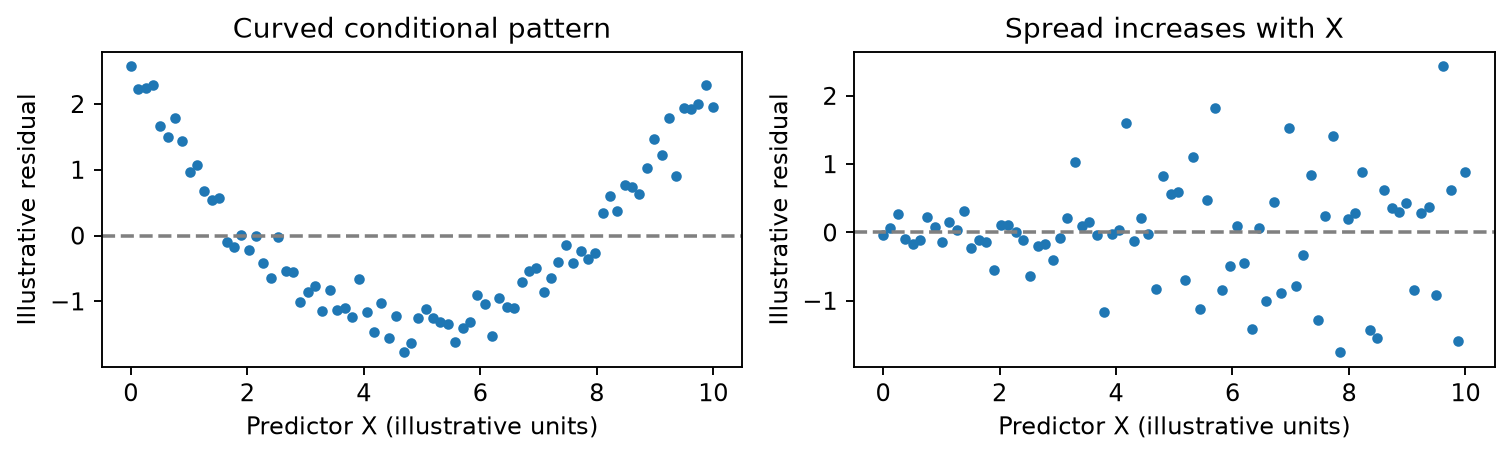
Interactive Residuals: Recognise the Warning
Switch among no clear pattern, a curve, and a widening fan. Predict what each picture suggests before revealing the explanation. These are schematic residual plots.
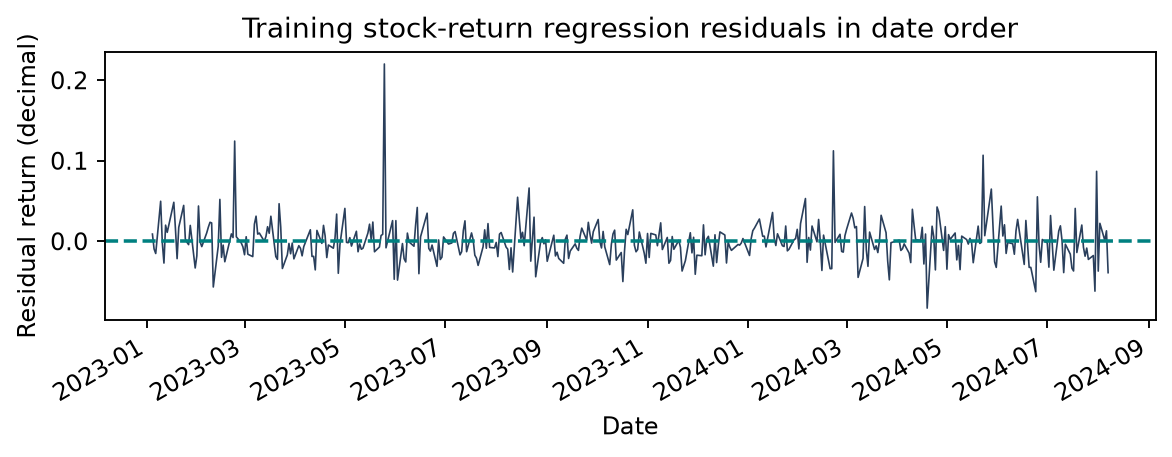
Independence: Inspect Time Order
For daily returns, plot residuals by date. Consecutive runs, persistence, or volatility bursts deserve investigation. A random-looking plot is not proof of independence.
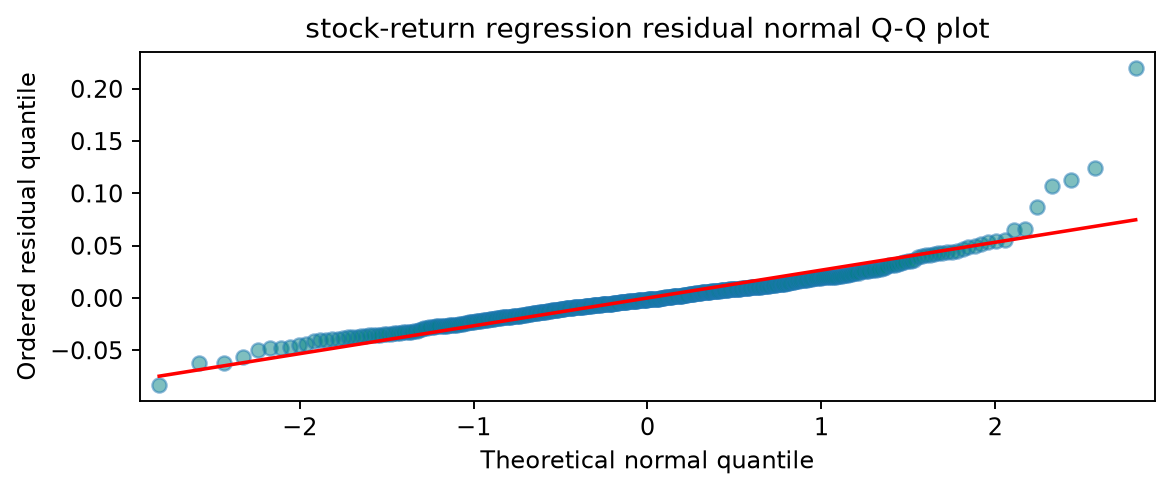
Normality: Read a Q-Q Plot
A normal Q-Q plot compares ordered residuals with normal reference quantiles. Tail deviations suggest departures from normality. The question is about errors, using residuals as a diagnostic proxy, not whether market returns themselves must be normal.
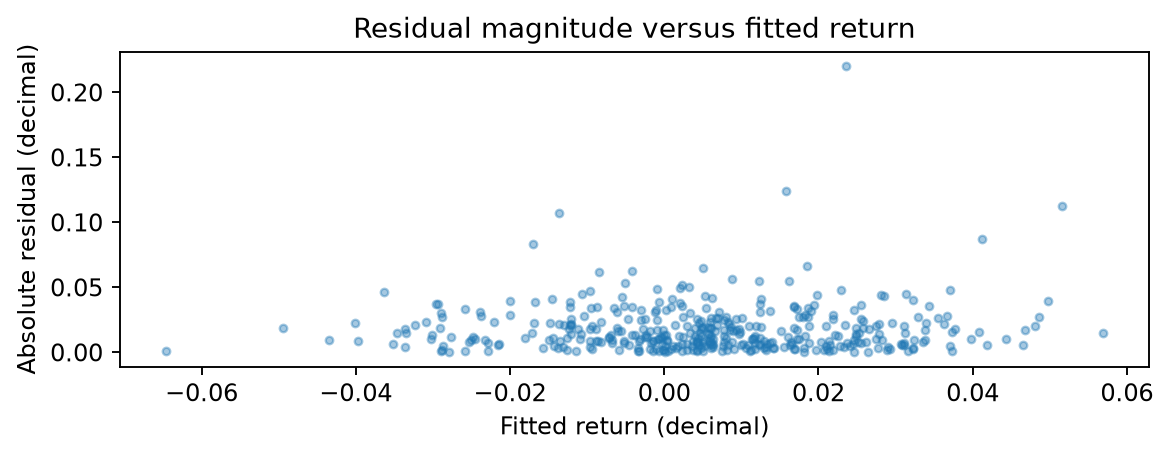
Equal Variance: Inspect the Spread
Plot absolute residual size against fitted values. A systematic rise in the spread may contradict equal variance. A constant-looking spread does not resolve independence or the correctness of the mean equation.
Outlier, Leverage, and Influence
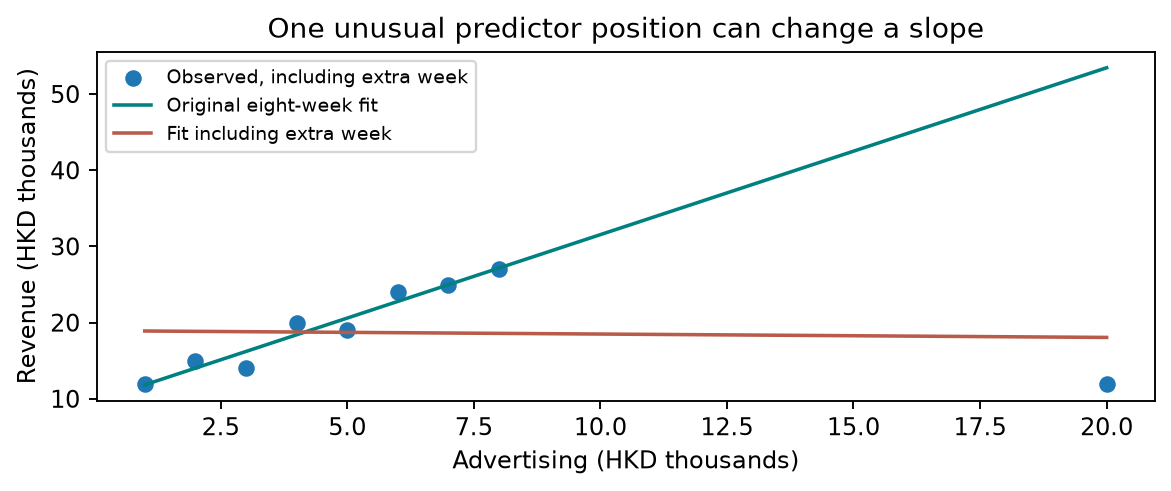
A large residual is an unusual Y relative to the fitted line. High leverage is an unusual predictor position. Influence means an observation substantially changes the fit. These are related but different ideas.
Interactive Observation: Does One Point Change the Fit?
Switch an extra observation on and off: Ads=20, Revenue=12. Its predictor is far outside the original 1–8 range. Compare slope and SSE, then explain why the point needs a business explanation.
Render the Effect of an Unusual Week
Both lines use OLS with an intercept. The extra observation changes the model, not just its correlation. Do not delete a genuine week simply to make a line look better.
In-Class Practice: Investigate a Residual
Find the retail week with the largest absolute residual. Print its complete record and explain two possible reasons for the deviation that would require additional evidence.
§7 — Multiple Linear Regression and Multicollinearity
Use city demographics to model annual pharmacy profit, interpret partial coefficients, and assess multicollinearity.
Pharmacy Profit: Why Use Several Predictors?
| Source column | Meaning and unit |
|---|---|
Profit |
Annual pharmacy profit, US dollars; the outcome Y |
Income |
City median annual salary, US dollars |
Disposable Income |
City median income after taxes, US dollars |
Birth Rate (per 1,000) |
Births per 1,000 residents |
Soc Security (per 1,000) |
Social-security recipients per 1,000 residents |
CV Death (per 100,000) |
Cardiovascular deaths per 100,000 residents |
% 65 or Older |
Residents aged 65+, in percentage points: 14 means 14% |
Location identifies a city; it is not a numerical predictor. The file contains 110 cities with observed profit and one proposed Kansas City location with no profit yet.
Read the Six-Predictor Design Table
The response is annual Profit. The design table contains an intercept column const and six demographic columns. sm.add_constant() creates the column of ones; .fit() estimates all seven coefficients together.
Partial Coefficients Have Units
Compare two otherwise identical demographic profiles. Hold the other five predictors fixed.
| Input difference | Difference in fitted annual profit, full model |
|---|---|
| Income higher by US$1,000 | About US$599 higher |
| Disposable income higher by US$1,000 | About US$2,535 higher |
| Birth rate higher by 1 birth per 1,000 | About US$1,704 higher |
| Age 65+ share higher by 1 percentage point | About US$7,714 higher |
Interactive Prediction: Hold the Other Inputs Fixed
Each line keeps the other inputs fixed. Move disposable income along it, or change the age-65+ share. Both axes use USD thousands.
R-Squared versus Adjusted R-Squared
Compare Income-only and six-predictor models on the same 110 cities. Adding inputs cannot lower training R² when both models include an intercept. Adjusted R² also accounts for the number of fitted predictors; it can fall when an added input contributes too little.
Adjusted R-Squared: Allow for the Number of Predictors
\(R^2_{adj}=1-\dfrac{SSE/(n-k-1)}{SST/(n-1)}\). Here \(n=110\), \(k=6\) and \(n-k-1=103\). The intercept is estimated but is not counted in \(k\).
MLR RMSE: Allow for All Estimated Coefficients
The course uses regression RMSE \(s=\sqrt{SSE/(n-k-1)}\). Six demographic predictors and one intercept leave 103 residual degrees of freedom. Here \(s\approx\text{US}\$13,547\) per year.
What Is Multicollinearity?
Multicollinearity is linear dependence among the predictors. If one input is nearly a linear combination of the others, little independent variation remains to estimate its separate association with profit.
In these cities, social-security recipients and the share aged 65+ move closely together.
Perfect dependence: coefficients are not uniquely identifiable. Strong imperfect dependence: coefficients can be estimated but may be imprecise.
Multicollinearity: Coefficients and Standard Errors
Strong imperfect dependence makes the separate predictor associations hard to estimate.
| What changes? | Consequence |
|---|---|
| Coefficient estimates | Small data changes can alter their size or sign; estimates depend on the other predictors included. |
| Standard errors | Coefficient variance and SE increase, other conditions held fixed. |
| Numerical stability | Near-perfect dependence can amplify rounding and numerical errors. |
Not automatic bias: imperfect multicollinearity does not itself bias OLS under a correctly specified, full-rank model with zero conditional mean error.
Multicollinearity: Tests and Confidence Intervals
Individual t-tests and coefficient intervals depend on the coefficient SE.
| What changes? | Consequence |
|---|---|
| Individual t-tests | Lower power; a useful predictor may have a large p-value after accounting for the others. |
| Coefficient confidence intervals | Wider intervals can include zero and both signs. |
| Overall F-test and R² | A significant joint test and high training R² can coexist with weak individual t-tests. |
A large p-value can reflect imprecision, rather than the absence of a useful association.
Multicollinearity: Prediction and Prediction Intervals
Individual coefficients can be uncertain while their combined prediction remains precise for familiar input combinations.
| Target | What multicollinearity means |
|---|---|
| Point prediction | Can remain stable for familiar combinations; validate accuracy on test data. |
| Mean-response CI | Can remain narrow for familiar combinations, but widen for unusual combinations. |
| New-outcome PI | Adds new-outcome noise to fitted-mean uncertainty; not automatically wide. |
Joint support matters: familiar social-security and age-share ranges do not guarantee a familiar combination. Validate predictions on representative test data.
VIF: Predict a Predictor with the Others
For each demographic input \(X_j\), fit an auxiliary regression on the other five inputs. Then \(VIF_j=1/(1-R_j^2)\). Profit is not used in this auxiliary regression. A large value signals little variation unique to that input.
Three Predictors: What Are the Auxiliary R-Squared Values?
For a smaller VIF illustration, use Income, Disposable Income and the age-65+ share. Fit three auxiliary regressions. Each takes one of these inputs as its response and the other two as predictors. Do not use Profit.
Illustration: VIF Grows Near Dependence
The relationship is nonlinear: auxiliary R² of 0.5 gives VIF=2; 0.9 gives VIF=10; 0.99 gives VIF=100. The graph illustrates the formula rather than six estimated pharmacy VIFs.
Overall F-Test: Do the Predictors Help Together?
\(H_0:b_1=b_2=\cdots=b_6=0\) versus \(H_1\): at least one slope differs from zero. Compare the six-input profit model with an intercept-only mean-profit model. The intercept is not part of the joint null.
The F Statistic Compares Explained Variation with Noise
\(F=(SSR/k)/(SSE/(n-k-1))\). Here \(k=6\) and the denominator degrees of freedom are 103. The pharmacy fit gives \(F\approx53.12\).
Individual t-Test: Does This Input Help Given the Others?
For social-security recipients, test \(H_0:b_j=0\) against \(H_1:b_j\ne0\). The two-sided test asks whether this partial linear association differs from zero after including the other five inputs.
Overall F-Test and Individual t-Tests
A large overall F can coexist with small absolute t statistics for some inputs. The six demographics jointly help explain profit, while some separate associations remain imprecise.
In this sample, F≈53.12, while the social-security t statistic is about −0.43. The overall F-test and an individual t-test answer different questions.
If LINE Assumptions Fail: What Changes?
Predict Profit with Every Required Input
The final row is the proposed Kansas City store. Supply all six demographic inputs in the same column order as the fitted design. Add the intercept column explicitly for this single new row.
In-Class Practice: A Controlled Demographic Comparison
Start with the proposed city’s inputs. Predict with the full model, then increase Disposable Income by US$1,000 while keeping every other input unchanged. Predict the difference before running. Does it equal 1,000 times that input’s fitted slope?
§8 — Test-Set Accuracy and Honest Prediction Scope
Evaluate frozen training fits on later data and identify the information each prediction requires.
Predict the Reserved Test Dates
Use the training model to predict the later test rows. Do not fit another model on the test data before assessing the original model. The matching const/SPY design is required.
Animated Evaluation: Fit, Freeze, Predict, Check
Step through a small holdout demonstration: train on weeks 1–6 and test on weeks 7–8. Keep the fitted coefficients frozen while later outcomes are revealed. Assume the test Ads inputs are supplied.
RMSE Measures Residual Variation
In ISOM2600, RMSE means residual standard error \(s\), an estimate of the underlying noise standard deviation. For SLR, \(s=\sqrt{\frac{1}{n-2}\sum_{i=1}^{n}(y_i-\hat y_i)^2}\). For MLR, replace \(n-2\) by \(n-k-1\). Here \(n\) is the sample size used to fit the model, and \(k\) excludes the intercept.
Test R-Squared Can Be Negative
The conventional test R² compares test SSE with deviations from the test sample mean. A negative value means the predictions perform worse than that test-mean reference. The test mean is a retrospective denominator, not a forecast available before the test period.
\[R^2_{test}=1-\frac{\sum_{test}(y_i-\hat y_i)^2}{\sum_{test}(y_i-\bar y_{test})^2}.\]
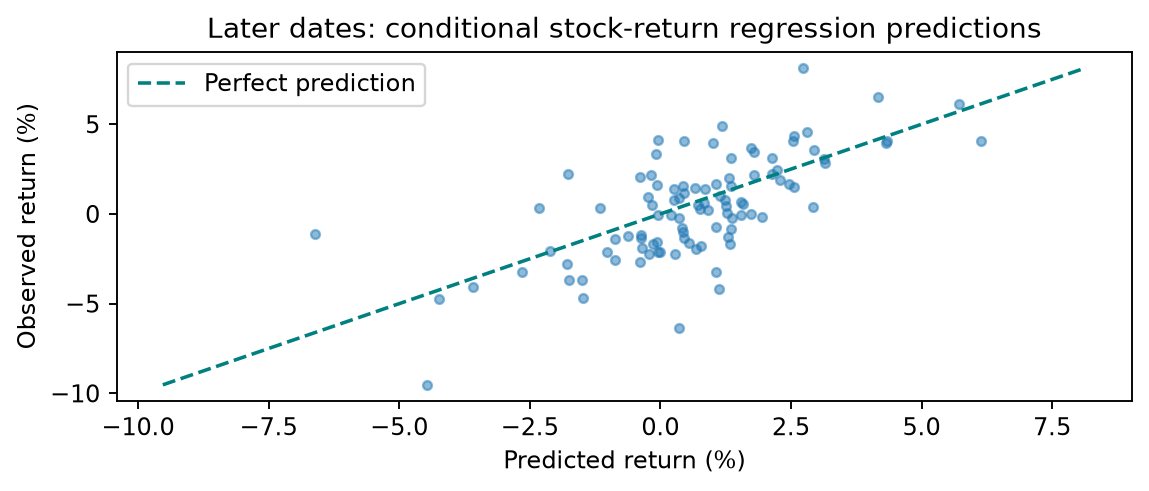
Render Actual versus Predicted Test Returns
The diagonal represents perfect prediction. Distance from it is prediction error. A narrow range of predictions beside a wide range of actual returns shows remaining uncertainty.
Read Training and Test Performance Carefully
Compare adjusted R² (higher is better) and RMSE (lower is better) on training and test records. Keep the training coefficients fixed when predicting the test set.
\[\text{Adjusted }R^2=1-\frac{SSE/(n-k-1)}{SST/(n-1)},\qquad RMSE=\sqrt{\frac{SSE}{n-k-1}}.\]
Calculate \(SSE\), \(SST\) and \(n\) separately for each set; \(k\) is the number of predictors excluding the intercept (here \(k=1\)). \(SST\) uses that set’s own mean. RMSE below is in percentage points of daily return.
Strong training scores but weaker test scores can suggest overfitting, a changed relationship or a difficult test period. Weak scores on both sets can indicate an inadequate model or substantial noise. There is no universal safe gap.
Underfitting and Overfitting
Underfitting: the model is too simple to capture important patterns in the data.
| Underfitting | Useful fit | Overfitting |
|---|---|---|
| Misses important patterns | Captures the repeatable pattern | Fits sample-specific noise too closely |
| Usually poor on both training and new test records | Performs reasonably on new records | Excellent training fit can deteriorate on new records |
A straight line can underfit a curved relationship. Test performance being better than training performance does not define underfitting. Choose complexity using validation; reserve an untouched test set for final evaluation.
Interactive Complexity: Better Training Fit, Worse New Predictions
Compare three models on the same constructed data. Circles are training records; crosses are held-out validation records. Here the true mean is a straight line. The flexible curve uses powers of X only to illustrate overfitting; learning polynomial syntax is not required.
In-Class Practice: Write a Supported Recommendation
Report training and test adjusted R-squared and RMSE for the frozen training model. Interpret both metrics and state what same-day SPY input the model requires.
§9 — Extension: Pharmacy Profit and Model Comparison
Compare demographic models on identical cities, select with training and validation, and evaluate the frozen choice once on held-out cities.
One Predictor or Six Demographic Inputs?
Could Income alone predict annual pharmacy profit well enough, or do the other demographics add useful information? Use the original 110 observed-profit cities. Shuffle once with a fixed random seed, then allocate 60% to training, 20% to validation and 20% to the final test.
Fit the Six-Predictor Pharmacy Model
Fit only the 66 training cities. Keep an intercept and all six demographic columns. The validation and test profits do not enter estimation.
Compare Models on Identical Validation Cities
Fit Income-only and six-predictor models on the same training cities. Evaluate both on the same 22 validation cities. The model with the better training fit need not have the better validation score.
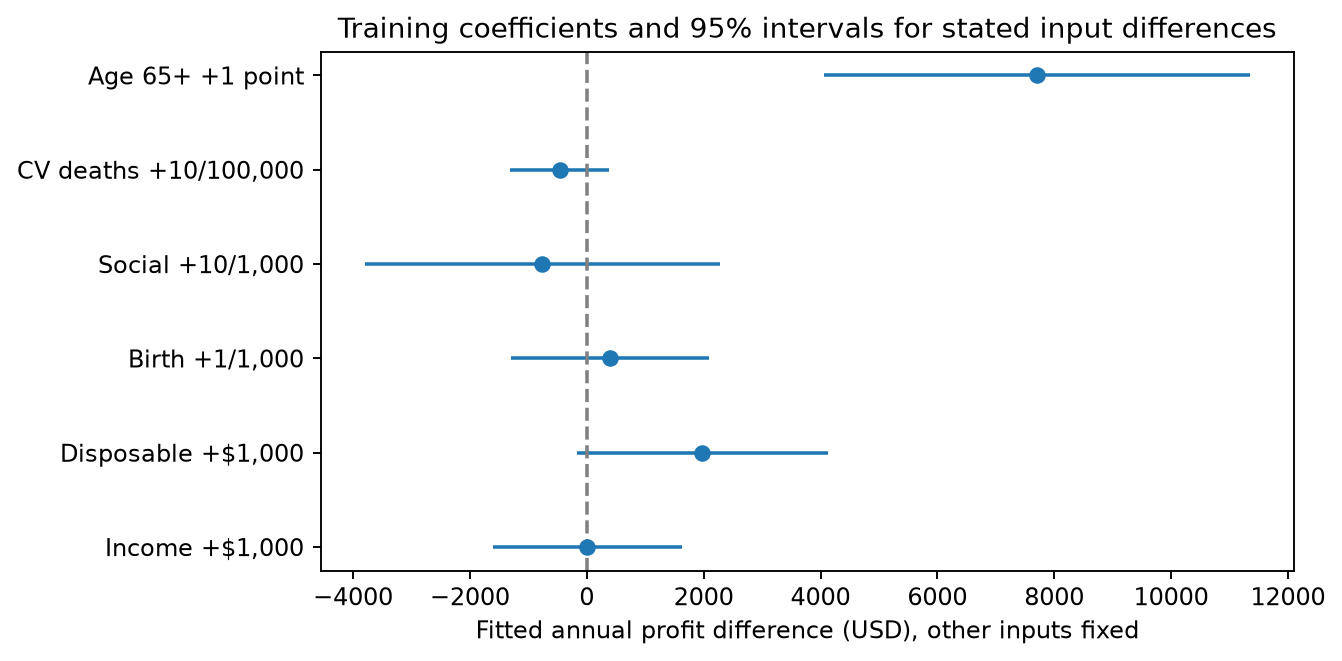
Plot Coefficient Intervals for Stated Input Differences
Raw slopes have different units. Instead of comparing them as if the inputs shared a scale, specify the input difference: US$1,000 income, one birth per 1,000, ten recipients per 1,000, ten CV deaths per 100,000, or one percentage point aged 65+.
Check Dependence in the Training Design
Measure predictor dependence using only the training cities. Each VIF regresses one demographic input on the other five. Do not include Profit or use the held-out cities to fit these auxiliary models.
Model Search Uses Training and Validation
Training: 66 cities → estimate candidate coefficients.
Validation: 22 cities → compare candidates and choose the predictor list.
Final test: 22 cities → evaluate the frozen choice once.
The Kansas City proposal has no observed profit and is not an accuracy check.
Best Subset: Compare Every Candidate Model
There are six possible inputs. Try every nonempty subset: 6 one-input models, 15 two-input models, 20 three-input models, 15 four-input models, 6 five-input models and 1 six-input model: 63 candidates. Every candidate includes an intercept.
Interactive Best Subset: Compare Validation Scores
Each dot is one candidate fitted on the training cities and scored on validation cities. Select a criterion and inspect the five leading candidates. Disposable + Birth + Age 65+ is preferred here. Income, Disposable, Birth, Social, CV deaths and Age 65+ abbreviate the six source columns.
Run All 63 Pharmacy Subsets
combinations(features, k) produces every k-input list. Fit each model on training data, then store its validation adjusted R² and RMSE s. Sort once to inspect the candidates.
Read Large p-Values Before Proposing a Shorter List
The training-only full fit gives Income the largest individual p-value. Its separate association is imprecise after the other inputs are included. This is a reason to examine alternatives, not proof that Income has no relationship with profit.
Refit with an Explicit Shorter Predictor List
Write the proposed shorter list explicitly: Disposable Income, Birth Rate and the age-65+ share. Fit it on training cities and compare it with the six-input model on the same validation cities. The final test remains untouched.
A Large p-Value Does Not Prove a Variable Is Useless
A coefficient test measures evidence about a partial association. It does not directly measure held-out accuracy or business relevance. A large p-value can arise from predictor overlap, limited sample size or a small conditional association.
Use the model’s purpose, sensible inputs and validation performance together.
Evaluate the Frozen Models on Held-Out Cities
The predictor choice is now fixed. Use the 22 test cities to report final held-out performance, without refitting on their profits. Show Income-only, all six inputs and the selected three-input model as a final comparison.
Interpret the Pharmacy Holdout Results
On these test cities, the selected three-input model has adjusted R²≈0.810 and RMSE s≈US$15,870. The full model gives ≈0.761 and US$17,782; Income-only gives ≈−0.145 and US$38,910.
The selected model’s test score is better than its validation score. That alone is not a definition of underfitting. Different small samples can have different difficulty.
In-Class Practice: Predict with the Selected Inputs
Predict annual profit for the proposed Kansas City store using the selected three-input training model. Supply disposable income US$22,642, birth rate 14.4 per 1,000 and age-65+ share 11.4%. Then increase the age share by one percentage point while holding the other two inputs fixed.
Appendix A — Statistical Foundations
Optional theory background: variables, samples, normal distributions, estimation and testing. High-school algebra is enough.
A.1 — Why We Need Statistics
A delivery company wants to know its average delivery time. Measuring every delivery may be impossible. We use a smaller set of deliveries to learn about the whole group.
Our route: data → sample → estimate → uncertainty → interval → test. No calculus or programming is needed.
A.2 — Variables and Data
A variable is a characteristic that can take different values. Data are the values we actually record.
| Delivery | Time (minutes) | Area | Late? |
|---|---|---|---|
| 001 | 26 | East | No |
| 002 | 34 | West | Yes |
| 003 | 30 | East | No |
Time, Area and Late? are variables. The recorded entries are data. Delivery is an identifier.
A.3 — Numerical and Categorical Variables
| Type | Example | Meaningful calculation |
|---|---|---|
| Numerical | Delivery time: 26, 34, 30 | Mean time |
| Categorical | Area: East, West | Number in each area |
A category coded 1 or 2 is still a label. Averaging area codes does not produce an average location.
If Late? is coded 1 for Yes and 0 for No, what does its mean measure?
The fraction of deliveries that are late. This works because the coding was explicitly defined as a 0/1 indicator.
A.4 — Population: The Whole Group
A population is the complete group we want to understand. Here it is all deliveries made by this company during the target month.
Define the group and time period before calculating. Next month may have a different population.
A.5 — Sample: The Observations We Use
A sample is the set of observations selected from the population. Its size is \(n\).
If we randomly choose 36 deliveries from the target month, \(n=36\). Their average helps us estimate the population average. A sample is one set of observations, not a probability curve.
A.6 — A Large Sample Can Still Be Biased
Suppose we record only deliveries near the warehouse. Their average may be too low for all deliveries. More nearby deliveries do not fix this selection problem.
A simple random sample gives every delivery an equal chance of selection. The formulas below assume independent observations from the same population; a small sampling fraction makes sampling without replacement approximately independent.
A.7 — Population Parameters and Sample Statistics
| Quantity | Population: usually unknown | Sample: calculated |
|---|---|---|
| Mean | \(\mu\) (mu) | \(\bar{x}\) (x-bar) |
| Standard deviation | \(\sigma\) (sigma) | \(s_x\) |
A parameter describes the population. A statistic is calculated from a sample. Different samples can give different statistics.
A.8 — The Sample Mean
\[ \bar{x}=\frac{x_1+x_2+\cdots+x_n}{n} \]
- \(x_i\): the recorded value for observation \(i\); \(i\) is just a row number.
- \(n\): sample size.
- \(\bar{x}\): add the values and divide by their count.
For 26, 30 and 34 minutes: \(\bar{x}=90/3=30\) minutes.
A.9 — Standard Deviation Measures Spread
Two samples can have the same mean and different spreads. A deviation is \(x_i-\bar{x}\). Squaring prevents positive and negative deviations cancelling.
A.10 — Sample Variance and Standard Deviation
\[ s_x^2=\frac{\sum_{i=1}^{n}(x_i-\bar{x})^2}{n-1},\qquad s_x=\sqrt{s_x^2} \]
The symbol \(\sum\) means “add these terms”. Variance has squared units; SD returns to minutes.
For 26, 30, 34: \(s_x^2=32/2=16\) minutes² and \(s_x=4\) minutes. We use \(n-1\) because the sample was also used to estimate its mean.
A.11 — A Random Variable
Before a delivery is selected, let \(X\) be its delivery time. We do not know its value yet. A random variable assigns a number to an uncertain outcome.
After observing it, we might record \(x=34\). Uppercase \(X\) describes the uncertain quantity; lowercase \(x\) is one realised value.
A.12 — A Probability Distribution
A probability distribution describes which values a random variable can take and how likely they are.
For a continuous quantity, probability is area under a curve over an interval. The entire area is 1, or 100%. Curve height is density, not the probability of exactly one value.
For a continuous delivery-time model, what is the probability of exactly 30.000… minutes?
Zero. A single point has no area. A range such as 29.5 to 30.5 minutes can have positive probability.
A.13 — A Normal Random Variable
\[ X\sim N(\mu,\sigma^2) \]
This means \(X\) follows a normal distribution: a symmetric bell-shaped curve.
- \(\mu\) is its centre (mean).
- \(\sigma>0\) is its standard deviation (spread).
- The second entry, \(\sigma^2\), is variance.
We use \(N(30,6^2)\) as an imagined delivery-time model. Real delivery times need not be normal.
A.14 — Interactive Normal Curve
Move the mean: the bell shifts. Increase SD: the bell spreads and becomes lower. The shaded area within one SD of the mean stays about 68.27%.
Predict the change before moving a slider.
A.15 — Standardise with a Z-Score
\[ Z=\frac{X-\mu}{\sigma}\sim N(0,1) \]
A z-score says how many population SDs a value lies above or below the mean. With \(\mu=30\) and \(\sigma=6\):
- \(x=36\) gives \(z=1\): one SD above the mean.
- \(x=18\) gives \(z=-2\): two SDs below the mean.
About 95% of a normal distribution lies between \(z=-1.96\) and \(z=1.96\).
A.16 — Different Samples Give Different Means
Imagine choosing three deliveries, recording their mean, then starting again with a new sample. The population stays the same, but the selected values change.
A.17 — A Sampling Distribution
Take a sample of size \(n\) → calculate one sample mean → repeat with fresh samples.
The distribution of those means is the sampling distribution of \(\bar{X}\). Each value represents a whole sample, rather than one delivery.
A.18 — Animate Repeated Samples
Click Draw sample or Play / pause. Dots show the current deliveries; the histogram collects one mean per sample. Increase \(n\) and restart: the distribution of means becomes narrower.
A.19 — Standard Error of the Mean
\[ SE(\bar{X})=\frac{\sigma}{\sqrt{n}} \]
Standard error (SE) is the SD of a statistic across repeated samples. It measures sampling uncertainty in the estimate.
If \(\sigma=6\): \(n=9\) gives SE=2 minutes; \(n=36\) gives SE=1 minute. Quadrupling the sample size halves the SE.
A.20 — SD and SE Describe Different Things
| Quantity | Variation of what? | In our imagined population |
|---|---|---|
| Population SD \(\sigma\) | Individual delivery times | 6 minutes |
| SE of \(\bar{X}\) | Means across samples of 36 | 1 minute |
A precise estimated average does not mean individual deliveries are all alike.
Does sampling more deliveries make the population SD shrink?
No. It reduces uncertainty in the sample mean. It does not make individual delivery times less variable.
A.21 — When Is the Mean Approximately Normal?
If the population is normal, the mean of independent observations is normal for any \(n\).
For a non-normal population with finite variance, the Central Limit Theorem often makes the mean approximately normal when \(n\) is sufficiently large. Strong skewness or outliers may require much larger samples. There is no universal “\(n=30\) fixes everything” rule.
A.22 — A Confidence Interval for the Mean
One estimate is not enough: add a margin of error on each side. When population SD \(\sigma\) is known and the sample mean is normal or approximately normal:
\[ \text{95% CI for }\mu:\quad \bar{x}\ \pm\ 1.96\frac{\sigma}{\sqrt{n}} \]
“\(\pm\)” means calculate a lower and an upper endpoint.
A.23 — A Confidence Interval in Minutes
For \(n=36\), \(\bar{x}=32\) and known \(\sigma=6\):
\[ SE=6/\sqrt{36}=1,\qquad CI=32\pm1.96=[30.04,33.96] \]
The target is population mean delivery time \(\mu\), not the time of one new delivery.
A.24 — Unknown Population SD: Use Student’s t
Usually \(\sigma\) is unknown. Estimate it by the sample SD \(s_x\). This adds uncertainty, so use a t multiplier:
\[ \bar{x}\ \pm\ t^*\frac{s_x}{\sqrt{n}},\qquad df=n-1 \]
\(t^*\) is a positive cutoff determined by confidence level and degrees of freedom \(df\). For \(n=36\), a 95% t interval uses \(t^*\approx2.030\) instead of 1.96. Exact for independent normal observations; approximate under suitable large-sample conditions.
A.25 — Animate 95% Confidence
Repeat the sampling-and-interval procedure. The vertical line is the fixed population mean; each horizontal interval comes from a new sample.
About 95% of intervals cover the true mean over many repetitions—not necessarily exactly 95 out of every 100.
A.26 — What 95% Confidence Means
The method captures the true parameter in 95% of repeated samples under its assumptions. After a particular interval is calculated, the fixed parameter is either inside it or outside it.
A 95% CI does not contain 95% of individual deliveries and does not assign a 95% probability to the fixed parameter being in this realised interval.
A.27 — Hypothesis Testing
Question: is population mean delivery time different from 30 minutes?
\[ H_0:\mu=30\qquad H_1:\mu\ne30 \]
- Null hypothesis \(H_0\): the reference claim we test.
- Alternative \(H_1\): the difference we are looking for.
Assume the null and the sampling model, then ask how unusual our sample result would be.
A.28 — The Test Statistic
\[ z_{\mathrm{obs}}=\frac{\bar{x}-\mu_0}{\sigma/\sqrt{n}}=\frac{32-30}{1}=2 \]
- \(\mu_0=30\): the mean specified by the null.
- \(z_{\mathrm{obs}}\): observed distance from the null, measured in SEs.
The sample mean is two SEs above the null mean. We compare it with a standard normal curve under \(H_0\).
A.29 — What a P-Value Means
For a two-sided test, count outcomes at least as far from the null in either direction. For \(z_{\mathrm{obs}}=2\):
\[ p=P(Z\le-2)+P(Z\ge2)\approx0.0455 \]
If \(H_0\) and the model are correct, about 4.55% of repeated samples would give a test statistic at least this extreme. This is not the probability that \(H_0\) is true.
A.30 — Significance and Decisions
Choose significance level \(\alpha_{\mathrm{sig}}\) before inspecting the result. At \(\alpha_{\mathrm{sig}}=0.05\), \(p=0.0455<0.05\), so reject \(H_0\) in this example.
- \(p\le\alpha_{\mathrm{sig}}\): reject the null.
- \(p>\alpha_{\mathrm{sig}}\): do not reject; this does not prove the null.
The significance level is a long-run false-rejection rate under \(H_0\), not the chance our particular conclusion is wrong. A small p-value alone does not show a large business effect.
A.31 — One-Sided and Two-Sided Questions
| Question chosen in advance | Null | Alternative | Count which tail? |
|---|---|---|---|
| Different from 30? | \(\mu=30\) | \(\mu\ne30\) | Both |
| Greater than 30? | \(\mu\le30\) | \(\mu>30\) | Right |
| Less than 30? | \(\mu\ge30\) | \(\mu<30\) | Left |
For one-sided tests, calculate the reference distribution at the boundary \(\mu=30\).
A.32 — Interactive P-Value Tails
Choose the research question, then move the observed z-statistic. The shaded probability is the p-value. At \(z=2\): two-sided \(p\approx0.0455\), greater-than \(p\approx0.0228\), less-than \(p\approx0.9772\).
A.33 — Choose the Direction Before Seeing the Data
Use a one-sided test only when the question was directional before observing the data. Do not switch sides or switch to one-sided testing to obtain a smaller p-value.
With a preselected “less than 30” alternative, a mean far above 30 is not evidence for that alternative. A one-sided p-value is not always half the two-sided one.
A.34 — A Confidence Interval and a Test
For the same two-sided procedure, a 95% CI and a test at 5% agree:
- Null value outside the CI → reject.
- Null value inside the CI → do not reject.
Our CI \([30.04,33.96]\) excludes 30 and our two-sided p-value is 0.0455. They are two ways to describe the same evidence.
Can we compare a 95% two-sided interval with any one-sided test and expect the same decision?
No. The confidence level, sidedness and statistical procedure must match.
A.35 — Statistical Foundations: Check Your Understanding
| Term | What it describes |
|---|---|
| Population / sample | Target group / selected observations |
| Parameter / statistic | Population quantity / calculated estimate |
| SD / SE | Spread of observations / sampling spread of an estimate |
| Confidence interval | Uncertainty about a parameter |
| P-value | Tail probability under the null model |
Next: the same ideas applied to a regression slope and predicted revenue.
Appendix B — Linear Regression Theory
Optional theory background: fitted lines, coefficient uncertainty, confidence intervals and prediction intervals. Read Appendix A first if these terms are new.
B.1 — Regression Uses the Same Statistical Ideas
A sample mean estimates one average. A regression estimates an average at each input value.
In this example, advertising spending \(x\) and weekly revenue \(Y\) are both in HKD thousands. We will fit a line, describe coefficient uncertainty, then distinguish average revenue from one new week.
B.2 — The Population Model
\[ Y=\beta_0+\beta_1x+\varepsilon \]
- \(x\): advertising input.
- \(Y\): uncertain revenue at that input.
- \(\beta_0\): population intercept.
- \(\beta_1\): population slope.
- \(\varepsilon\) (epsilon): individual deviation from the average; \(E(\varepsilon\mid x)=0\).
Thus the population mean is \(E(Y\mid x)=\beta_0+\beta_1x\). “\(\mid x\)” means at the given input \(x\).
B.3 — One Input, Several Possible Outcomes
At the same advertising input, revenue can differ because of weather, customer demand and other unobserved influences.
The straight line describes average revenue, while noise describes the spread around it.
B.4 — The Fitted Line
\[ \hat{y}(x)=\hat{\beta}_0+\hat{\beta}_1x \]
A hat means “estimated from our sample”.
- \(\hat{\beta}_0,\hat{\beta}_1\): estimated intercept and slope.
- \(\hat{y}(x)\): estimated average of \(Y\) at input \(x\).
For this sample, \(\hat y(x)\approx9.6429+2.1905x\). Displayed coefficients are rounded; calculations use full precision. An extra HKD1,000 of Ads is associated with HKD2,190.5 higher fitted revenue. Association alone does not establish causation.
B.5 — Observations and the Fitted Line
Each dot is one observed week. The line supplies a fitted value at that week’s input. The vertical gaps are residuals: observed minus fitted.
B.6 — Residuals and Squared Error
\[ e_i=y_i-\hat y(x_i),\qquad SSE=\sum_{i=1}^{n}e_i^2 \]
- \(e_i\): residual for observed week \(i\).
- \(SSE\): sum of squared residuals; it is never negative.
A residual above the line is positive; below is negative. Squaring stops the signs cancelling. Fitting by ordinary least squares (OLS) means choosing the line with the smallest SSE.
B.7 — Animate the Least-Squares Fit
Move the intercept and slope. Watch the residual segments and SSE change. Click Animate OLS fit to move to the least-squares line.
The minimum is for the total squared error, not for each residual separately.
B.8 — Population Noise and Sample Residuals
\[ \varepsilon_i=y_i-(\beta_0+\beta_1x_i),\qquad e_i=y_i-(\hat\beta_0+\hat\beta_1x_i) \]
The true population line is unknown, so we cannot observe its noise values directly. Residuals use the estimated line. They help us estimate the noise spread and examine assumptions.
B.9 — Assumptions Behind the Formulas
| Assumption | Plain-language meaning |
|---|---|
| Linear mean | The population average follows a straight line |
| Independent errors | One observation’s error does not determine another’s |
| Constant variance | Noise has the same SD \(\sigma\) at every input |
| Normal errors | At a fixed input, errors follow a normal distribution |
These give exact small-sample t tests and intervals. The predictor \(x\) itself need not be normal; \(x\) must vary. Normality concerns errors conditional on \(x\).
B.10 — RMSE Estimates the Noise SD
\[ s=\mathrm{RMSE}=\sqrt{\frac{SSE}{n-2}} \]
This course uses RMSE for the residual standard error. It estimates the unknown noise SD \(\sigma\), in revenue units. We use \(n-2\) because simple linear regression estimates an intercept and a slope.
In our eight-week sample: \(SSE=12.4762\), so \(s=\sqrt{12.4762/6}=1.4420\) HKD thousands.
B.11 — A Slope Also Has a Sampling Distribution
Take a new sample of weeks and refit: the fitted slope changes. The population slope stays fixed.
\(SE(\hat\beta_1)\) estimates the SD of slope estimates across repeated samples. It measures the precision of the estimated slope, not the spread of individual revenues.
B.12 — Standard Error of the Slope
\[ S_{xx}=\sum_{i=1}^{n}(x_i-\bar x)^2,\qquad SE(\hat\beta_1)=\frac{s}{\sqrt{S_{xx}}} \]
- \(S_{xx}\): total squared spread of the observed inputs.
- \(s\): RMSE, the estimated noise SD.
Our sample has \(S_{xx}=42\), so \(SE(\hat\beta_1)=1.4420/\sqrt{42}=0.2225\). Across repeated comparable samples, estimated slopes typically vary around the true slope on a scale of about 0.2225 revenue units per Ads unit.
B.13 — Standard Error of the Intercept
\[ SE(\hat\beta_0)=s\sqrt{\frac1n+\frac{\bar x^2}{S_{xx}}} \]
The intercept is the estimated mean at \(x=0\). If the observed inputs are far from zero, it is harder to estimate reliably.
Here \(n=8\), \(\bar x=4.5\), \(S_{xx}=42\), giving \(SE(\hat\beta_0)=1.1236\). Do not give a business interpretation at zero if zero is outside the meaningful range.
B.14 — A Confidence Interval for a Coefficient
\[ \hat\beta_j\ \pm\ t^*SE(\hat\beta_j),\qquad df=n-2 \]
\(j=0\) means intercept; \(j=1\) means slope. For our sample, \(df=6\) and a 95% interval uses \(t^*=2.4469\).
Slope CI: \(2.1905\pm2.4469(0.2225)=[1.6460,2.7349]\).
This estimates the population slope: the association is roughly HKD1,646 to HKD2,735 per extra HKD1,000 in Ads under the model.
B.15 — A Two-Sided Test for a Coefficient
\[ H_0:\beta_j=0,\qquad H_1:\beta_j\ne0 \]
\[ t_{\mathrm{obs}}=\frac{\hat\beta_j-0}{SE(\hat\beta_j)},\qquad df=n-2 \]
For the slope: \(t=2.1905/0.2225\approx9.8446\), with two-sided \(p\approx0.0000633\). Under a zero population slope and our model assumptions, such a large absolute t-statistic is very rare. Reject at 5%; this alone does not prove causation.
B.16 — Interactive Coefficient Test and Interval
Keep \(df=6\) and adjust the estimated slope or its SE. Compare the two-sided p-value, 95% CI and the null value zero. A larger SE means less precise estimation.
These controls illustrate hypothetical regression outputs; they do not refit the eight observed weeks.
B.17 — A Coefficient CI and Its Test Agree
For a matching two-sided 5% t test and 95% t interval:
- CI excludes zero → coefficient differs significantly from zero.
- CI includes zero → insufficient evidence of a nonzero coefficient.
An interval shows both uncertainty and plausible effect sizes.
B.18 — Multiple Linear Regression
\(Y=b_0+b_1x_1+\cdots+b_kx_k+e\). The pharmacy model predicts annual Profit from six demographic inputs, so k=6. Each fitted slope compares profiles with the other five inputs held fixed. The intercept is estimated but is not counted in k.
B.19 — RMSE and Degrees of Freedom in Multiple Linear Regression
\[ s=\mathrm{RMSE}=\sqrt{\frac{SSE}{n-k-1}},\qquad df=n-k-1 \]
We estimate \(k\) slopes plus one intercept. With \(n=20\) observations and \(k=2\) predictors, \(df=17\).
For coefficient \(j\): CI is \(\hat\beta_j\pm t^*SE(\hat\beta_j)\) and the test uses \((\hat\beta_j-0)/SE(\hat\beta_j)\) with the same df. Software calculates the SEs; the simple-linear-regression slope SE formula does not apply unchanged.
B.20 — Individual t Tests and the Overall F Test
| Test | Null | Alternative |
|---|---|---|
| Individual t | \(\beta_j=0\) | \(\beta_j\ne0\) |
| Overall F | \(\beta_1=\cdots=\beta_k=0\) | At least one slope is nonzero |
An individual t test asks about one predictor with the others included. The overall F test asks whether the predictor set helps explain the mean at all. A significant F test does not say that every coefficient is significant.
B.21 — A New Input and a Fitted Mean
\[ x_0=4,\qquad\hat y_0=\hat y(4)\approx18.4048 \]
The subscript 0 labels the prediction case; it does not mean \(x_0=0\). Here the input is Ads=HKD4,000.
\(\hat y_0\) estimates average revenue at this input: HKD18,404.8. It is also our point prediction for one new week, but that week has extra uncertainty.
B.22 — Standard Error of the Fitted Mean
\[ SE(\hat y_0)=s\sqrt{\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}} \]
This measures how much our estimated average at \(x_0\) varies across repeated training samples. It is smallest near the average observed input \(\bar x\).
At \(x_0=4\): \(SE(\hat y_0)=0.5218\) HKD thousands. This is smaller than \(s=1.4420\), which measures individual noise.
B.23 — Confidence Interval for Average Revenue
\[ \hat y_0\ \pm\ t^*SE(\hat y_0) \]
For whom? The population average of all comparable weeks with Ads fixed at HKD4,000.
\(18.4048\pm2.4469(0.5218)=[17.1279,19.6816]\) HKD thousands.
This interval measures uncertainty about the mean response, not the variability of one future week.
B.24 — One New Week Has Extra Uncertainty
A prediction for one future week has two sources of uncertainty:
- We estimated the population mean line using a sample.
- The future week has its own unpredictable noise.
A prediction interval includes both, so it is wider than a confidence interval for the average at the same input and confidence level.
B.25 — Prediction Interval for One New Week
\[ SE_{\mathrm{pred}}=s\sqrt{1+\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}} \]
\[ \text{95% PI}:\quad \hat y_0\ \pm\ t^*SE_{\mathrm{pred}} \]
The extra 1 accounts for the new week’s noise. At \(x_0=4\), the PI is \([14.6524,22.1571]\) HKD thousands. It targets one independent new response at the specified input, under the model assumptions.
B.26 — Interactive Confidence and Prediction Intervals
Move \(x_0\) and change the confidence level. Compare the narrow mean CI with the wider individual PI. Both widen away from \(\bar x=4.5\).
Click Animate new weeks: dots vary around the fitted mean. This is a teaching simulation treating the fitted line and RMSE as the generating model.
B.27 — Three Different Interval Targets
| Interval | Target | Units |
|---|---|---|
| Coefficient CI | A population slope or intercept | Coefficient units |
| Fitted mean CI | Average revenue at given \(x_0\) | Revenue units |
| Prediction interval | One new week’s revenue at \(x_0\) | Revenue units |
All three involve estimation uncertainty. Only the prediction interval adds the new observation’s individual noise.
B.28 — What the Intervals Cannot Fix
Intervals rely on the regression model and sampling assumptions. They do not repair a biased sample, a curved mean fitted as a straight line, dependent errors, or a changed business relationship.
Extrapolation: predicting outside the observed input range can fail even when the displayed formula produces a narrow-looking interval.
More data can reduce estimation uncertainty; it does not eliminate individual noise.
B.29 — Regression Theory: Check Your Understanding
- The fitted line estimates the average of \(Y\) at an input.
- OLS chooses coefficients that minimise SSE.
- RMSE \(s\) estimates underlying noise SD.
- Coefficient SEs, CIs and t tests describe estimation uncertainty.
- A mean CI concerns an average; a PI concerns one new outcome.
Return to Sections 2, 4 and 5 to connect these ideas with the Python results.
Chapter Summary
| Task | Python pattern | Interpretation check |
|---|---|---|
| Inspect association | .corr(), scatterplot |
Pair rows, inspect curvature; zero r does not rule out association |
| Fit a line | sm.OLS(y, sm.add_constant(X)).fit() |
Intercept, slope, residual |
| Quantify coefficient uncertainty | .bse, .pvalues, .conf_int() |
Specify null and assumptions |
| Predict | .predict(), .get_prediction() |
Mean CI versus individual PI |
| Diagnose | .resid, .get_influence() |
LINE, leverage, influence |
| Add predictors | Multiple-column X, VIF | Holding others fixed; dependence |
| Evaluate later records | Test adjusted R² and RMSE | Frozen fit, known inputs |
| Compare models | Adjusted R² and RMSE | Same outcome and rows; preserve final test |
Before recommending a decision: state the outcome, units, observation period, prediction inputs, error measure, uncertainty, and limitations.
Prof. Xuhu Wan · HKUST ISOM · Introduction to Business Analytics