Select, clean, create measures, explore, and follow time
Prof. Xuhu Wan
What This Chapter Covers
A DataFrame holds a business table. We will select records, handle missing data, create business measures, explore patterns, and calculate rolling and cumulative results.
Chapter Roadmap
Section
Business task
1
Read a table and its columns
2
Select relevant records
3
Handle incomplete information
4
Create measures, sort results, and read method chains
5
Count categories and describe distributions and relationships
6
Compare groups and choose charts
7
Organise dates and measure changes
8
Follow recent trends and accumulated results
Our Retail Orders
A small gift retailer wants to understand its first week of November orders in Central and Kowloon. One row is one order line. Quantity is recorded in units; UnitPrice and UnitCost are HKD per unit. These are classroom records, not a sample used to make claims about a named company.
Read O101: 2 units sold at HK$120 per unit, with product cost HK$70 per unit. Predict its revenue before running a calculation.
§1 — DataFrames and the First Look
Identify what a row represents, load a table, and inspect its structure before analysing it.
Cross-sectional Data versus Time Series
First ask: what does one row represent?
Cross-sectional data
Time-series data
Compare
Different entities in the same period
The same entity or measure over time
Example
One row per customer this month
One row per day of a store’s sales
Row order
Usually no natural time sequence
Chronological order matters
Missing values
Consider comparable entities and the variable’s distribution
Respect time and what was known then
Train/test split
Random split can suit independent entities
For forecasting: earlier train, later test
Our order-line table contains transactions. Aggregating sales by day creates a time series.
A Column Is a Series
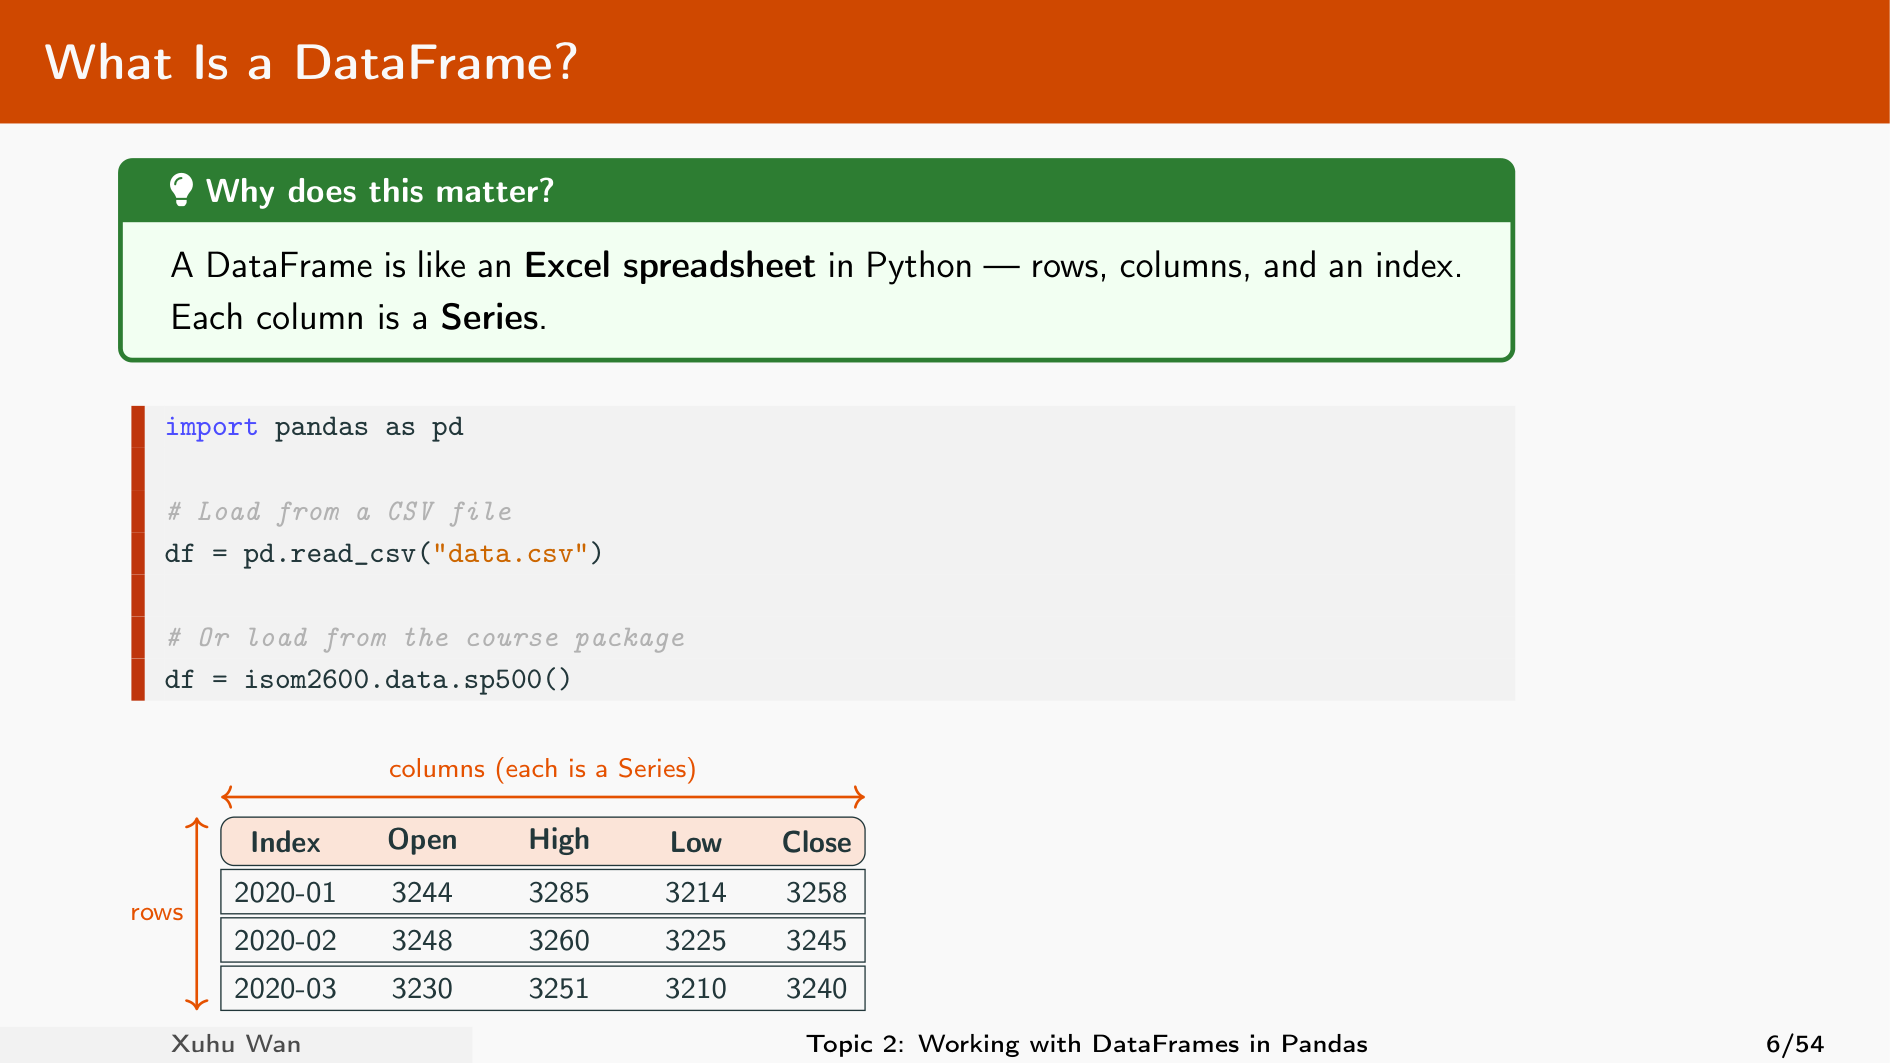
A Series is one labelled variable. A DataFrame places related Series in columns and gives them a shared row index.
Rows, Columns, and the Index
Read across a row for one observation. Read down a column for one variable. Index labels identify rows; numerical positions count from 0.
Create a Small DataFrame
pd.DataFrame({...}) uses dictionary keys as column names and lists as column values. Supply an index= when meaningful row labels are available.
Change one price, then run the box again. Check which cell changes.
Load a CSV File
A CSV stores a table as text separated by commas. pd.read_csv() returns a DataFrame. The first line normally supplies column names.
DataFrame Attributes
Attributes describe the table and have no parentheses..shape is (rows, columns); .columns and .index contain labels; .dtypes gives one data type per column.
DataFrame Methods
Methods perform a task and use parentheses..head(2) returns the first two rows. .tail(2) returns the last two. .info() prints a structural summary.
.info() prints its report; avoid wrapping it in print(...), which would also print its return value, None.
Column Types and Business Meaning
Quantity is numerical, Store is categorical, and Date initially contains text. A number-like code may still be an identifier. Data type and business meaning both matter.
In-Class Practice: Inspect an Order Table
Print the row count, return the final two records, and name the column containing unit prices. Explain whether the index identifies stores or orders.
Hint: .shape[0], .tail(2), and .columns. Expected: four rows, last labels C and D, prices in Price.
§2 — Selecting Columns, Rows, and Cells
Select records by label, position, or conditions; update cells; and split independent customers or time-ordered observations into training and test sets.
One Column or a Smaller Table
df["Units"] returns a Series. df[["Units", "Price"]] returns a DataFrame. The inner brackets form a list of column names.
Select Rows with iloc and Row Positions
.iloc[0] selects the first row. .iloc[1:3] selects positions 1 and 2. The stop position 3 is excluded, just as in list slicing.
Select Rows with loc and Index Values
.loc["B"] selects the row whose index value is B. .loc["B":"D"] includes both index values B and D in this ordered example. Index values and row positions may select different rows.
Select Rows and Columns Together
The selection before the comma chooses rows; the selection after it chooses columns.
Selection
Select rows using
Select columns using
df.loc[rows, columns]
Index values
Column names
df.iloc[rows, columns]
Row positions
Column positions
Positions start at 0 for iloc. A colon : means all rows or all columns in that slot.
Predict the scalar in the last line: row C, column Price gives 35.
Select Data with Condition
Compare a column with a threshold to get one True/False value per row. df.loc[mask] selects the rows where the condition is True. Display the mask before using it.
Change the threshold from 3 to 4. Predict which labels remain.
Interactive Filter: Change the Threshold
Move the threshold and watch which order lines remain. Then reproduce that selection in the Python box below.
Label
Store
Units
Keep?
A
Central
2
False
B
Kowloon
1
False
C
Central
4
True
D
Kowloon
3
True
Retained labels: C, D
Combine Conditions with Parentheses
Use & for AND and | for OR. Put each comparison in parentheses. Python and and or do not combine whole Boolean Series this way.
Membership, Ranges, and Negation
.isin([...]) checks membership. .between(2, 3) includes both endpoints by default. ~ reverses a Boolean mask.
Update Selected Cells with loc
Use .loc[rows, column] = value to update the intended cells directly. If you need a separate result table, create a .copy() and edit that table.
Train/Test Splitting Depends on the Data
Training data develop a model. Test data check it on held-out observations.
Prediction task
Defensible starting split
Why?
New independent customers from the same population
Randomly assign customers to train or test
Row position has no natural time meaning
Future sales from a time series
Sort dates; train on earlier dates, test on later dates
Future records are unavailable when training
Repeated records from a customer require attention to groups. Predicting future behaviour also requires attention to time.
Split first, then learn cleaning values from training data only.
Cross-sectional Example: Split Customers Randomly
Assume one row per independent customer in the same month. frac=0.75 selects 75% (six of eight) for training; the remaining customers form the test set.
Why use random_state=42? Computers make pseudo-random choices using an algorithm. A seed is the starting value for that algorithm.
Same seed + same data and row order: in the same Python setup, the same customers are selected each time. This is reproducible random sampling.
Different seed: the selected customers may change. 42 is arbitrary; it is not a special or better number.
No fixed seed: repeated runs may select different customers.
Fixing the split lets classmates reproduce your results and lets you compare models on the same training/test customers.
Run the box twice: both seed-42 training lists match. Changing to 7 selects a different set in this example. Six customers train; two test; no customer appears in both. This same-month example does not evaluate a forecast of future months.
Time-series Example: Train Earlier, Test Later
Sort rows by date. Use the first 75% for training and the last 25% for testing.
cut is an ordinary variable that stores where to split the rows. It is the number of training rows and the row position where the test set begins.
len(sales) counts the rows: 8.
0.75 * len(sales) calculates 75% of them: 6.0.
int(...) converts that result to the integer 6, so cut = 6.
Selection
Row positions when cut = 6
Dates
sales.iloc[:cut]
0–5: the first six rows; stop before position 6
1–6 November
sales.iloc[cut:]
6–7: start at position 6 and continue to the end
7–8 November
Positions start at 0, so position 6 is the seventh row. cut is a position, not a date or an index value.
1–6 November: train → 7–8 November: test. Six earlier days train; two later days test. Do not shuffle a future-forecast evaluation.
In-Class Practice: A Purchasing List
Select Central orders with at least two units. Return only Units and Price. Predict the row labels before running your code.
Expected labels: A and C. Hint: combine two conditions, then use .loc[mask, [...]].
§3 — Missing Data and Cleaning Decisions
Identify incomplete information and explain how a cleaning decision changes the records used in an analysis.
Missing Sales and Zero Sales
An unknown sales value does not establish zero sales. A recorded zero is an observed value. Pandas uses missing-value markers such as NaN, None, and pd.NA, depending on the column type.
Detect and Count Missing Values
.isna() returns a Boolean table. Summing it counts True entries. .notna() identifies available observations.
Find Incomplete Records
Select records whose Sales value is missing, then investigate the original record. A missing-value report should identify affected observations.
Missing Values Change the Denominator
The Sales mean uses three observed values: (100 + 0 + 300) / 3. len(df) counts rows; .count() counts non-missing values.
An all-missing sum can be misleading: use .sum(min_count=1) when an unknown total should remain missing.
Drop Rows: All Columns or a Subset
dropna() removes rows with any missing entry. dropna(subset=["Sales"]) checks Sales only. Explain why the retained sets differ.
dropna: Rows versus Columns
axis=0 drops affected rows. axis=1 drops affected columns. Removing a column can remove information from every record, so inspect the result.
Compare Filling Assumptions
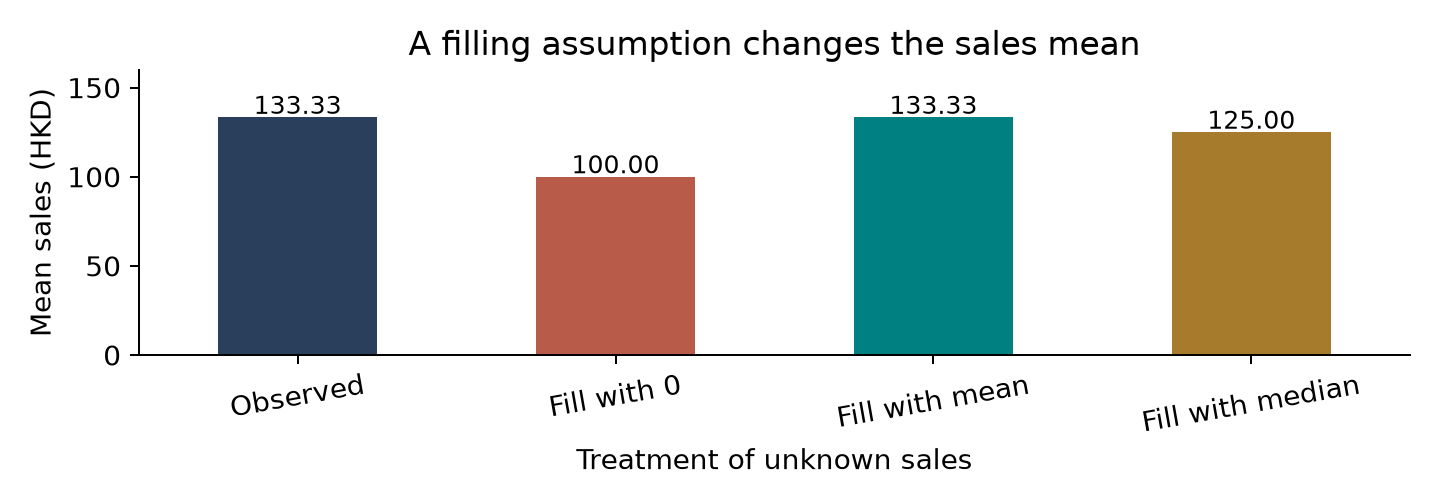
A zero, mean, or median fill makes a different assumption. Compare the resulting means before deciding which, if any, is defensible.
Does comparing these results tell us which filling assumption is justified? Explain what else we need to know.
Cross-sectional Data: Mean, Median, or Mode?
Cross-sectional data compare different customers, stores, or products in the same period. If filling is justified, choose by the variable and its observed distribution.
Fill with
When to consider it
Example
Mean (average)
Numeric; roughly symmetric, without influential outliers
Delivery days near a typical value
Median (middle value)
Numeric; skewed or with extreme values
Customer spending with a few large purchases
Mode (most frequent value)
Categorical; a common category is a defensible guess
Payment method: Card or Cash
These are starting rules, not proof. Investigate why data are missing. Do not forward-fill from an unrelated customer.
Apply Mean, Median, and Mode to Different Columns
Each row is a different customer in the same month. Predict the three fills for row D. .mode() returns a Series; .iloc[0] selects its first value.
Expected fills: 3 days, HK$110, Card. These are assumptions, not observations. If modes tie or a column is entirely missing, investigate before choosing a fill.
Time Series: Why Forward, Not Backward?
In this course, use forward fill only for time series of the same entity, sorted by time, when the last value remains applicable.
A service fee stays valid until a new fee is announced. Read this timeline left to right:
Fee (HKD)
Mon 2 Nov
Tue 3 Nov
Wed 4 Nov
Thu 5 Nov
Recorded update
10
Missing
12
Missing
Forward fill: earlier → later
10
10 ← Monday
12
12 ← Wednesday
Backward fill: earlier ← later
10
12 ← Wednesday
12
Missing
On Tuesday, 10 is already known; Wednesday’s 12 is still in the future. Backward fill leaks future information into a forecast made on Tuesday.
Forward Fill Uses a Previous Value
For this fee time series, .ffill() carries an earlier value forward; .bfill() brings a later value backward. Sort dates first and compare Tuesday in both columns.
A leading gap stays missing with forward fill. A trailing gap stays missing with backward fill. Do not carry values between unrelated customers or stores.
Negation with Missing Values
For this float Series, ~(x > 3) also keeps the missing entry. If the question asks for observed values no greater than 3, include .notna() explicitly.
The missing entry is not evidence that its value is small.
In-Class Practice: A Cleaning Recommendation
Keep records with observed Sales even if Rating is missing. Print the before/after row counts and total observed sales. Explain why you have retained the zero-sales record.
Expected: 4 rows before, 3 after, observed total HK$400. The missing rating does not prevent a sales calculation.
§4 — Feature Engineering and Modifying Tables
Create business measures whose formulas, units, and handling of missing values you can explain.
A Feature Is a Variable Used in Analysis
An existing column can be a feature. We can also derive a new variable from existing columns. Revenue, gross profit, and order-size labels answer different business questions.
Revenue: Multiply Corresponding Rows
Columns are Series, so arithmetic acts element by element and aligns row labels. An explicit loop is unnecessary for this calculation.
Change O101’s Quantity from 2 to 3. Predict its new Revenue before running.
Product Cost and Gross Profit
ProductCost = Quantity × UnitCost. GrossProfit = Revenue − ProductCost. This excludes rent, salaries, and other operating expenses.
Gross Margin and a Zero Denominator
Gross margin is GrossProfit / Revenue. A zero-revenue record has an undefined margin. Copy Revenue, then use .loc to replace non-positive denominators with None before dividing. Pandas displays these missing numerical values as NaN.
loc: Select Rows or Update Selected Values
Use .loc in two ways:
Select:orders.loc[positive, "Revenue"] returns only the positive-revenue rows A and C.
Assign:denominator.loc[denominator <= 0] = None changes the zero value to missing in a copied Series. All three index values remain.
Selection returns 2 rows; assignment keeps 3: B is absent from selected but remains as NaN in denominator. The original Revenue column still contains zero for B.
Labels with a Short Comprehension
Revisit Chapter 1: label observed orders as Large when Revenue >= 200, and Standard otherwise. This example has complete revenue values.
A two-branch label is only appropriate when its branches cover all intended cases.
Labels That Preserve Missing and Zero Values
Initialise a clear label, then use .loc for observed positive, zero, and negative values. An unknown return should remain Unknown.
Change Column Names and Drop Columns
Use the .columns attribute to assign a list of column names in their current order. Use .copy() first to preserve the original table. .drop(columns=[...]) returns a table without the specified columns.
Sort Rows: Ascending or Descending
by="Price" chooses the sorting column. axis=0 reorders whole rows. ascending=True means smallest first; ascending=False means largest first. There is no descending= argument.
Predict the descending labels: A, B, D, C. Store and Price move together; the original row labels stay attached.
Sorting axis: Reorder Rows or Columns
Argument
Default when omitted
What it controls
axis
axis=0
Reorder whole rows using values in a named column. Use axis=1 to reorder columns using a named row.
ascending
ascending=True
Put smaller values first. Use ascending=False to put larger values first.
With neither argument supplied, .sort_values(by="Monday") sorts rows by Monday from smallest to largest.
Default row order: Central, Kowloon. Descending row order: Kowloon, Central. Descending column order using Central: Tuesday, Monday.
Sort a Series and Place Missing Values
A selected column is a Series: use .sort_values() without by. Its labels stay attached. Missing values go last by default, even for descending order; na_position="first" moves them first.
Descending observed values are A = 120, D = 60, C = 35. Moving B does not fill its missing value.
Method Chaining: Pass the Result On
A chain passes each returned object to the next method. First sort the table, then take its first two rows. Read left to right; in a multiline chain, read top to bottom.
df → sorted DataFrame → first two rows. Both versions return A and B. The dot calls the next method on the previous result.
Build a Readable Three-Step Chain
Task: find the two largest observed revenues. Step 1 removes unknown revenues (4 → 3 rows). Step 2 sorts those 3 rows. Step 3 keeps the first 2. Write the three calls as one expression and read from left to right.
Expected: C = 300, D = 200. All three methods return DataFrames. Change .head(2) to .head(1) and predict the result.
The Order of Methods Changes the Question
Sort → head: find the largest two orders in the whole table. Head → sort: rank only the first two recorded orders. The same method names can answer different questions.
First result: B, C. Second result: B, A. Predict both before running; C is already excluded when .head(2) runs first.
Check the Returned Object Before Chaining
df["Revenue"] returns a Series; .dropna() returns another Series; .sum() returns one number. Stop when you have the answer. A next method must be supported by the returned object.
Both totals are 600. Keep chains short; split them into named steps when the intermediate result needs checking.
Compare Two Ways to Rescale a Feature
Let x be one Sales value. Calculate the reference values from the same Sales Series.
Comparison
Min-max scaling
Z-score standardisation
Formula
(x - min) / (max - min)
(x - mean) / std
What it measures
Position within the observed range
Distance from the mean in standard-deviation units
A result of 0 means
The observed minimum
The observed mean
A result of 1 means
The observed maximum
One standard deviation above the mean
Range for these input values
0 to 1
No fixed bounds; values can be negative
Required denominator
max - min > 0
std > 0
Both methods rescale values; neither makes a distribution normal. Here std is the sample standard deviation returned by .std().
In-Class Practice: A Margin Calculation
Calculate revenue and gross profit for each record. Then print the label of the order with the largest gross profit. Explain the units.
Expected gross profits: A = 100, B = 54, C = 40 HKD. A ranks first.
§5 — Exploratory Data Analysis
Describe typical values, variation, unusual observations, and relationships using meaningful units and denominators.
Business Questions Before Statistics
How large is a typical order? How much do values vary? Are unusual orders driving the average? Which variables move together? State the question before choosing the method.
Read describe One Statistic at a Time
df.describe() calls a DataFrame method and returns a new DataFrame of summary statistics. For a table containing numbers and text, it summarises the numeric columns by default. Here, we select Revenue and GrossProfit, then summarise each column separately.
Output row
What it tells us
count
Number of observed (non-missing) values
mean
Arithmetic average
std
Sample standard deviation: how spread out the values are
min
Smallest observed value
25%
First quartile: the 25th percentile
50%
Median: the 50th percentile
75%
Third quartile: the 75th percentile
max
Largest observed value
Missing values are excluded separately for each column. A recorded zero is included. The original table is unchanged.
Mean, Median, and a Large Order
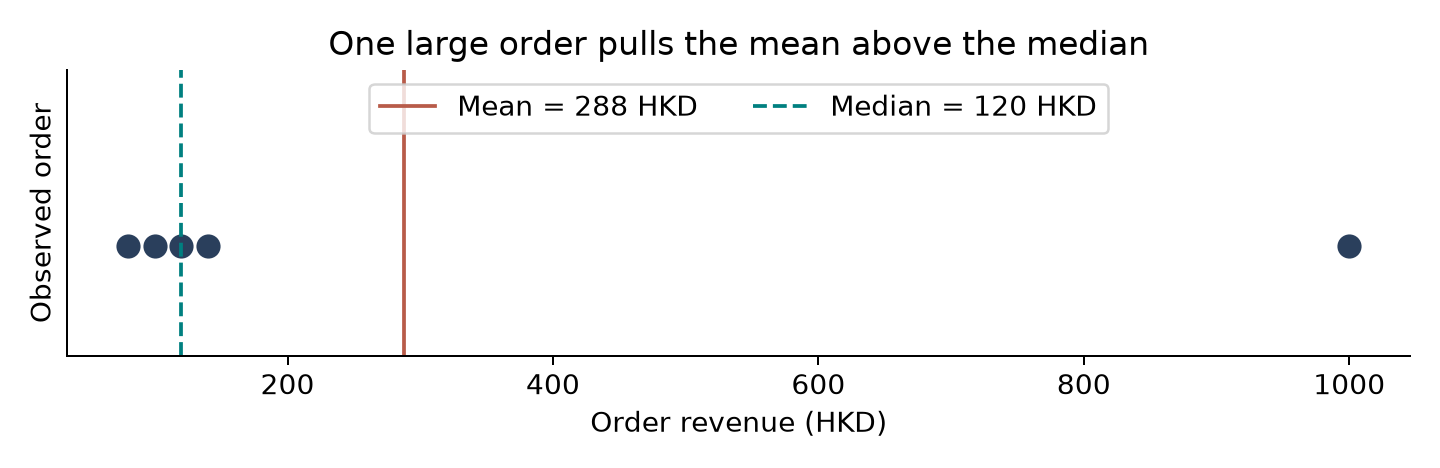
One large order can move the mean substantially. Compare the mean and median, then inspect the distribution rather than declaring a large observation an error.
Change 1000 to 200. Predict which summary changes more.
Spread, Quantiles, and Extremes
Use .std() for spread, .quantile(0.75) for a quartile, and .min() / .max() for extremes. Pandas uses sample standard deviation (ddof=1) by default.
Understanding axis: Rows and Columns
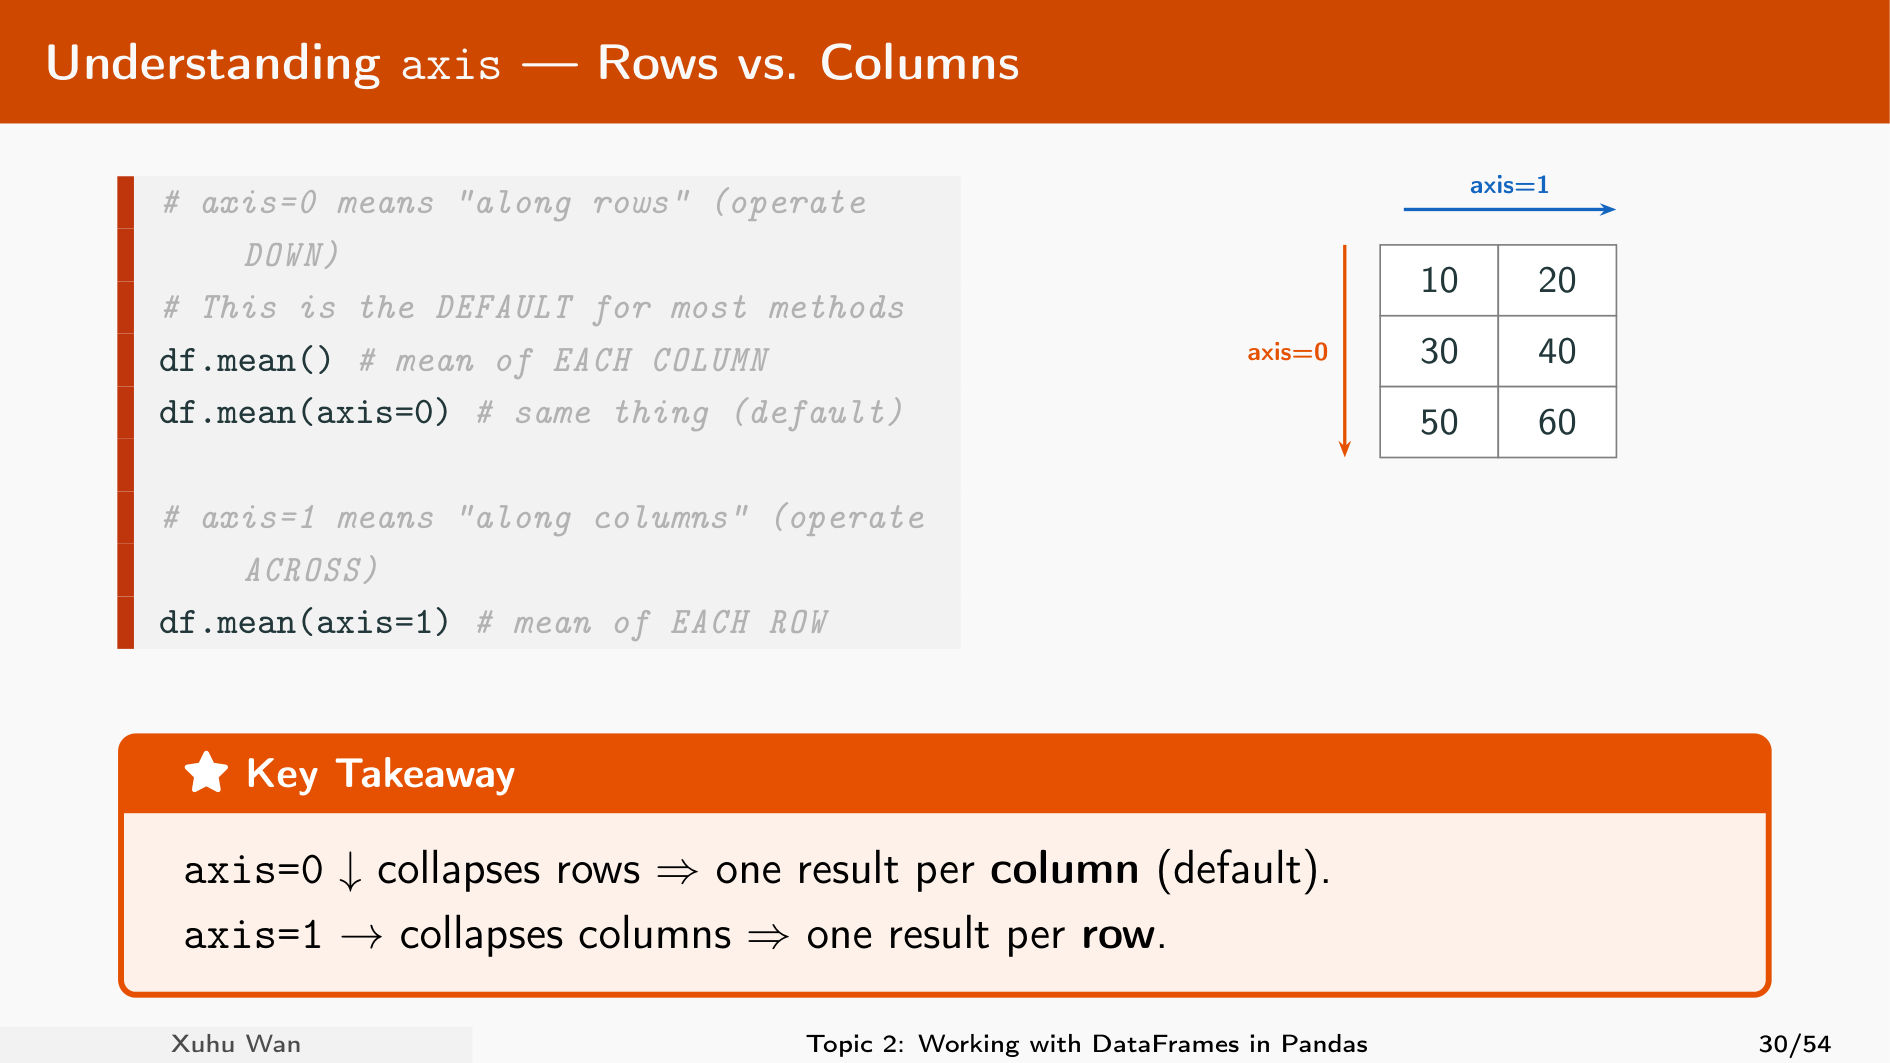
For these reductions, axis=0 operates down rows and returns one result per column. axis=1 operates across columns and returns one result per row.
axis in a Table with Comparable Units
Both columns contain sales in HKD. Sum down rows to get totals by day; sum across columns to get totals by store. Combining prices and trading volumes in one mean or standard deviation would mix units.
Store
Monday (HKD)
Tuesday (HKD)
Central
100
150
Kowloon
200
250
Monday = 300 HKD; Tuesday = 400 HKD
value_counts: Count Each Category
.value_counts() returns a Series: its index contains category labels and its values contain frequencies. It counts records, not revenue. By default, the most frequent categories come first and missing entries are excluded.
Gifts appears 3 times; Stationery and Accessories appear once each. Five categories are observed across six records.
value_counts: Include Missing Categories
value_counts() uses dropna=True by default, so missing values are not counted. categories.value_counts() and categories.value_counts(dropna=True) give the same result. Use dropna=False to include missing entries in the frequency counts.
Default total: 5. With dropna=False: 6, including one missing category. This option counts the gap; it does not fill it.
value_counts: Shares and Percentages
normalize=True divides each frequency by the number of included records. With the default missing-value exclusion, Gifts has 3/5 = 60%. Including the missing category changes this to 3/6 = 50%.
Always say “share of observed categories” or “share of all records”. The denominator determines which population each percentage describes.
Chain Counts, Sorting, and Top Categories
Read this chain as categories → frequency Series → descending frequencies → top two. sort_values now sorts the counts, not the original category names.
Top two: Gifts = 3, Stationery = 2. value_counts() already sorts descending, so .value_counts().head(2) gives the same top two here.
Correlation Needs a Scatterplot
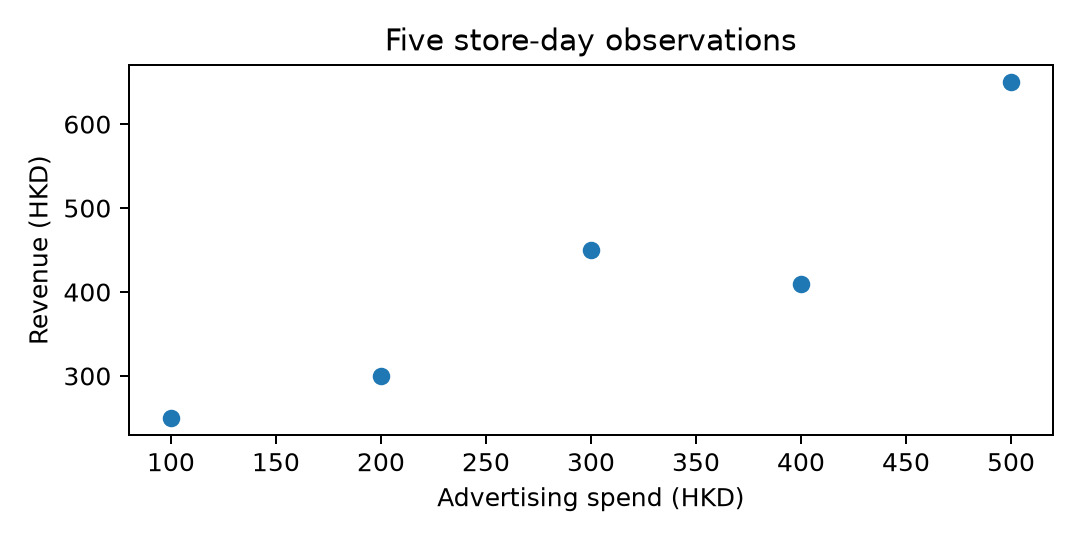
Correlation describes association. A high correlation alone does not establish causation. plt.scatter(x, y) plots one point for each paired observation: advertising spend on the horizontal axis and revenue on the vertical axis.
In-Class Practice: A Supported Finding
Calculate the mean, median, and largest order value. Write one sentence explaining why the mean alone could mislead a manager describing a typical order.
Expected: mean 288, median 120, maximum 1000 HKD. The largest order raises the mean substantially.
§6 — Business Charts
Select each store or category with a condition, calculate its summary, and choose a chart that answers the business question.
Individual Orders and Group Summaries
Work one store at a time: select its Revenue values with .loc, inspect the selected rows, then call .sum(). Repeat the same steps for the other store.
Group Totals and Group Averages
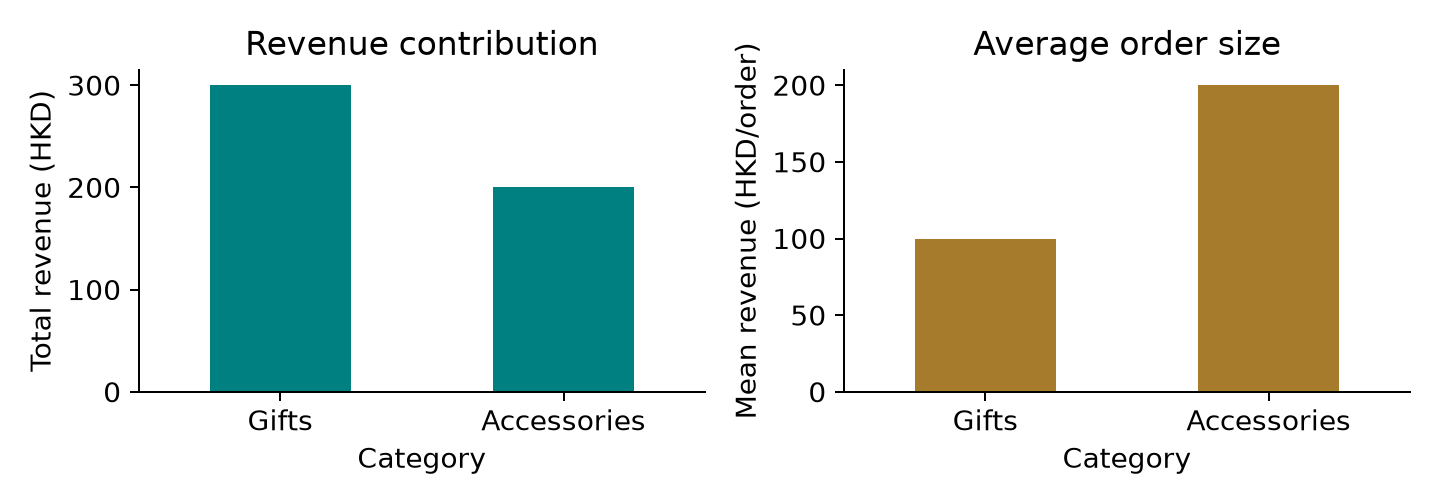
Total revenue measures contribution to sales. Mean revenue measures average order size. A group with more orders can rank differently on these measures.
Group Size and Available Values
Select each store separately. len(central) counts all selected entries; central.count() counts observed values. The mean uses only observed values.
One Category, Three Simple Calculations
First select Gifts revenue. Then calculate the count, total, and average on separate lines. Change "Gifts" to "Stationery" and run again.
Plot as a Method of DataFrame and Series
In 1.5, plt.plot(x, y) and plt.scatter(x, y) are functions: we pass the data to Matplotlib. In 2.6, we call .plot() on the pandas Series or DataFrame that contains the data.
Pandas call
What it draws
series.plot()
A line: Series index on x, values on y
df.plot(kind="scatter", x="AdSpend", y="Revenue")
A scatterplot using the two named columns
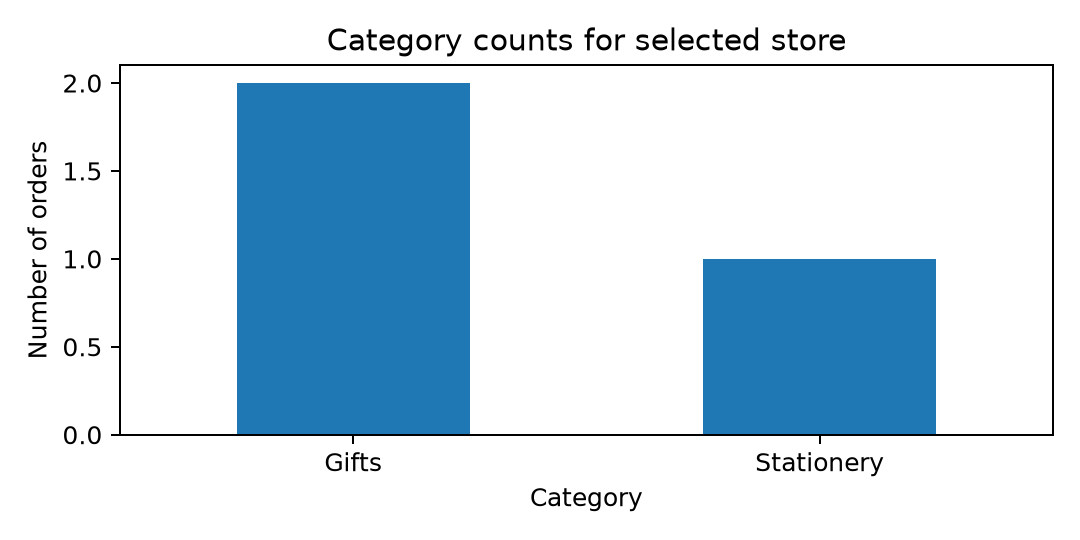
Select → summarize → plot in one line. Here, count categories for Central only. kind="bar" chooses a bar chart; .plot.bar() is a shorthand for .plot(kind="bar").
Read left to right: select Central’s Category Series → count each category → draw the counts. Result: Gifts = 2 orders; Stationery = 1. Change "Central" to "Kowloon"in the .loc condition and run again.
Bar Chart: Compare Category Totals
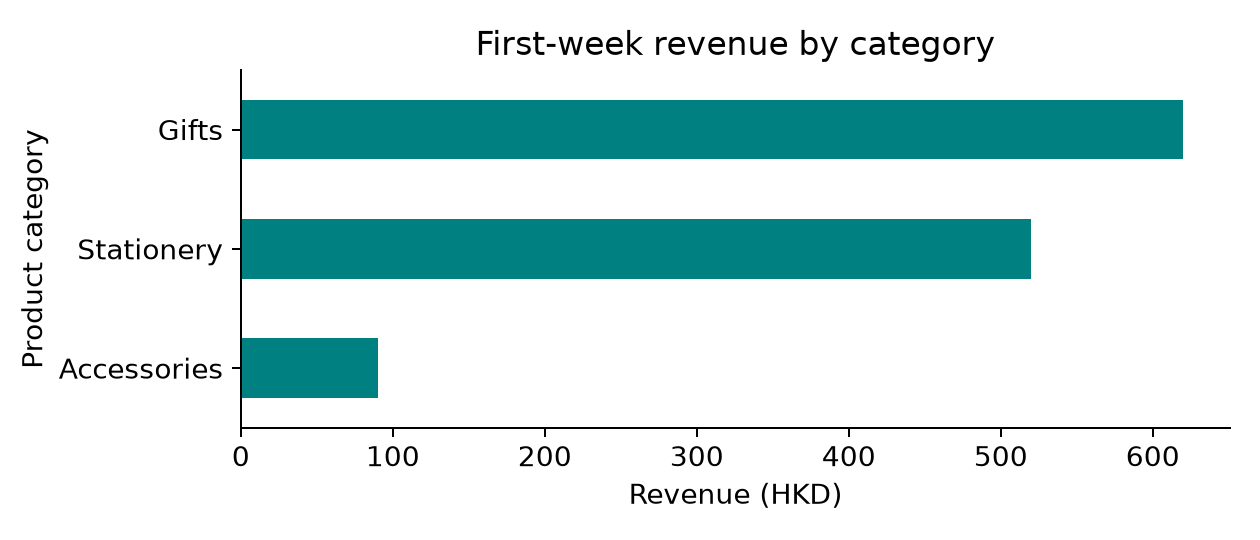
Calculate the totals first, then plot them. A bar chart compares distinct categories. Here, .plot.barh(...) draws horizontal bars and returns the chart’s Axes object, which we save as ax. It is the plotting area that contains the bars, title, and axes.
Horizontal or vertical? The h in barh means horizontal. Both charts compare the same category totals; only their orientation changes.
Pandas method
Direction of bars
Category axis
Revenue axis
.plot.barh()
Horizontal: bar length shows revenue
y
x (HKD)
.plot.bar()
Vertical: bar height shows revenue
x
y (HKD)
.plot(kind="barh") and .plot(kind="bar") are equivalent ways to choose these chart types. Horizontal bars often leave more room for long category names.
Code
What it does in this example
ax.set(title=..., xlabel=..., ylabel=...)
A method of ax: sets the chart title and both axis labels together. Here, x shows Revenue (HKD); y shows Product category.
plt.tight_layout()
Adjusts spacing around the plot to help keep the title and labels from overlapping or being cut off. It does not change the data.
plt.show()
Displays the completed figure in the Python output. Call it after creating and formatting the chart.
Order: create the chart and save ax → set title and labels → adjust spacing → display.
Try it: change horizontal = True to horizontal = False and run again. The bars become vertical and the axis labels swap. The totals stay the same: Accessories = 90, Stationery = 520, Gifts = 620 HKD.
Histogram: Show the Order Distribution
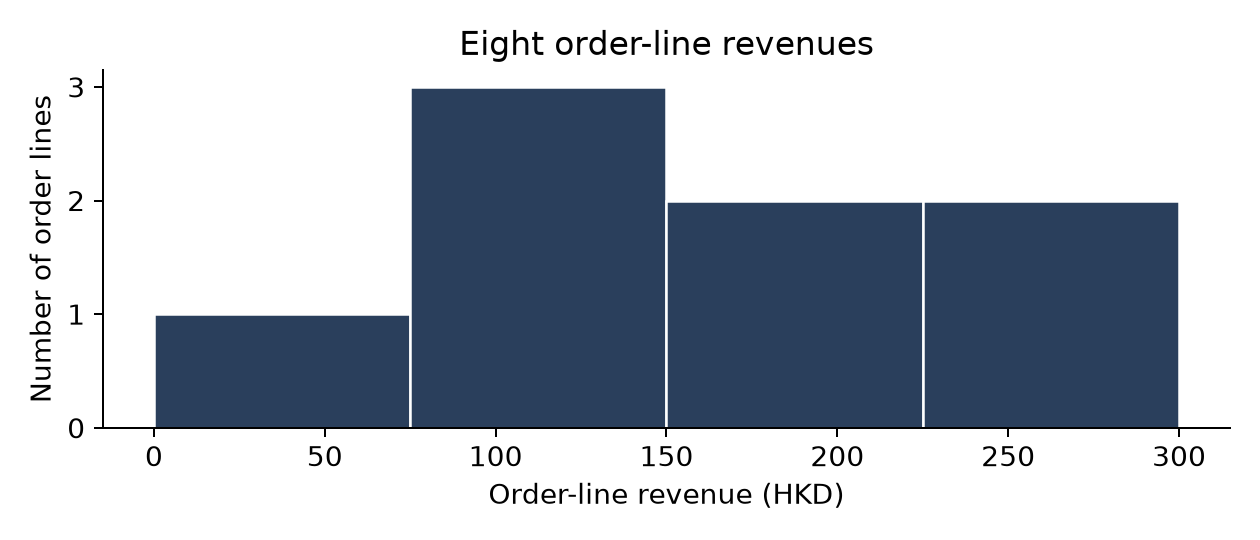
A histogram groups numerical values into intervals. Change bins and see how the appearance changes. With only eight observations, avoid strong claims about distribution shape.
Box Plot: Compare Store Distributions
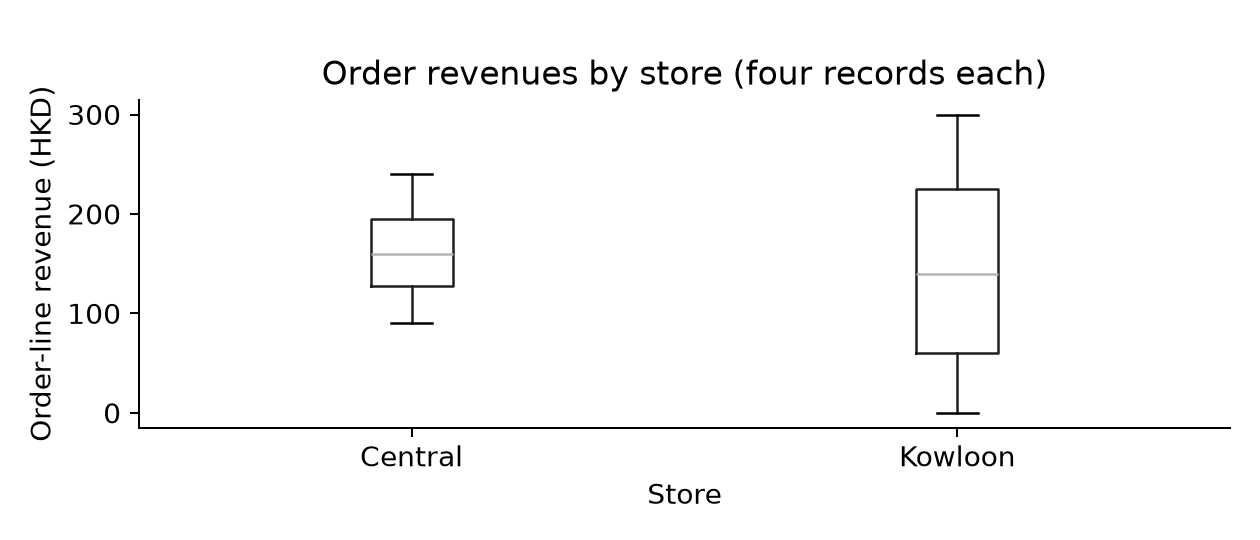
A box plot summarises a distribution with its median and quartiles. With small groups, inspect the original points as well. An unusual observation can be legitimate.
Four Chart Types at a Glance
Compare a line chart, histogram, bar chart, and box plot. Choose by the question: time order, numerical distribution, category comparison, or distribution summary.
A Conclusion Supported by the Table
In our eight classroom records, Gifts contributes HK$620 in revenue. This does not establish that its products are most profitable, that coupons caused larger orders, or that a particular budget transfer is optimal.
Work with ChatGPT: Check the Result
Ask ChatGPT to explain the code and its assumptions. Then run it, inspect row counts, and verify key numbers yourself. A fluent recommendation still needs evidence.
Useful prompt: “Explain which rows this code removes, how the denominator changes, and which business claims the output can support.”
In-Class Practice: Total or Average?
Use .loc to select Gifts revenue, then Accessories revenue. Print each count, sum, and mean separately. Put the two totals into a Series and draw a bar chart.
Expected: Gifts has 3 orders, total 300, mean 100. Accessories has 1 order, total 200, mean 200.
§7 — Dates, Lags, and Changes over Time
Convert and organise dates, combine selected orders into daily totals, and distinguish previous values, next values, and changes.
A Date String and a Datetime Value
"2026-11-01" begins as text. pd.to_datetime() converts it to a datetime value. Convert dates before relying on date-specific operations.
Set and Sort a Date Index
.set_index("Date") moves Date into the index. .sort_index() places records in chronological order. Neither step makes missing dates appear automatically.
Select Dates with loc
A sorted DatetimeIndex supports readable date ranges. Both endpoints are included. A partial date such as a month selects matching records.
Date Components: Column versus Index
For a datetime Series, use .dt.month or .dt.day_name(). For a DatetimeIndex, use .month or .day_name() directly. .dayofweek counts Monday as 0.
Orders Become a Daily Sales Table
Two order lines on November 2 have revenues of HK$80 and HK$140. Use .loc to select that date and .sum() to calculate its daily total: HK$220. One order line and one day are different observation units.
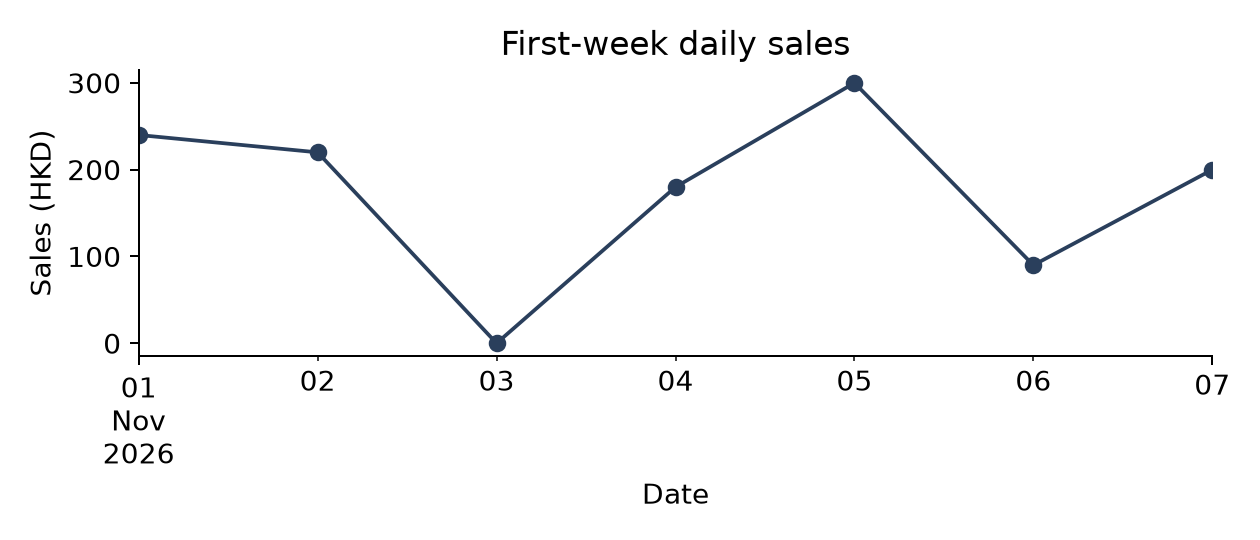
Line Chart: Follow Time Order
Plot daily sales in chronological order. A line chart shows changes between consecutive dated observations; it does not establish a forecast.
shift Moves Values Relative to Their Rows
.shift(1) moves values down one row, placing the previous observation beside the current one. The index stays unchanged. The first row shows NaN because it has no previous observation.
shift(-1): Bring the Next Observation to the Current Row
.shift(-1) moves values up one row. Each row receives the next observation; the index stays unchanged. The last row shows NaN because there is no next observation.
Method
Direction
Value beside the current row
Missing boundary
.shift(1)
Down one row
Previous observation
First row
.shift(-1)
Up one row
Next observation
Last row
Absolute Change and Relative Change
Absolute change is current − previous. Relative change divides by the previous value. .pct_change() returns a fraction: 0.10 means 10%. Missing observations and zero denominators need attention.
Growth after Zero Sales
A move from HK$0 to HK$180 has an absolute increase of HK$180. It does not have a finite percentage increase. Retain only positive previous sales for this growth-rate denominator.
In-Class Practice: Yesterday and Today
Build a table with Sales, Previous, absolute change, and relative change for 100, 120, and 90 HKD. Show relative change as a percentage in a separate column.
Expected later changes: +20 HKD and +20%; −30 HKD and −25%. The initial changes are missing.
§8 — Rolling and Cumulative Methods
Explain what a moving window includes and distinguish recent-period statistics from running totals and compounded growth.
A Three-Observation Moving Average
For sales 100, 200, 300, 400, 500, the first complete three-value window is [100, 200, 300], with mean 200. The next window drops 100 and adds 400.
Interactive Window: Which Values Are Included?
Change the window size and ending observation. Highlighted values contribute to the mean. Reproduce the selected calculation in the Python box.
Position
0
1
2
3
4
Sales (HKD)
100
200
300
400
500
Window [100, 200, 300]: mean = 200.00 HKD
Chart: Sales and a Moving Average
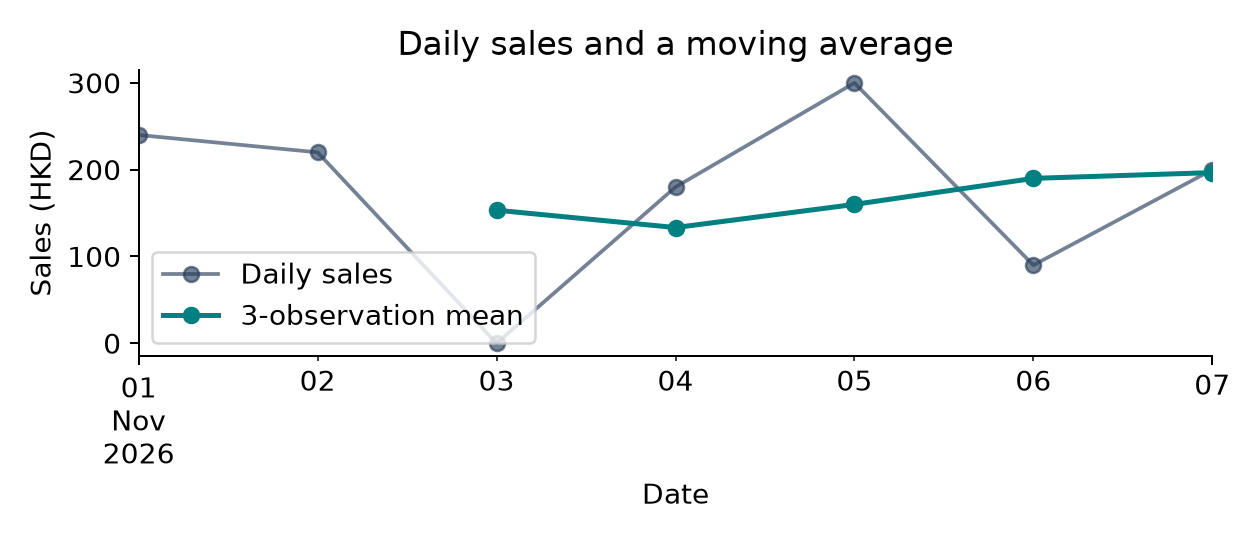
A rolling mean smooths short-term variation. Change the window from 3 to 2 or 4, then compare the curve and the number of initial missing values.
Create the dates first:pd.date_range(start="2026-11-01", periods=7, freq="D") creates a DatetimeIndex containing seven consecutive calendar dates, November 1 through November 7.
Argument
Meaning in this example
start="2026-11-01"
The first date is November 1, 2026.
periods=7
Create seven dates, including the first date.
freq="D"
Move forward one calendar day each time; D means daily.
Save these dates as dates. Using index=dates pairs each sales value with its date. This function creates dates; it does not create sales values or fill missing sales.
Rolling Sums and Standard Deviations
A rolling sum measures recent total sales. A rolling standard deviation describes recent variation. Both need a defined window and units.
Incomplete Windows and min_periods
min_periods=1 allows an early mean using the available values. That first output is a one-observation mean, even though the maximum window size is 3.
Three Observations versus Three Calendar Days
On irregular dates, .rolling(3) and .rolling("3D") use different windows. The default right-closed time window excludes an observation exactly at its left boundary.
Cumulative Sales: Keep Adding from the Start
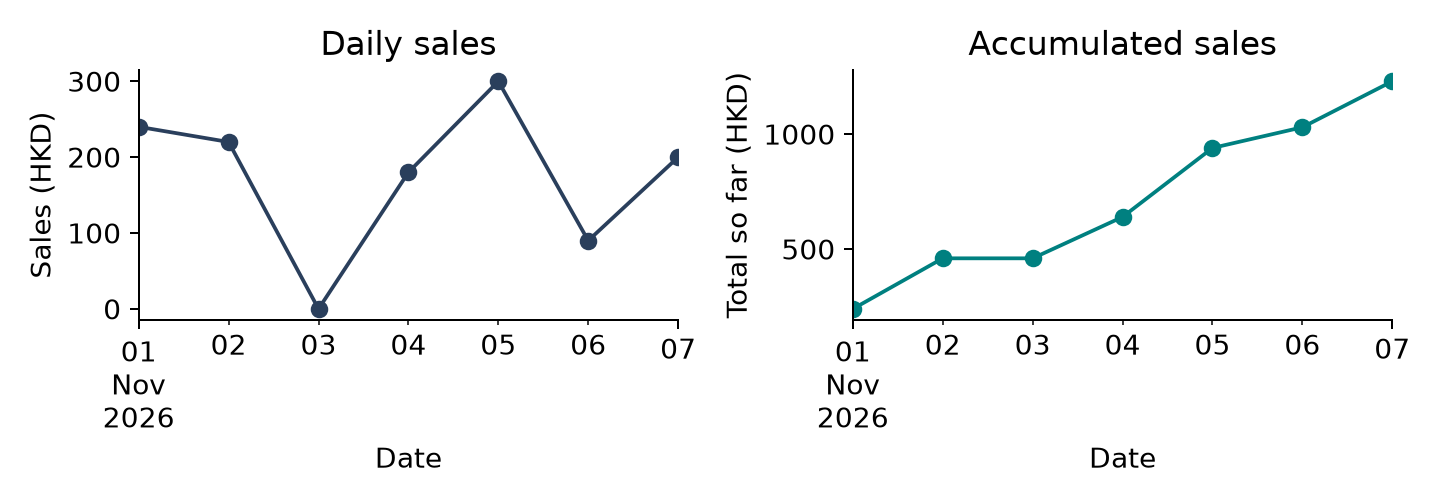
.cumsum() retains all observations from the beginning through the current row. It answers “How much so far?” rather than “How much in the recent window?”
Chart: Daily and Accumulated Sales
Compare sales on each day with sales accumulated so far using two separate charts. Use the familiar Series methods .plot.bar() and .plot(), with plt.title(), plt.xlabel(), and plt.ylabel() to label each chart.
Cumulative Maximum and Minimum
Cumulative means using every observation from the first row through the current row.
.cummax() gives the cumulative maximum: the highest value observed so far.
.cummin() gives the cumulative minimum: the lowest value observed so far.
A cumulative maximum can stay unchanged when the current sales value falls; a cumulative minimum can stay unchanged when the current sales value rises.
.cumprod() means cumulative product: multiply all values from the first row through the current row. It returns one product for each row.
For [2, 3, 4], the cumulative products are [2, 2 × 3, 2 × 3 × 4] = [2, 6, 24].
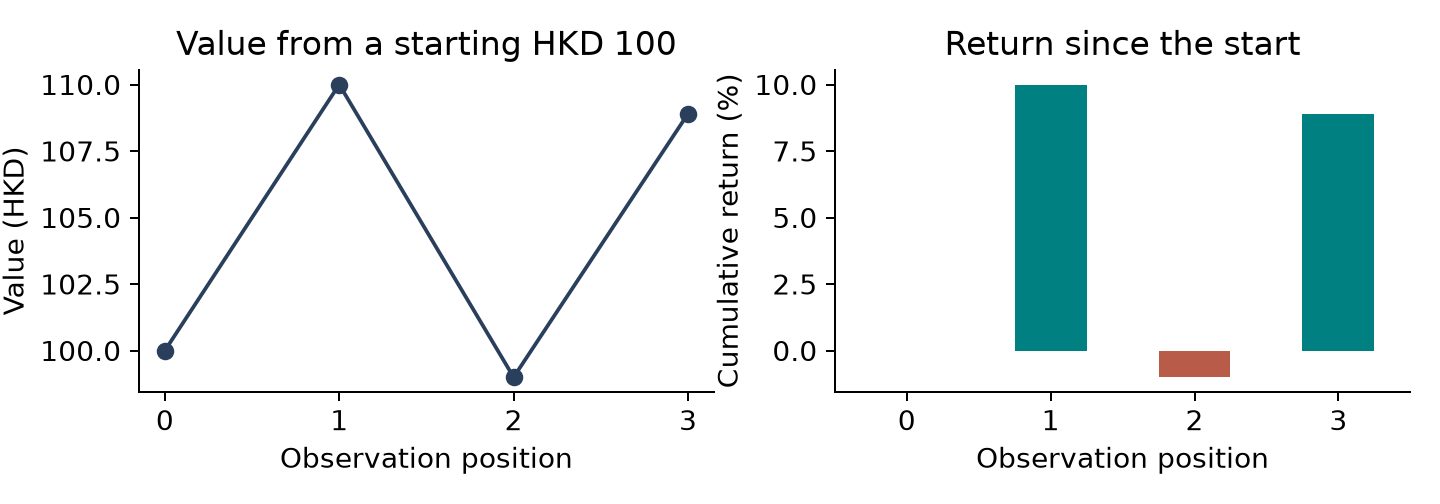
For returns, first calculate each growth factor as 1 + return. Then use .cumprod() to multiply the factors. Subtract 1 from the product to obtain the cumulative return.
Row
Return
Growth factor
Cumulative product
Cumulative return
0
+10%
1.10
1.10
1.10 − 1 = +10%
1
−10%
0.90
1.10 × 0.90 = 0.99
0.99 − 1 = −1%
2
+10%
1.10
1.10 × 0.90 × 1.10 = 1.089
1.089 − 1 = +8.9%
Multiply the growth factors; do not add the returns.
From Prices to Cumulative Returns
The first price has no return from a previous observation. Set the known starting value to 100 for this complete-price example, then compound subsequent growth factors.
Financial Example: S&P 500 Data
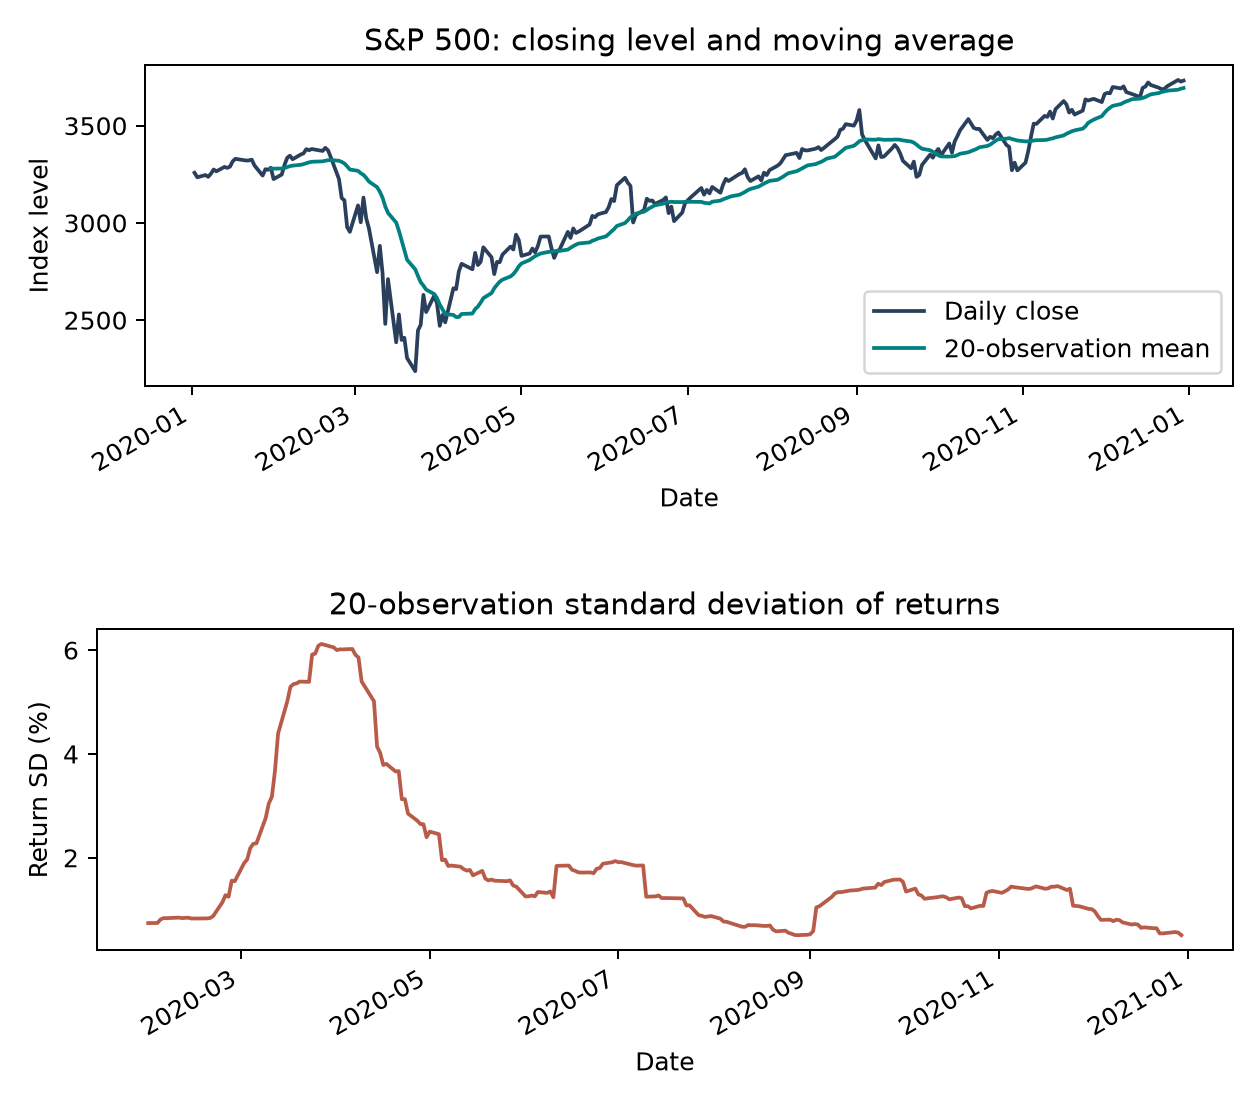
Load the course’s 2020 S&P 500 snapshot. Select dates, calculate fractional returns, and compare a price moving average with a returns standard deviation.
Financial Chart: Prices and Return Variation
Read two separate charts made with the familiar .plot() method:
Closing level and moving average: the blue line shows the S&P 500 closing level on each date. The teal line shows the mean of the most recent 20 observations. The vertical axis measures index level.
Variation in daily returns: the red line shows the standard deviation of the most recent 20 returns. Multiplying by 100 displays it as a percentage. A higher value means the recent daily percentage changes varied more.
Change window = 20 to window = 10, then run again and compare both charts.
Extension: A Running Peak and Drawdown
Drawdown compares the current price with its highest value so far: price / running peak − 1. It is zero at a peak and negative below that peak.
Rolling and Cumulative Answer Different Questions
Compare the last three observations with all observations so far. Select a rolling sum for recent sales; select a cumulative sum for progress since the beginning.
In-Class Practice: Recent Sales and Total Sales
Compute the three-observation rolling mean and cumulative sales. Print the final values and explain why they answer different questions.
Expected final rolling mean: 400 HKD per observation. Expected cumulative total: 1500 HKD.
Chapter Summary
Business task
Main tools
Inspect a table
.shape, .dtypes, .head(), .info()
Select records
[], .loc[], .iloc[], Boolean masks
Handle missing entries
.isna(), .notna(), .dropna(), .fillna()
Create measures
column arithmetic, .copy(), .loc assignment
Rank and combine steps
.sort_values(), axis, ascending=False, short method chains
Check yourself: Can you explain the code, predict its output, and support a business conclusion with the actual numbers? Next: Chapter 3, Predicting with Linear Regression.