Use Python tools to select business data, calculate summaries, draw charts, and interpret probabilities. The lecture emphasis is reading code and explaining results.
Chapter Roadmap
Section
What you will learn
1. Lists
Select, transform, and filter values
2. Modules and Imports
Packages, installation, aliases, import forms
3. NumPy Arrays
Calculate with many numbers at once
4. Pandas Series
Label and summarize business data
5. Matplotlib
Create and explain charts
6. SciPy Probability
Normal CDF and PPF
§1 — Lists and Comprehensions
Select values, transform prices, filter records, and pair matching observations.
Lists: An Ordered Collection
A list stores several values under one name. Items keep their order. Square brackets create the list; commas separate items.
Indexing and Slicing
Indexing selects one item. Python starts at position 0; -1 selects the last item. A slice includes its start and excludes its stop.
Predict the slice first. Change it to dishes[:2] and explain the result.
List Methods: A Short Recap
A list is an object. A method is a function belonging to an object: write object.method(...). The dot looks up the method, and () calls it. append("Milk Tea") adds one item; count("Milk Tea") counts matching items; pop() removes and returns the last item when called without an argument.
Compare dishes.count("Milk Tea") with len(dishes): the first calls a list method to count one value; the second calls a built-in function to count all items.
A Loop Builds a New List
Every dish price rises by HK$2. Start with an empty list, visit each old price, and append the new price.
The original prices list is unchanged.
A Comprehension Transforms Values
A list comprehension builds a new list in one expression. Read [price + 2 for price in prices] as “for each price, calculate price + 2.”
A Comprehension Filters Values
An ifafter the for part keeps only matching items. The result may be shorter than the original list.
Change the cutoff from 50 to 40. Which items enter the result?
A Comprehension Assigns a Label
An if ... elsebefore the for part produces a value for every item. Each price receives a label; no item is removed.
zip: Pair Corresponding Items
zip pairs items in the same positions. for count, bill in ... gives names to the two values in each pair. Inputs should describe matching dishes.
In-Class Practice: Filter or Label?
Print (1) prices at least HK$50 and (2) one Premium/Regular label per price. Explain why the result lengths differ.
Checkpoint: two prices pass the filter; all four receive labels.
§2 — Modules and Imports
Explain installation versus import and recognize the common import forms.
What Is a Module?
A module is reusable Python code containing functions, variables, or other definitions. Often it is a .py file. import makes its names available in your running session.
Module, Package, and Library
Word
Meaning
Example
Module
Reusable unit of Python code
math, matplotlib.pyplot
Package
Organizes modules under a shared name
numpy, scipy, isom2600
Library
General name for a collection of tools
The NumPy library
Install versus Import
Install: add a package to a Python environment. Import: make its code accessible in the current running session. Installation does not automatically create the names used in your code.
math comes with Python. Colab commonly supplies NumPy and SciPy. These websites supply their required browser packages.
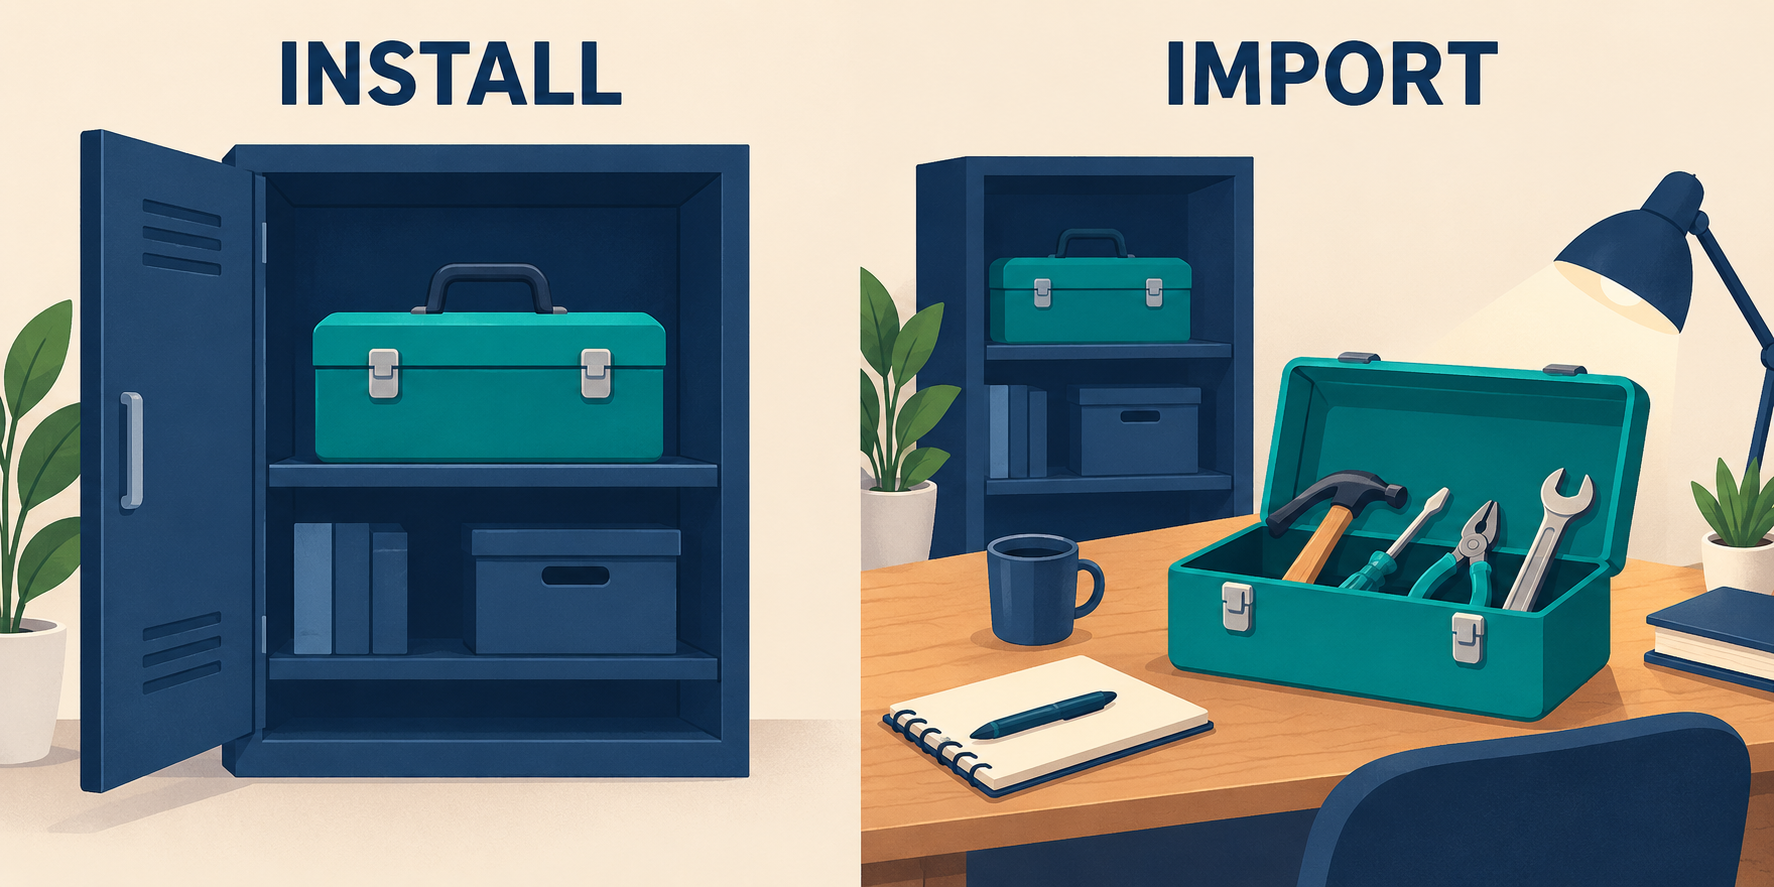
Install and Import: A Toolbox Metaphor
Install: place a toolbox in the environment. Import: make its tools accessible in your current session. The package remains installed when a session ends.
Illustrated metaphor. Installation provides code; import makes its names available in the running session.
pip Commands: Where They Run
pip is Python’s package installer. These commands run in different environments; read them here as instructions, not code for a website Python box.
Terminal:
python-m pip install isom2600
Colab cell:
!pip install isom2600 --quiet
! runs a shell command through the notebook. --quiet reduces messages. %pip install isom2600 is a notebook alternative targeting the current kernel.
What Does pip install isom2600 Mean?
isom2600 is this course’s helper package. Installation downloads its Python code. It does not install Python or enroll you in the course.
Colab reference for later work:
import isom2600# data = isom2600.data.profit()
It supplies isom2600.data and isom2600.regression helpers. The websites use small supplied data directly; no installation is needed here.
Import Form 1: The Module Name
import math introduces math. math.sqrt(...) identifies the module that provides the function.
A bare sqrt(64) is not defined by this import alone.
Import Form 2: An Alias
as gives a module a shorter local name. Its tools stay the same; the name you type changes.
Import Form 3: A Selected Function
from math import sqrt introduces sqrt directly. Call it without the math. prefix.
Import Form 4: A Function Alias
A selected function can also have an alias. Here, root refers to the square-root function.
The result is still 8.0. Use the chosen name consistently.
Import Form 5: A Submodule
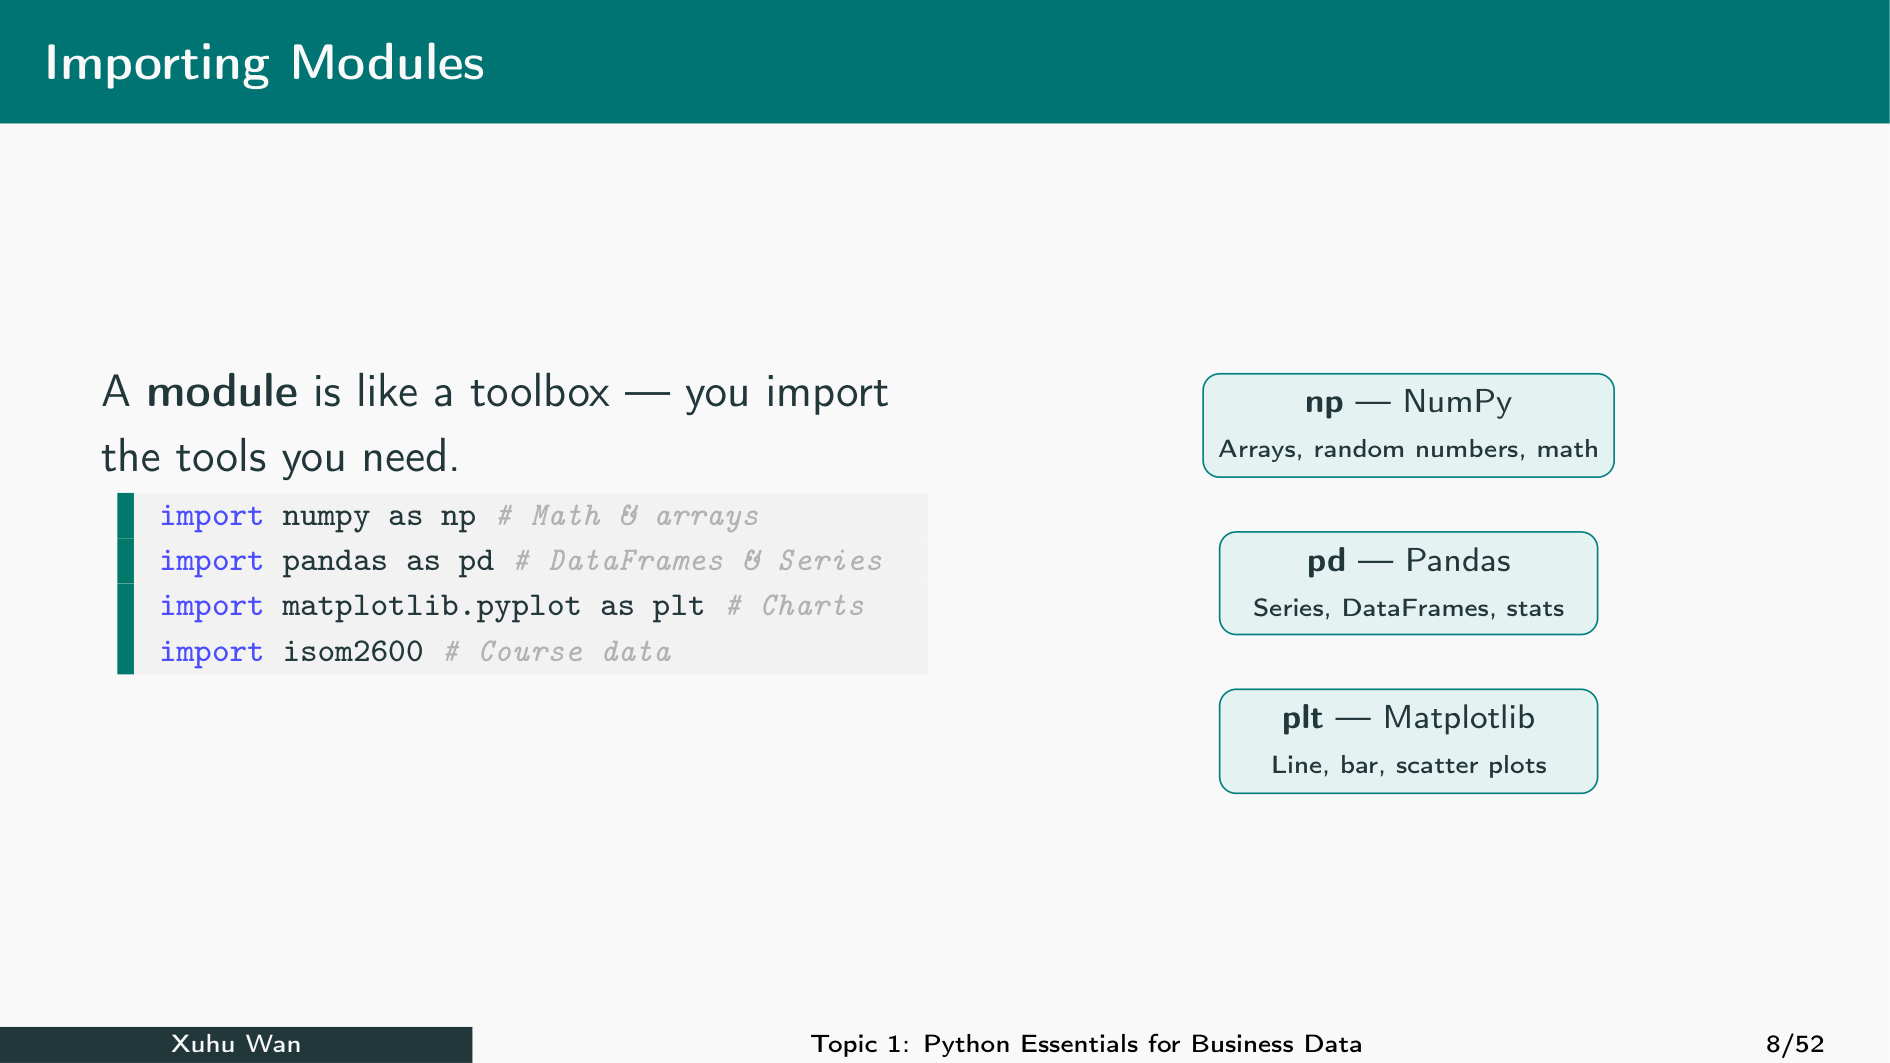
A dotted import selects part of a package. matplotlib.pyplot contains chart functions; from scipy import stats selects statistics tools.
Common Aliases in This Course
These names become available only after their corresponding imports run.
import numpy as np · import pandas as pd · import matplotlib.pyplot as plt · from scipy import stats
Wildcard Imports and Common Errors
from math import * is another form. It brings many public names into the session. Prefer explicit imports so the source of each name is clear.
Error
Check
ModuleNotFoundError
Package spelling and current environment
NameError: np is not defined
Whether import numpy as np ran
AttributeError
Function spelling; overwritten module name
In-Class Practice: Match the Import
Calculate sqrt(144) in two ways: through math.sqrt and through a directly imported function. Print both results.
Checkpoint: both forms print 12.0. Explain why the calling styles differ.
§3 — NumPy Arrays
Use arrays for calculations, masks, numerical summaries, and a reproducible simulation.
Create a NumPy Array
NumPy provides arrays for numerical calculations. np.array(...) converts a list into an array. Import NumPy before using np.
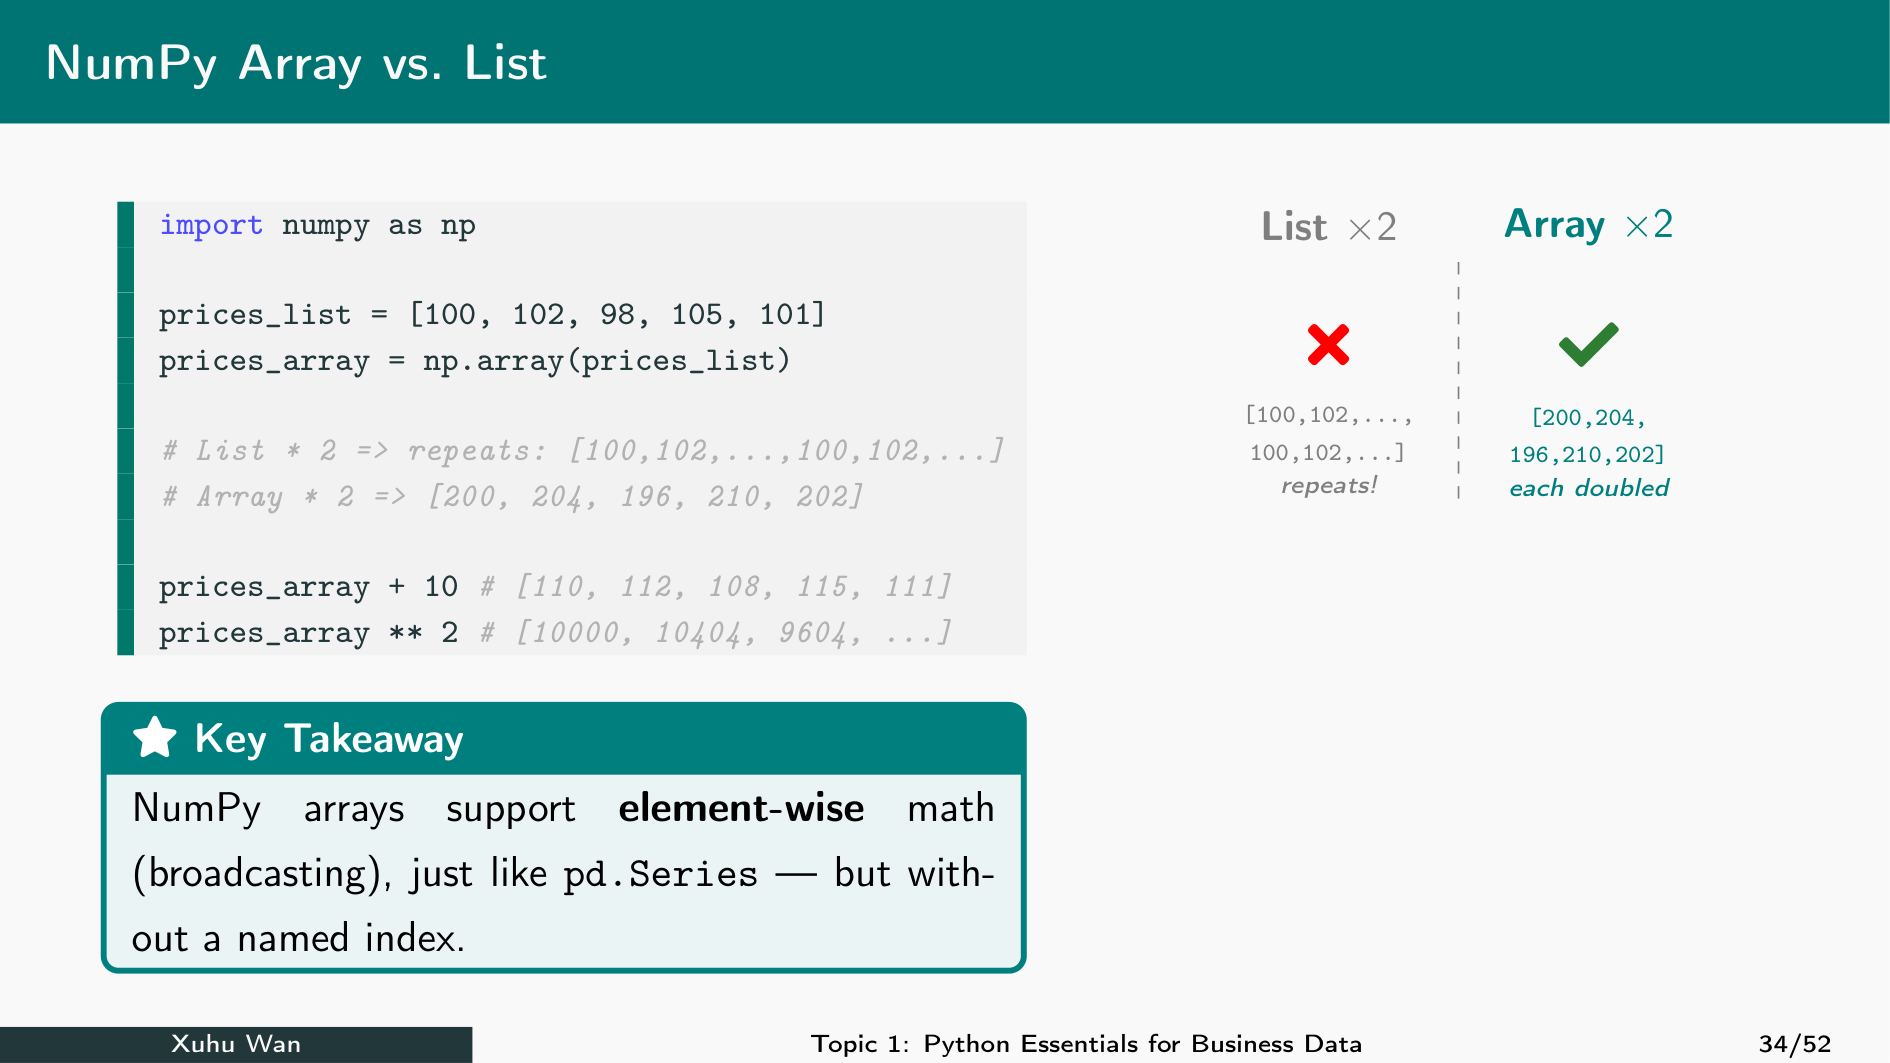
List Multiplication versus Array Multiplication
A list multiplied by 2 repeats its items. An array multiplied by 2 doubles each numerical value.
Array Multiplication: The Picture
The list repeats the sequence; the array produces one doubled value per original item. Repetition is valid list behavior, but does not calculate doubled prices.
Array Attributes and Methods
An array is an object: it stores values and provides information and tools. The dot in prices.member accesses something belonging to prices.
Kind
Meaning
Example
Attribute
Information about the object; read without ()
prices.dtype
Method
A function belonging to the object; call with ()
prices.sum()
Predict, then try: which expressions use ()? Change prices.sum() to prices.mean() and run again. The method now calculates the average price.
Calculate Revenue Element by Element
For equally shaped arrays, corresponding positions are combined. Customer count × average bill gives one dish’s daily revenue.
Units: customers/day × HK\(/customer = HK\)/day. This matches the list-and-zip result.
A Scalar Applies to Every Element
A scalar is one value. Applying it to every array item is a simple form of broadcasting. Use it for price adjustments and percentage changes.
Conditions Create a Boolean Mask
A comparison returns one True/False result per item. Use the mask to select matching values. Its mean is the fraction of True values.
Two of four prices pass: 0.5, or 50%.
Array Summary Statistics
Use sum, mean, median, min, and max to summarize observations. Interpret the units: a mean is not a guarantee about every observation.
customers.mean() is an array method. np.median(customers) calls a function from NumPy with the array as its argument. A Pandas Series also provides a .median() method.
Standard Deviation: Choose the Denominator
Standard deviation measures spread in the original units. NumPy defaults to ddof=0: variance divides by n. The usual sample standard deviation uses ddof=1: variance divides by n−1.
Outputs: 2.315 and 2.588 customers. Match the convention to the question; pandas defaults to ddof=1.
Random Numbers: A Reproducible Simulation
A simulation creates artificial data. np.random.normal draws numbers from a normal model: loc=28 sets the mean to 28 minutes, scale=6 sets the standard deviation to 6 minutes, and size=5 asks for five numbers.
These are simulated delivery times, not observations. The optional np.random.seed(42) line makes the example repeatable; 42 is an arbitrary seed. Change size=5 to size=10 and run again to generate ten values. Section 6 explains the normal model.
In-Class Practice: A Price Increase
Increase prices by 10%. Print updated prices and select only those above HK$50.
Checkpoint: only the updated Char Siu price is above HK$50.
§4 — Pandas Series
Identify values with labels and interpret summaries, rankings, and aligned calculations.
Create a Labelled Series
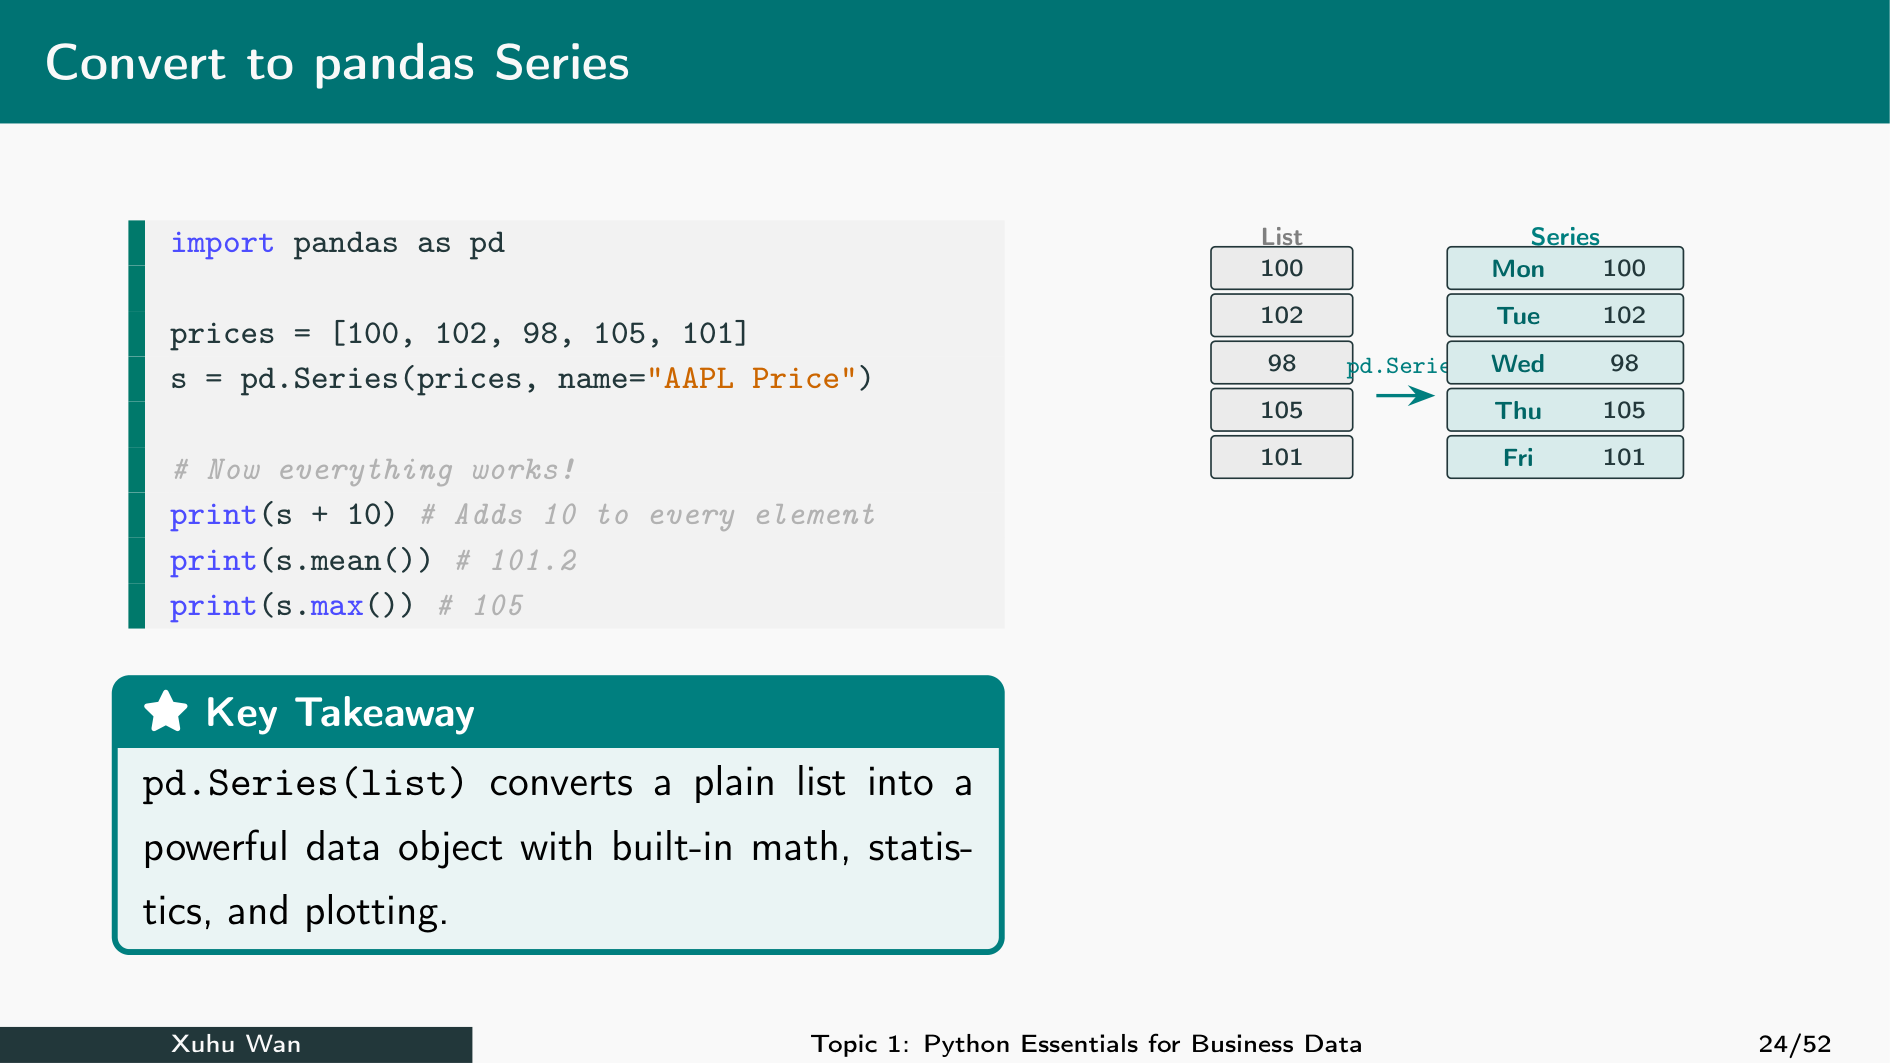
A pandas Series pairs values with an index of labels. These dish names identify which revenue belongs to which dish.
Series Labels: The Picture
The right column attaches weekday labels to the same five values. A Series can have a default numerical index or labels that you supply explicitly.
Select by Label or Position
.loc selects by an index label, such as a dish name. .iloc means integer-location selection: it selects by numerical position. Positions start at 0: the first item is at 0, the second at 1, and the third at 2.
Remember:.iloc[1] selects the second item, not the first. Here .loc["Char Siu"] and .iloc[1] select the same value using a label and a position respectively.
Series Attributes and Methods
A Pandas Series is also an object with attributes and methods. Attributes describe it:index gives labels, name gives its name, shape gives dimensions, and dtype gives the stored value type. Read them without (). Methods do something:mean() calculates an average; median() finds the middle sorted value; head(2) returns the first two items. Call methods with (); put any arguments inside.
Try: change head(2) to head(1) and run again. For selection, .loc[...] and .iloc[...] use square brackets rather than the method-call parentheses used by .mean().
Mean, Median, and Spread
A mean summarizes average level; a median is the middle sorted value. Standard deviation measures spread, so two series with the same mean can behave differently.
describe: A Summary in One Call
describe() reports count, mean, sample standard deviation, minimum, quartiles, and maximum for numerical data. The 50% row is the median.
Pandas and NumPy: Match ddof
Pandas defaults to ddof=1; NumPy defaults to ddof=0. Use matching choices when comparing answers.
Outputs: 2.588, 2.588, 2.315. Neither default is automatically appropriate for every business question.
Filter and Rank a Series
A Boolean condition selects labelled values. sort_values orders values; idxmax identifies the label of a maximum value.
Count Categories
value_counts() counts how often each category occurs. Use it for survey responses, product categories, and order types.
Tea appears three times and Coffee twice. Counts differ from averages of numerical measurements.
Series Arithmetic Aligns Labels
Pandas matches index labels in Series arithmetic, even when their order differs. Check labels before combining records.
In-Class Practice: Explain a Revenue Summary
Create a labelled Series, print its mean and largest-revenue dish, then explain why revenue alone cannot determine profitability.
Checkpoint: Char Siu has the largest daily revenue, but costs are missing.
§5 — Matplotlib
Choose a chart, label it clearly, and explain what its evidence supports.
Choose a Chart for the Question
Question
Chart
How does revenue change over time?
Line
Which dish has more revenue?
Bar
How are delivery times distributed?
Histogram
Do two numerical variables move together?
Scatter
Matplotlib: A Figure and Its Labels
plt is the alias for matplotlib.pyplot. A figure is the picture area. plot adds a line; show displays it. Labels explain what the picture measures.
Line Chart: Follow Time Order
Plot days on the horizontal axis and daily revenue on the vertical axis. A connecting line helps follow chronological changes.
Friday is the largest observation. Five days do not establish a long-term trend.
Bar Chart: Compare Categories
Use separate bars for dish categories. Compare heights on the same numerical scale. Revenue does not include costs.
Histogram: Show a Distribution
A histogram groups numerical observations into intervals called bins. Bar heights count observations within each interval. It shows spread and concentration.
Scatter Plot: Compare Two Variables
Each dot represents one observation. Use a scatter plot to inspect association between two numerical variables. An association alone does not prove cause and effect.
A Series Can Use Matplotlib
A Series plotting method uses its index labels. kind="bar" requests bars. You can then use plt to label and display the figure.
The explicit plt.bar and Series method answer the same category-comparison question.
In-Class Practice: Repair a Chart
Draw a bar chart comparing the three dishes. Add a meaningful title and axis labels including revenue units. Explain why a line joining dish names would be less suitable.
Checkpoint: three bars; a labelled vertical axis in HK$/day.
§6 — SciPy Probability
Distinguish CDF and PPF, calculate probabilities and cutoffs, and state model assumptions.
SciPy: A Normal Probability Model
scipy.stats supplies probability distributions. A normal distribution is a bell-shaped model described by a mean and standard deviation. Its use is an assumption about the data.
CDF: A Value Gives a Probability
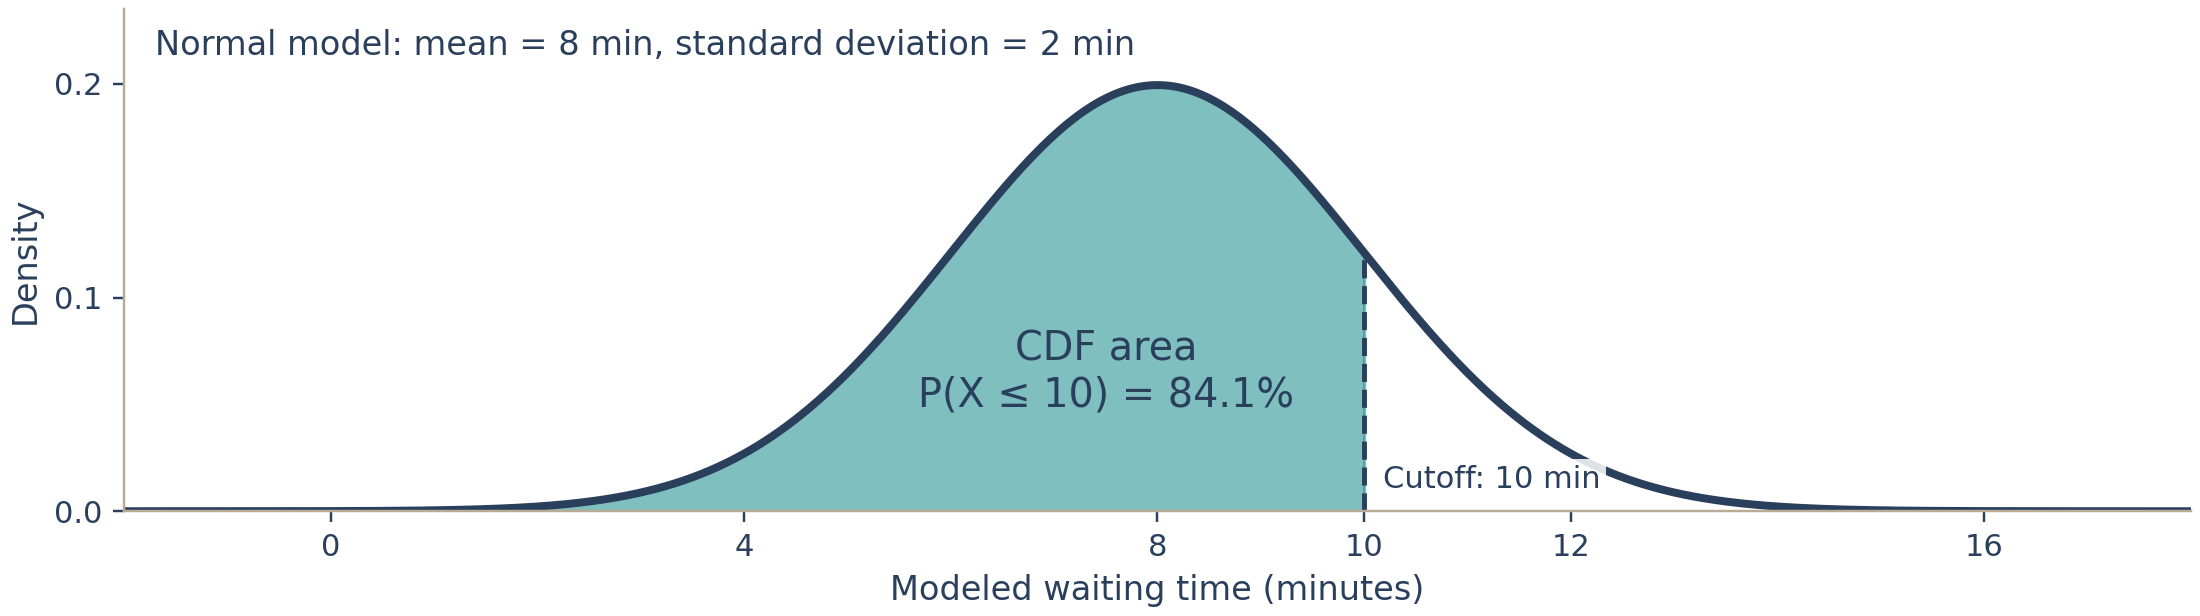
CDF means cumulative distribution function: P(X ≤ x). For the normal model with mean 8 and standard deviation 2, what fraction of waiting times is at most 10 minutes?
About 84.1% lie at or below 10 minutes under this model. For a continuous normal distribution, < and ≤ give the same probability.
Upper Tail: Exceeding a Limit
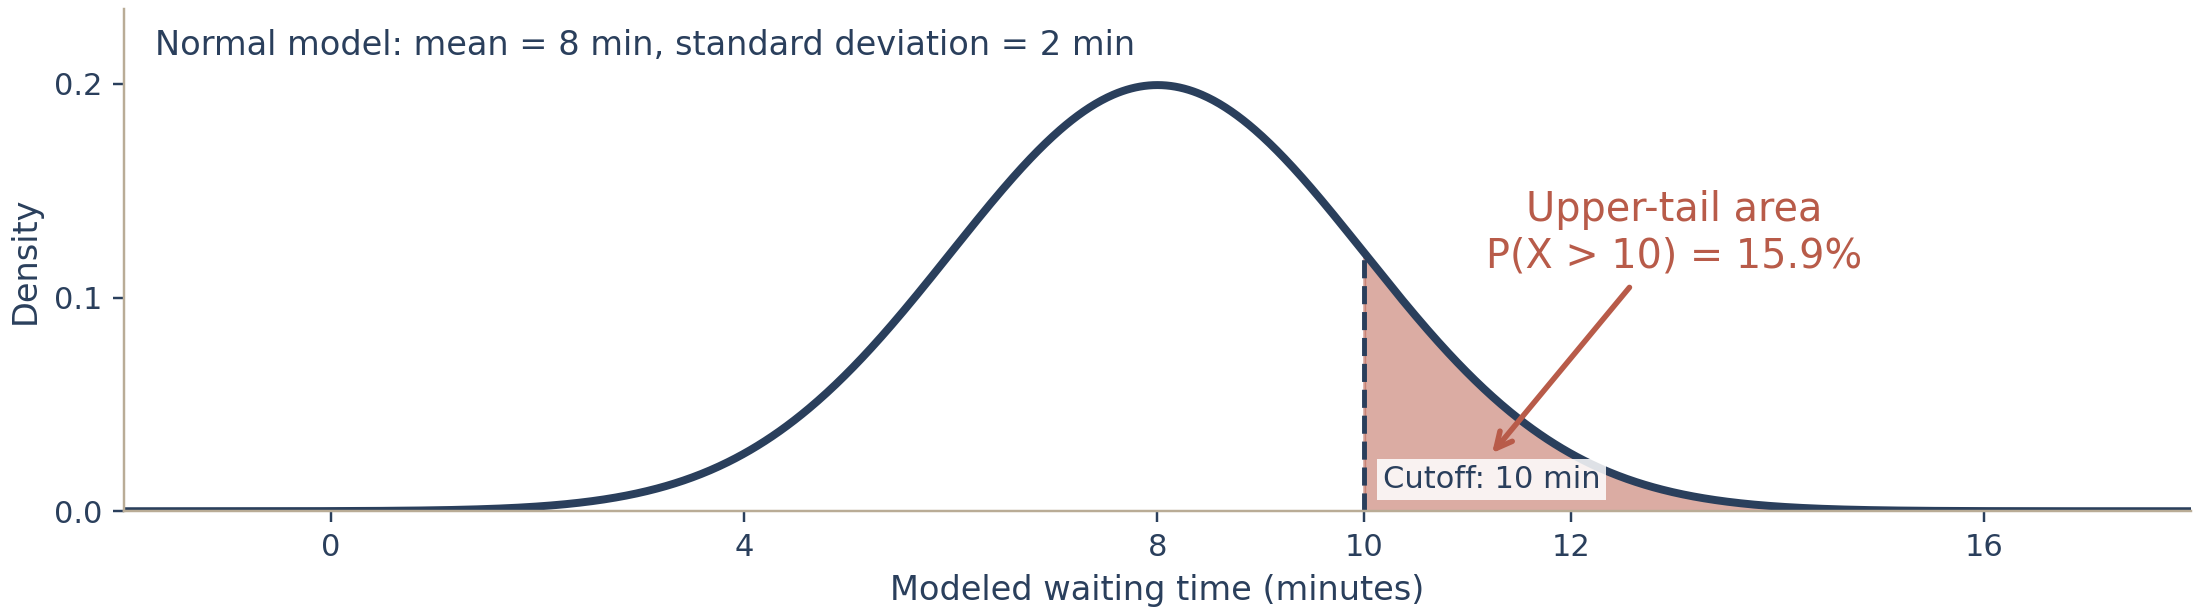
For the same normal model (mean 8, standard deviation 2), shade the area to the right of 10 minutes: P(X > 10). The total area is 1, so subtract the CDF’s left-hand area from 1.
The shaded upper tail is about 15.9%. The two areas sum to 100%: 84.1% + 15.9%.
Probability Between Two Values
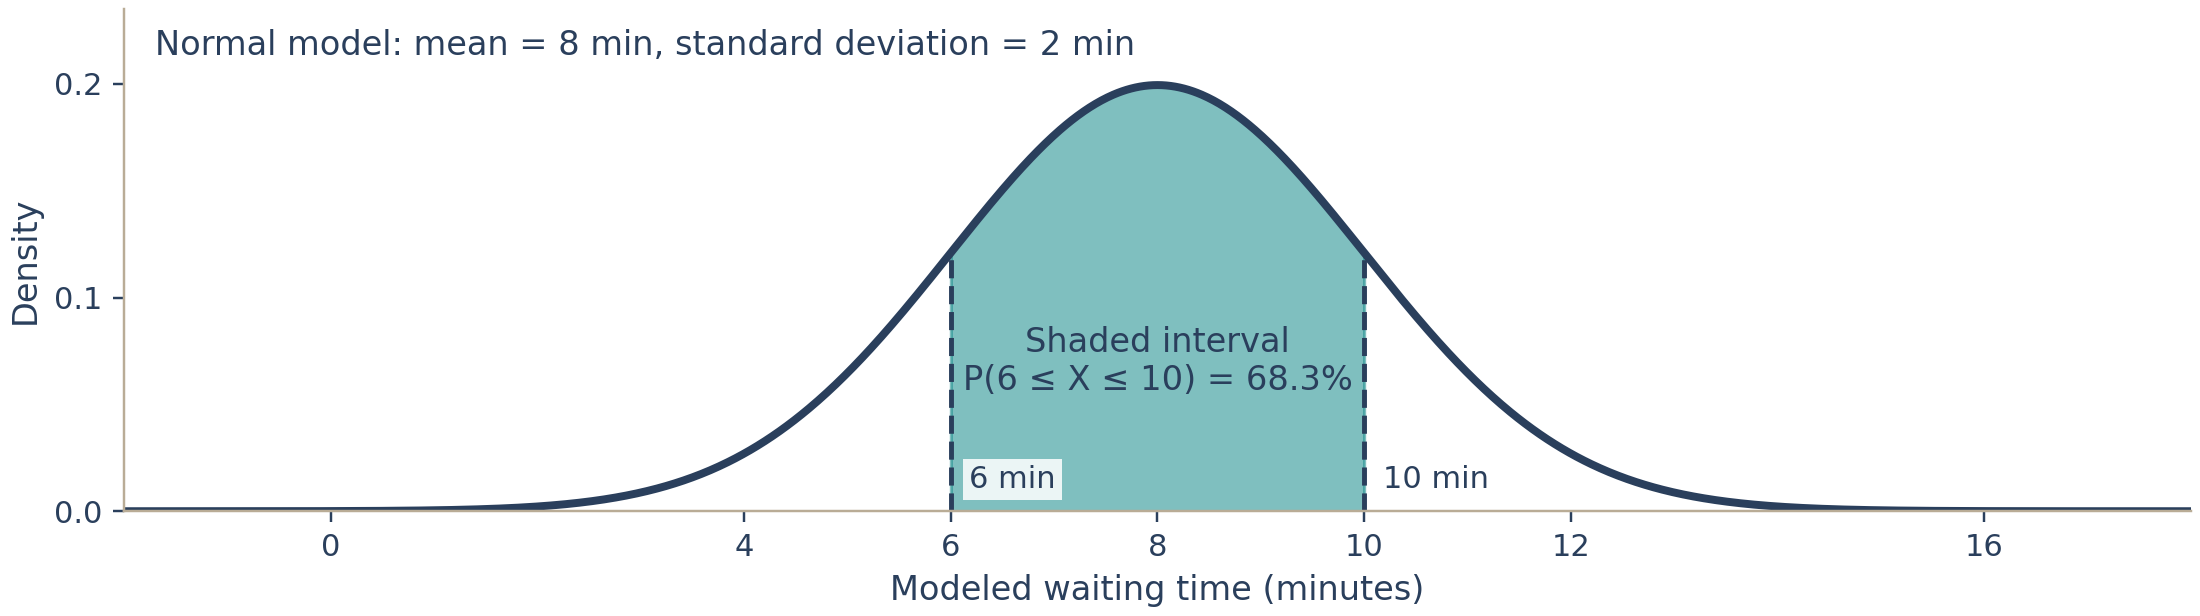
To find the probability between 6 and 10 minutes, subtract the cumulative probability up to 6 from the cumulative probability up to 10.
The probability is about 68.3%, matching the normal interval within one standard deviation of its mean.
PPF: A Probability Gives a Value
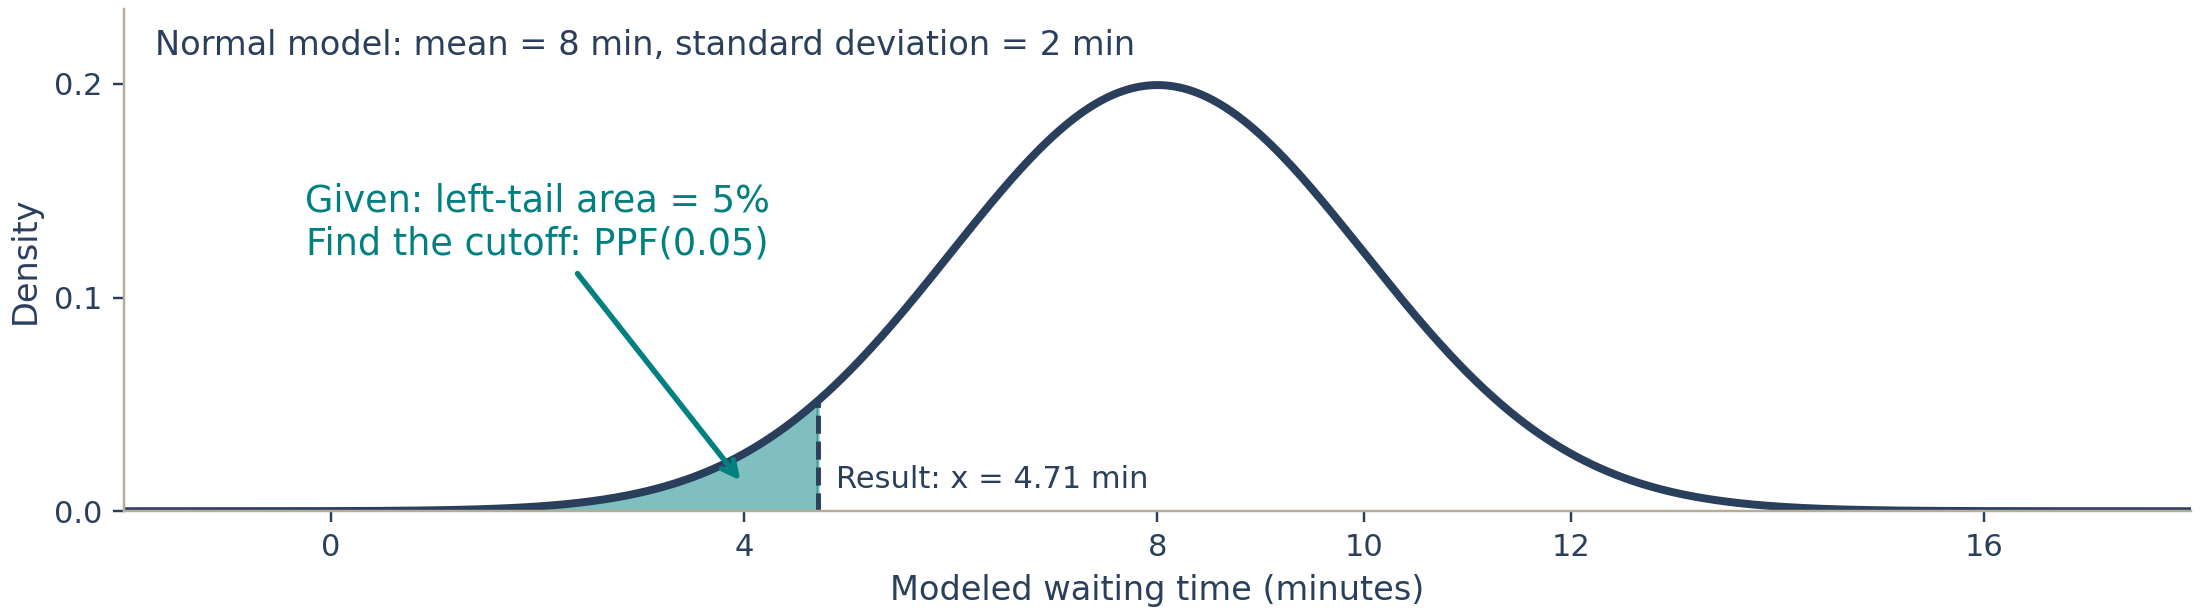
PPF means percent point function, the inverse CDF: probability → cutoff. Start with a shaded left-tail area of 5% and find the cutoff x. Here the normal model has mean 8 and standard deviation 2.
About 5% of modeled waiting times are at or below 4.71 minutes. Use 0.05, not 5.
Delivery-Time Service Target
A service-level agreement (SLA) is a promised service standard. Assume delivery times follow a normal model with mean 28 and standard deviation 6 minutes. How often is a 40-minute limit exceeded?
About 2.28% exceed 40 minutes; the modeled 95th percentile is 37.87 minutes. These are model estimates, not observed frequencies.
Observed Data versus a Probability Model
An observed proportion summarizes the sample. A normal CDF uses an assumed model. An observed sample quantile is not automatically the same as the model’s PPF.
times <= 40 creates a Boolean Series. Its .mean() counts True as 1 and False as 0: four of five times pass, so the observed fraction is 0.80. times.quantile(0.95) is a Series method estimating the sample’s 95th percentile, 42.40 minutes.
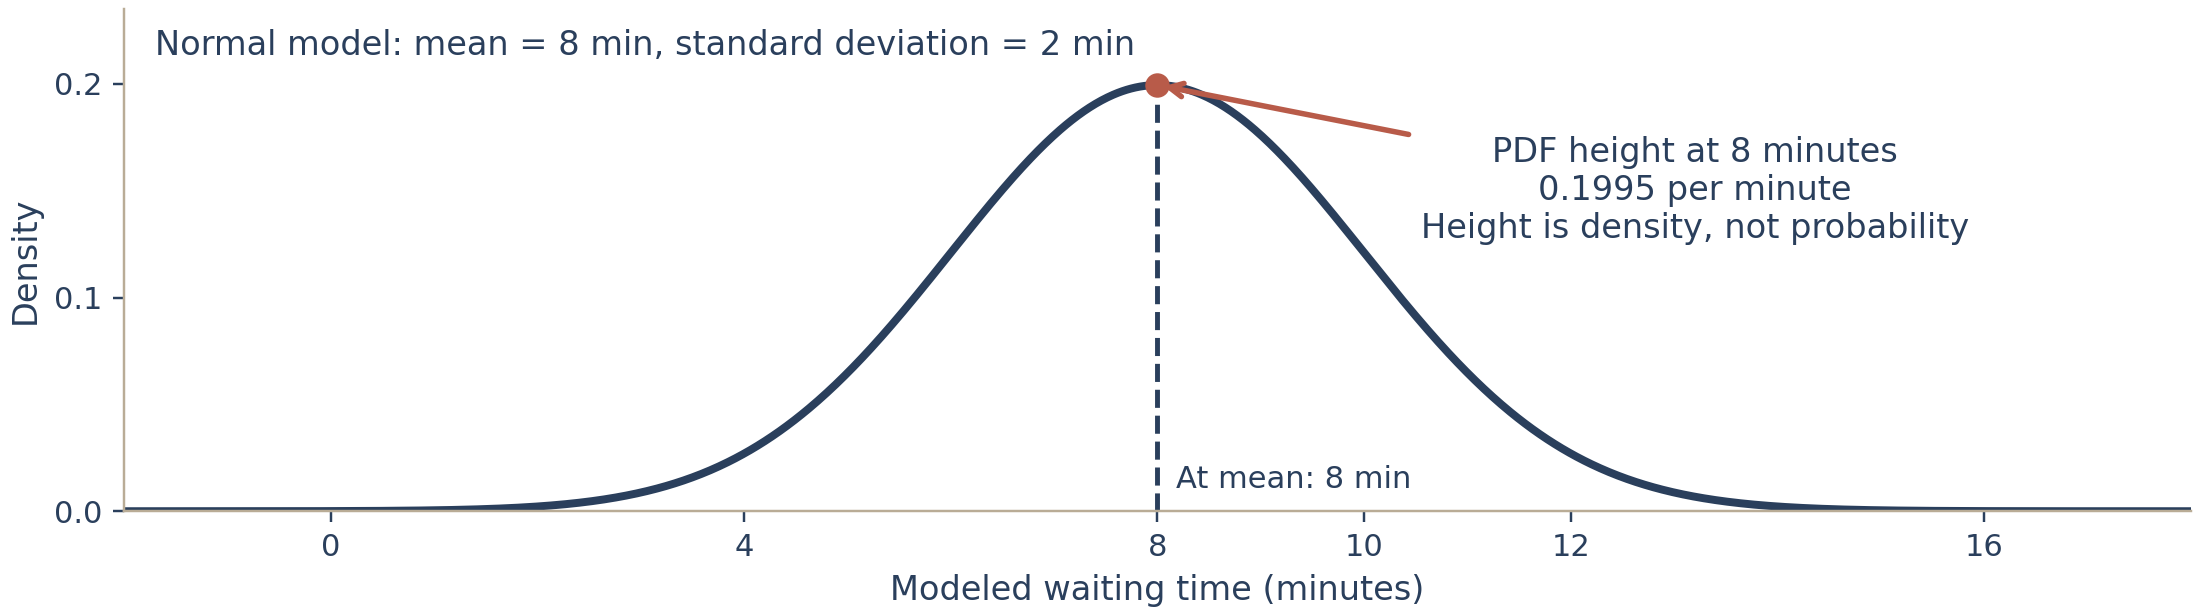
PDF: Density Is Not Probability
PDF is probability density, the height of a continuous distribution’s curve. Probability is area over an interval, not the height at a point.
The density is about 0.1995 per minute; the cumulative probability is 0.5. They measure different things.
In-Class Practice: A 90% Delivery Target
For mean 28 and standard deviation 6 minutes, find the 90th percentile. Check it by passing that cutoff into CDF. Explain the result in one sentence.
Checkpoint: about 35.69 minutes; the checked cumulative probability is 0.90.
Chapter Summary
Tool or concept
Main purpose
Read this example
List
Store, select, transform, filter
[p for p in prices if p >= 50]
Import
Make tools available under names
import numpy as np
NumPy array
Element-by-element calculations
counts * bills
Pandas Series
Label, select, summarize
revenue.loc["Wonton"]
Matplotlib
Communicate comparisons and patterns
plt.bar(dishes, revenue)
SciPy
Probabilities and model percentiles
stats.norm.cdf(...) / ppf(...)
Before trusting a result: check matching records, units, ddof, and model assumptions. Explain what the evidence supports. Revenue is not profit; association is not causation. Installation and import are different steps.